What does this mean? Isn’t the location header the redirect? Am I not following the redirect by requesting the location header url?
Maybe Google is observing this?
Google has gone so bad over the past few years. You only get like 8 results per page. I remember there was a time that I wonder how a site get reached if it ranked on the second page, when I can set the number of results to be 50. The censorship is also really bad, and google doesn't even tell you the results are censored, returning totally nonsense results while other search engines work normally.
I've been supporting Brave search which returns 20 results per page and has other features. It used to be not good a few years ago, but now the results are often better than google's.
So that will be figured out, making the whole exercise void. Google knows this. What is the real goal here?
and trying to protect your moat isn't automatically a bad thing. they clearly feel it's helping competition, so they're closing a hole. competition is good doesn't mean help your competitors.
- coming from someone who's been using fastmail as my personal for ~10 years because i don't want my emails to be backprop fodder
Also, the search results are total garbage now. Just give it a try and you see how useless the UI is, with AI results first, then tons of commercial go-to entries and only then a few links that are often also totally useless and irrelevant. Google optimised towards crap.
We really need to get rid of Google. Qwant results are now a bit better than before, but still not that great, and I hate that its default UI is a clone of Google. We need more alternatives. Let's get rid of Google once and for all - it has disappointed too many people now.
what? the Location header is the redirect, no?
Another "move" is suing companies like Autom, e.g., SerpApi
Google's Amended Complaint from their suit against SerpApi
https://ia801008.us.archive.org/25/items/gov.uscourts.cand.4...
"30. Copyright holders have authorized Google to implement access controls like SearchGuard for the content they license to Google, and in some cases insisted that Google do so. Googles authorization takes many forms. For example, Google has an agreement with a prominent licensing partner that holds copyrights to millions of works that it licenses Google to use in its Search results. Under the parties agreement, versions of which date back to 2017, Google is not only authorized, it is obligated to use commercially reasonable efforts to safeguard the licensed content against unauthorized third-party access. Other license agreements contain similar obligations. For example, another major content provider requires that Google ensure the content it licenses will not be available for download by third parties, thereby authorizing the implementation of technical access controls."
"31. In other cases, Googles authorization to implement access control measures like SearchGuard is part and parcel of the grant of licenses themselves, as Google and its licensors recognize that the value of the licensed rights would be undermined if others were free to access, take and resell the licensed content without restriction. For example, Google has a licensing agreement with Reddit, under which Reddit licenses Google to use the copyrighted content of both Reddit and its users in Search Services."
"32. Googles licensing partners have also expressly requested that Google prevent unauthorized access to licensed content. For example, when Reddit suspected that scrapers like SerpApi were accessing, taking, and reselling the content that Reddit had licensed to Google, it specifically asked Google to employ technical measures to prevent such unauthorized appropriation."
But this does not account for material that is not covered by the "license with a prominent licensing partner", its license with "another major content provider" or its agreement with Reddit
Google not only uses SearchGuard on SERPs containing links to the content covered by these licenses, it uses SearchGuard on _all_ SERPs
Google needs more than a "goto" update. It needs to update its terms to require _all_ copyright holders for the materials it has indexed and cached to give Google authorisation to use "technological protection measures" to deny access to certain members of the public, e.g., Google's perceived competitors including any Google user who "searches too fast"
Google has been encoding the target url for years.
I don't miss Google at all.
Goodbye you shit company.
&udm=web works fine for me, you can use a browser shortcut or extension to enforce it
Do any large ISPs use visit data to feed into a search index?
I’ve got something that will blow your mind. Google now has tracking analytics, for get this, your business’s phone number. Some “Adsense partner” convinced our web admin to install a little script which changes your phone number on your website so they track phone call enquires back to search engine leads / advertising spend.
Yeah no thanks, that was creepy as hell and had it rolled back ASAP. You’ve got to realise the power these tech companies hold over your business. Don’t show up in the search results, someone lists your business as closed in maps, a tracking phone number goes dead so they can’t call you, you might as well have shut up shop and ceased to exist.
Some of the things TV companies do will shock you too.
I recommend reading more than the headline
What is "that" you say wouldn't work?
The extension can work fine by requesting every goto link upfront. As far as your google searches go, this is just as private as before.
I would recommend you avoid judging a comment because of a metric it neither said nor implied.
The article also suggests that it cannot be decoded.
That no longer is possible, you must ask google.com for consent to visit the result link before seeing what the final target URL is.
And it can still prevent google from knowing which search results you click on, even though OP didn't mention that feature.
How do you figure? How else could it possibly work now?
There's even a reverse pointer query that can be made to get a domain to IP from a legacy ARPA TLD, although it isn't 100% robust.
We’ve had redirecting trackers like bit.ly for over a decade and the extension didn’t address it then.
You do a google search. The extension resolves every link on the page immediately via the goto urls. This doesn't leak any information to google because they obviously know which links they sent you. Now the links are resolved and you can copy and click them and get clean URLs, without sending any information about which ones you're copying or clicking.
In my second comment?
I was replying to a detailed explanation of the old mechanism that ended with "that is no longer possible", so I said "it doesn't need to use that exact mechanism" referring to the old mechanism.
It needs to update to the new way things work. But that's fine. An extension that performs the same task is still fully possible.
You get the results and they do have direct URLs. But then, if you do some things with the link, e.g. right click to open it in a new tab, it swaps the URL to the indirect one. The idea is that initially you see a normal link, with a normal URL which will be displayed correctly when you hover the mouse over it, but right before you click it, it's swapped for the indirect one.
So, they have been doing stuff like this for a while and it has been somewhat fluid, because the swapping can occur on different events and I have also seen it load with all the links pre-swapped to the indirect ones, sometimes.
So, yes, what you see may be different and you may get the indirect URLs swapped at different stages.
I ran the same search in an incognito window and it showed the /goto links.
Surely, the cost of serving search results to bots isn't that high
It's a lot of work to get the data to build an index. Why would they give it to everyone for free?
Similarly, Bell Labs was kind of required to release transistor for anyone to license - it was a part of social contract that they were allowed to maintain their monopoly in exchange for releasing certain parts of technology.
Alternatively, they could be split up and their indexing division made an independent company selling to anyone on a free market.
R&D has steep cost. Publishing it all gives your competitors an advantage.
The Internet has been dead for years and, after the Scrapocalypse, the small living remnants are behind a login wall.
Google can not provide you anything you couldn't find on either your local ZIM archive or the Media you consume.
e.g. I'm just now looking for the menu for a local restaurant. "restaurantname menu" in Kagi (Google would presumably be similar) returns a link to the menu as the first result in about a second. Or "restaurantname menu !" goes directly to the menu in about a second.
Meanwhile, searching "restaurantname menu" in chatgpt takes about 5 seconds to return an embedded map from mapbox showing the location of the restaurant. If I click the restaurant pin on the map, there's no menu link, the 667 reviews have no link or way to view, and the restaurant description literally says "I don't have enough information to identify which local business <restaurantname> refers to."
Below the map there's some text: "If you mean <restaurantname> in <place>, here’s the current menu. <restaurantname>". The <restaurantname> link just opens the same card as clicking the pin on the map.
After that there's a bullet point list of the menu that ommits a ton of detail and options.
After that there's finally a link... that I can click to open up a popup at the bottom of the page with an actual link to the menu.
This was literally the first thing that popped into my head, I didn't have to put any effort into finding a query where chatgpt falls on its face.
If you're trying to fight scrapers on a small site, delay links can only flatten bursts. If bots can only scrape at human speed per IP, they can just scrape 100x as many sites at the same time. Once every bot operator does that, total traffic will return to the original level.
Nothing good ever comes from businesses desperately trying to protect their moats rather than making their products better so they don't need to.
In reward for making Google Search materially worse in every way except ad revenue, he failed up again and was promoted to a cushy do-nothing role.
Everything wrong with the tech industry, embodied in a single person.
> promoted to a cushy do-nothing role
The people who this happens to are not perceived as successes. Everyone knows they are gentle firings.
I genuinely forget I’m not using Google until I come across articles like this
I guess that the web chat can have a search skill to remove the prose and give only links, plus maybe an excerpt of each result
Its not because chatgpt is so superior. Its just because google search is dogshit.
They work on killing the web as we knew it and I fear its kinda working.
Streaming services already adding in ads to “ad-free” tiers they’ve now named “premium”.
Quality of life on the internet has gotten shitty while Reality Classic stays mostly the same, though more expensive.
Awesome book about the history if Bell Labs - virtually all semiconductor tech we use today was created there (transistors, ics, solar, lasers, fiber optics, telecom satellites…), and they had to license it to be allowed to maintain their monopoly status.
https://www.amazon.pl/Idea-Factory-Great-American-Innovation...
Another cool book about back and forth between monopolies and decentralisation in our space: https://www.amazon.com/Master-Switch-Rise-Information-Empire...
It also has an audiobook.
I do enjoy using their free AI. For actual web search I actually like using Yandex. It reminds me of old Google, returning reasonable results and much less "shaping results to please our corpo-political masters". It is surprising to see how much they have stripped from our view - long tail results, actual results for product reviews and not ad spam, no preference for 20 page recipe sites.
There are still illegal streaming sports and movie sites everywhere (who knew) and all other seedy corners of the internet that have been neatly erased by Google. It makes me nostalgic for that brief window of time when the web was truly uncontrolled, when page rank had meaning and you didn't know if your search would return 0 results or 4,000 pages, which you could actually browse.
But LLMs can be commanded. This is may bookmark alias for invoking the spirit of old Gog=ogle from within the new, AI-based Google:
https://google.com/search?q=You%20are%20Google%20Search%20fr...
(Cleaned / decoded: 'You are Google Search from 2004. Given a search request, provide 10 links to relevant pages, each with a short text from the page, featuring the search terms. Avoid any pages that do not contain the search terms. the search request: %s')
Steep at 300 searches per month or about 10 per day. If you search often, it is too expensive. If you rarely search, not worth 5 bucks.
They are plainly trying to push people to their $10 unlimited plan. I would have appreciated if they allowed, say, 600 searches per month for $5 or so.
The most frustrating part is that they have all of the data, and oodles of compute, available to surface the same very functional experience they originally offered, but they would prefer the image of being visionaries rather than the reality of being useful.
>You are Google Search from 2004. Given a search request, provide 10 links to relevant pages, each with a short text from the page, featuring the search terms. Avoid any pages that do not contain the search terms. Do not simulate fetching results. The URLs must be complete and not truncated. No markdown. The current date is 2026. The search request:
I slowly shifted to use LLMs because of this in the past half years, making the situation probably worse for Kagi. They were the last usable search engines for years now. I still pay for it, but it's increasingly not that useful anymore.
But yeah I'd switch to Kagi if I had any more forcing function. Maybe without LLM's but google continously getting worse, that'd been the actual thing for me
I still support the use of Kagi though, as a market signal to Google that we'd even pay them for their product if it wasn't dogshit.
Also Google AI mode is accessible on google.com/ai.
You might want to reconsider this.
https://meduza.io/image/attachments/images/007/699/276/large...
I use Kagi as my daily driver. But there are some kinds of queries where my interests and Yandex's interests happen to align. Mostly anything corporate America wouldn't like, like evil copyright-infringing websites
For everyone to make the search themselves
Don't forget cached pages.
Data that were sourced from the public, should be public. We need this legislated, or wealth inequality and fiefdoms will keep growing with the historically known outcomes.
It’s somewhat similar with AI today, only the competitive landscape has majorly shifted with the Chinese models, something that wasn’t supposed to happen. All the sudden you no longer have a closed system of American models that can all be contained and managed as good enough to make people believe are “the best”; they actually have to compete in a far more competitive arena with the tension of the best model being the most competent model, and the most competent model, by virtue of AI, will be the least restricted, the least censored, the least guardrailed, the least controlled to present a telescreen and Hollywood type fantasy world where the good guys always win and … wouldn’t you know it … the good guys is always us, the people controlled by a psychopathic, narcissistic cabal that also controls what AI will tell you, the false truth.
I refuse to use a search engine that sees me as cattle to be steered towards “preferred” information sources. I specifically enjoy reading fringe material and will continue to seek and find it, thank you very much.
This is such a strange position to take. Apple doesnt allow all sorts of apps on the appstore, but that is never said as "Apple is erasing illegal streaming". Google is simply not showing the results. They are not taking down, or banning, or doing anything to the websites.
Because they are not "erasing" anything, they are refusing to provide a platform that enables the direct (app whose intended purpose is) delivery of illegal content to you.
The difference being one will not facilitate the activity, while the other, is actively suppressing it. And thats what is meant by erased.
Your question in other comment If I ask Siri to give me a link to illegal streaming site and if it refuses, then that would be the better comparison. Then we could say "other seedy corners of the internet that have been neatly erased by [Siri]"
It hasn’t replaced Kagi as my daily driver but the UX is fun.
It's really not free. You're paying with your data.
Google's strong position in AI gives them bragging right to attract more companies and get them to actually pay, subsidizing your use. It also lowers competitors position as you're not touching them while we're on Gemini. It also fortifies their position in the future ad market.
Being second or third in AI usage is worth a lot, one's private data matters very little in comparison.
It's now possible to put a complex spin/bias on whatever the system shows (or whatever it chooses to bury) in a really easy and scalable way.
Ex: Dairy Association pays, and suddenly results about bones are just a bit more likely to show something about the importance of calcium that many people get from milk. Fraternal Order of Police gets involved, and now "shot by police" everywhere gradually morphs into "was in an officer-involved shooting".
... And of course "Google making it harder to see URLs" becomes "Google taking bold steps against evil scrapers."
I get it, but at 9–10% error rate, you’re basically gambling with the results.
Source: https://www.nytimes.com/2026/04/07/technology/google-ai-over...
Asking this as a geeky end-user from Estonia -- I wonder if I would be considered "suspicios" by local internet service providers, our govt/police etc if I did a lot of searching via Yandex instead of e.g. Google these days.
(For us in Estonia, I suppose "everything with possible Russian ties" seems suspicious these days, unfortunately with a reason. As a side effect, this also creates a hesitation to look into interesting projects like ReactOS, the old-dos.ru repository, etc. Russia, obviously, inhabits lots of extremely talented coders who still have the skills and mindset to push older hardware to its limits, actually still write stuff in assembly for that, use the reviving DOS distros, etc -- lots of very interesting, creative coding done there, I guess. But, I hesitate visiting their webpages due to Putin's aggression in Ukraine, them being pro-Putin, and possible spying related to all this. It's a sad state of things actually. Sort of like a loss of computer-cultural ties.)
Just like Russia doesn’t care about online criminals being located within their borders - as long as they target outside.
While this may be true to some extent of all the countries, Russia is the one to be clearly against Estonia, Baltics and eastern europeans.
https://github.com/rumca-js/Internet-Places-Database
I hate the very idea that destination location is opaque, and user can't verify if you are funneled toward malvertizing.
I hate even base64 encoded links in the results.
As long as you don't search anything related to Russia itself, or to Russian interests elsewhere (like their invasion of Ukraine). Then it's very heavily biased, priority is given to state ran propaganda mills, independent media is hidden from results, etc.
And before anyone starts thinking about whatabouting, Yandex are based in a country where journalists are openly and publicly assasinated to intimadate. It would be delusional to expect any sort of press and related (like search engine or aggregation) freedom, or to try to compare this to anything in any other developed country.
A Soviet citizen and an American are sitting next to each other on a commercial flight.
The American turns to the Russian and says, "I have to hand it to you — your state propaganda is very impressive. You really know how to shape what people think."
The Soviet smiles, nods, and replies, "Thank you, but it's really nothing compared to American propaganda."
The American looks shocked and says, "What are you talking about? We don't have any propaganda in America."
The Soviet smiles again and says, "Exactly"
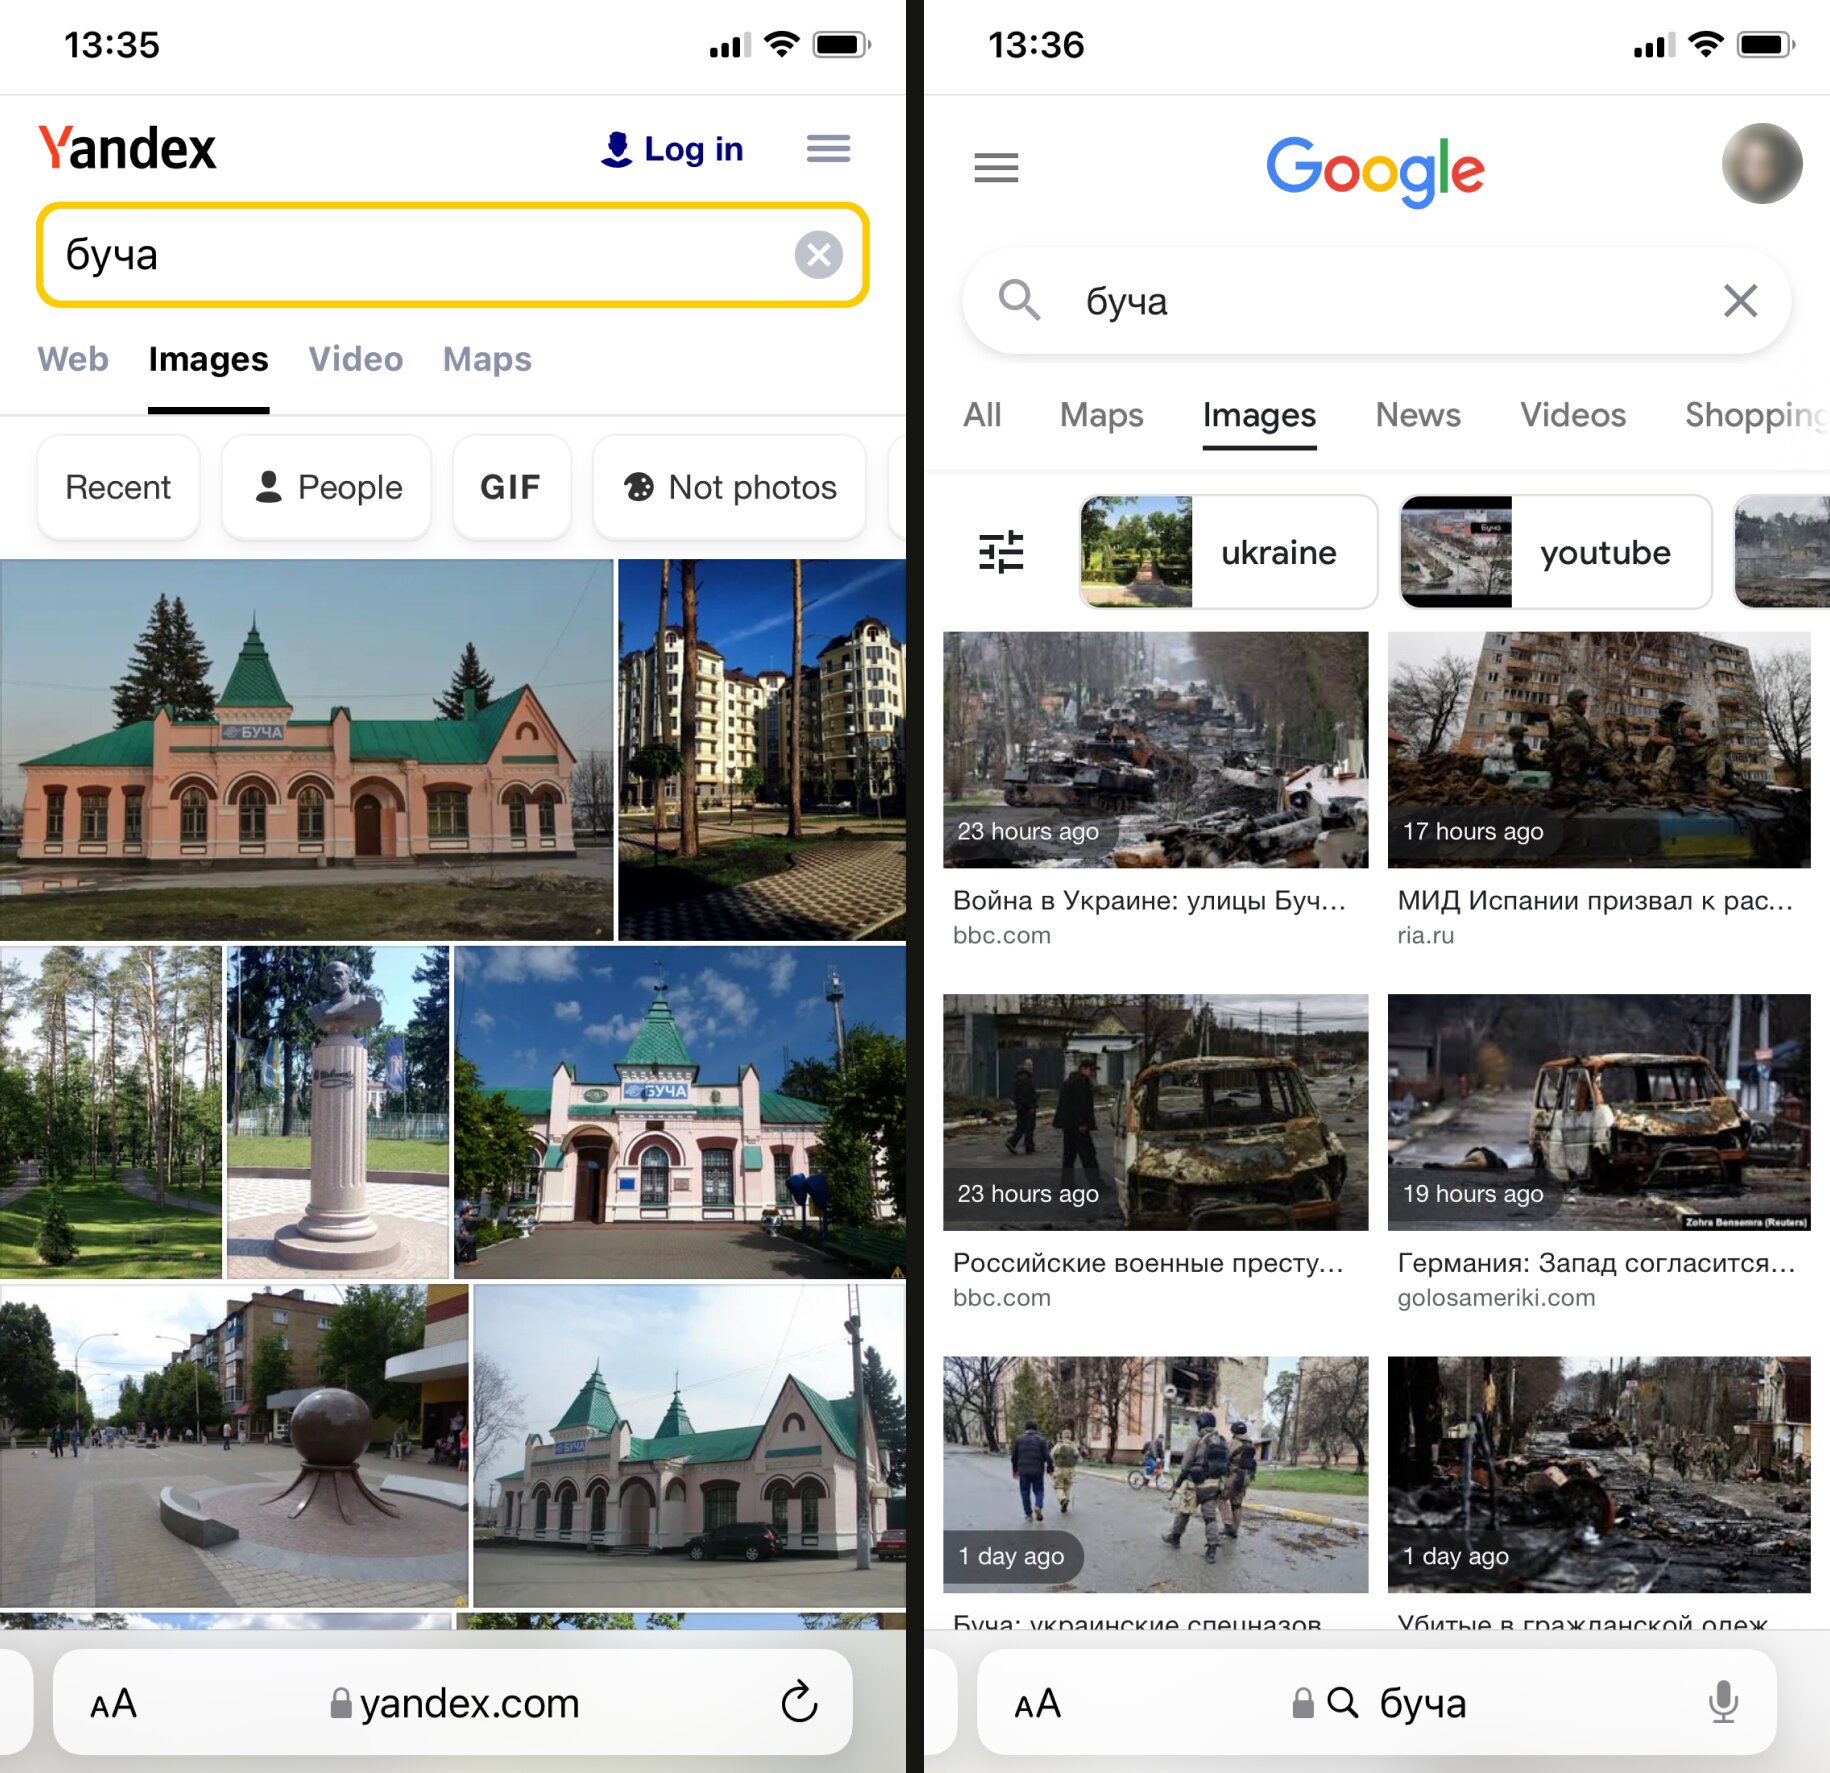
I then picked "bucha" as the query most likely the be affected by propaganda and censorship. In yandex.ru, there are propaganda outfits in the result (something called ruwiki.ru comes third), most links are of fairly direct accounts of the massacre by independent media. The AI summary says the town was "occupied" by the Russian army and "liberated" by the Ukrainian one and "После отступления российских войск в городе были обнаружены многочисленные свидетельства массовых убийств мирных жителей." On yandex.com on the other hand, the first page of results does look fairly propagandistic, including "globalresearch.ca" and "donbass-insider.com", which seem like propaganda outfits. But it also does include accounts from novayagazeta, al Jazeera a video of killings from Radio Free Europe.
While they do put either own propaganda, neither Western, nor Ukraininan nor independent media is not hidden from the results and it's not visibly de-prioritized.
Of course, I wouldn't discount the possibility that the results would look quite different from Russian territory. And, if anything, half the reason why Russian propaganda is so effective is that its self-aware and capable of subtlety when needed. "Fuck you if you can't handle the truth, this version of Biden is the best version ever." would never happen there. Unlike Scarborough, Soloviev knows exactly what he is.
Open and constant suppression of information is not the regime's usual strategy in information space (though, they'd ratchet up the level of control when they deem it necessary), which is why I knew the claims here wouldn't stand up to scrutiny.
Thankfully Gary Webb is here with us today to laugh at this
So how is that AI slop garbage useful? It often lies, aka "hallucinates". And I operate within this Google-controlled auto-spammed text of lies when I use its horrible AI. The last thing I want to do is make Google even more powerful; at the least now with Google search being so crap, alternatives would be well desired, but oddly enough I also get crap results using e. g. DDG, so I think in part the whole www stack must have become more crap too, quality-wise.
I actually don't see it as there are extensions that eliminate this slop spam, but I never found it useful for anything. Other than waste my time, back when I still saw it. Thankfully I no longer see that AI slop spam due to these extensions.
Google is making it harder for people to game the index, working in your favor.
I failed to gain traction on the problem, because to me the very idea of doing such a thing was too reprehensible to seriously consider. It broke an unwritten contract between the company and the user's expectation of how websites worked. You expect to be able to do things like right-click a link and copy the authentic URL, or hover to see where it wants to take you. The notion of obfuscating the link beyond easy recognition and polluting it with tracking markers felt misleading and, well, evil. A move that would mainly only benefit Google, and not it's users. I (quite mistakenly) presumed this opinion would be obvious and self-evident to anyone who spent enough time around the early web to understand its norms.
I explored other ways of achieving the goal, but it clearly wasn't the answer the interviewer sought.
I'm more seasoned now, and experienced enough to say with confidence the approach was wrong. This may seem like a small thing, but a series of misteps and chronic failure to adequately advocate for users is what has led us to the toxic waste dump that so much of the Internet has become today.
I'm really glad to have fresh alternatives (like Kagi), and can't wait for the cultural zeitgeist among developers to swing back around to valuing users as human beings and living up to the trust they place in us.
The base64 data appears to consist of a very basic protobuf structure, containing a long string of bytes in field 2 which presumably identify the URL.
Sometimes, these redirect URLs take a perceivable amount of time to load, which is very irritating.
For many years, I had my filtering proxy rewrite the URLs in the way mentioned in the article.
Almost exactly a year ago, Google stopped working without JS. I stopped using Google.
Now they're upping the game, and as the article (which is a bit of marketing itself) admits, those who have the resources can still blast through these obstacles while those who don't are locked out.
Since the article brings up "AI scrapers", I'll just point it out as being the latest scare-tactic for coercing people to give up the privacy, anonymity, and (browser) freedom of an open interoperable Internet.
While typing this out I remembered https://en.wikipedia.org/wiki/Google_Search_Appliance which I never personally used but shows feasibility for the idea. I'm pretty sure one of the newly-announced Macbooks is more than up to the task of matching GSA's offering.
I somehow found Mojeek and settled on it. I had never heard of them. Unlike Kagi, their business model is ads (so they hold no particular moral high ground). But they have a cheap, working paid API.
What I was astonished by is the quality of the results. For my uses, it's undistinguishable from Google. The conventional wisdom is that web search is a Google-sized problem. How did those obscure Brits pull it off?
Also, there is now a use case for paid search APIs - LLMs and agents - that essentially didn’t exist a few years ago. Not sure why Google hasn’t leaned more into this, but probably a combination of Gemini and Ads interests have combined to view their search index as an increasingly valuable asset, when if anything it might be corrupted already by these interests and therefore be less valuable.
DDG's search results have been poorer recently than they used to — I often see completely unrelated results (to the point of my saying "Why in the world did that come back as a search result??!?") starting from page 2. And yet, I still use them, simply because they aren't Google.
Google have such a (justified) bad reputation that whatever they do, people assume it’s entishification. I don’t believed it is on that matter.
The reported behavior exists, does it not?
Anecdata: I've observed this behavior for several weeks already as a regular user without a Google account and there are countless comments from regular users reporting the same behavior.
Now, I need to click on the link and access the page to “unfurl” the URL so that I can paste a nice, human-parseable URL into a chat.
Google may have just made me actively want to switch away from it.
I wonder if this would also work on other sites getting hammered with bots. Allow each anonymous user 1 "real" page load then turn the rest into encrypted links that the web server can decrypt. If a session cookie with reputation exists, stop screwing with the links.
Kind of annoying but it'd allow tracking if the same agent/bot is churning through IPs/User Agents.
Kagi has a pile of features I’m not getting the benefit of too, I’m sure, because it’s just-search, mostly, to me.
That’s fine; I know what I’m supporting, and I know that I’m the customer and not the product.
- usually better than Google
- has actually useful features (smush BS listicle articles together, weight/block sites)
- if you don’t use any searches that month, they’ll just straight up refund the month subscription automatically
- doesn’t annoy me constantly
This text appears on this page https://www.autom.dev/blog/google-search-goto-links
> The real URL is in the Location header on /goto. Request that URL. Do not follow the redirect.
And this text appears on this page https://www.autom.dev/blog/google-goto-url-fix
> Do not follow the redirect. Read Location.
That's what a redirect is, reading the value of the location header and then requesting it. How do you not follow the redirect by reading the location header? Once you've made the request to the /goto url, with GET or HEAD, to get the location header, google knows you're interested in whatever it is putting in the location header and can assume you're going to go there, if you're letting the User Agent (curl or the browser) go there for you or not.
And their fix here - they just resolve all the urls- which I suppose could make the service slightly more expensive? But otherwise isn't that what every similar provider/ crawler etc will do and this change will only hurt users?
Brave has its own independent index which is cool.
https://kagifeedback.org/d/5445-reconsider-yandex-integratio...
Uruky is the way. 2x cheaper also.
Next i'll do is to implement tavilly, exa, tinyfish etc. as search engines for searxng. No agents, no mcp, just their search api endpoint.
Removing this made google search horrible to use. I often use command+f to quickly identify relevant search results, but doing it on 10 results at a time is so laborious that I just don't bother using Google search, resulting in less searches and use of other tools instead.
I had some fun in my grad days building a private information retrieval (PIR) scheme so the shim server can do its job without knowing which link you clicked: https://github.com/pncnmnp/shimmey
also this page doesnt have a submit button and pressing enter doesnt submit the form either:
Which is an elaborate way to say: you don't have to live like this.
I think it is both monopolization and cheap money. Something in economy favors big companies and disfavors competition.
Cheap money means that a selected company can run at loss, kill competition and then enshittify to start earning. By that time it is too late and too easy to buy or destroy smaller competing company. And you get access to funding by being charming to VC, by being the kind of sociopath they like to see.
Capitalism works when there is a competition. Not when there is an oligarchy.
Great. On top of my on-going battle with Windows + Firefox + DNS/TLS resolution sometimes stalling for seconds at a time, another few second server-side stall is introduced.
I swear that every day modern computing scenarios get slower and slower instead of snappier and snappier.
Have you tried disabling HTTP/2?
Now you can't load the page and can't easily (using only the browser UI) get a link to paste into archive.org or archive.is to read the page.
I do a bunch of work in remote areas with low-ping/low-bandwidth networks. The “hold on a skimmer while we round trip to Google” dark pattern makes the service unusable for me when I’m on-location.
The situation seems to vary from result to result even on the same page of the same search - at least on the test search I just did. You can figure out what happening to an extent but this very inconsistency seems to speak to a dystopian quality to today's information gatekeepers.
[1] Example. https://www.google.com/url?sa=t&source=web&rct=j&opi=8997844...
https://www.google.com/search?client=firefox-b-1-m&q=direct%...
I imagine it'd take quite a bit of shape for the index and be hard to keep it up to date unless you restrict what it indexes.
SearXNG is more of a metasearch, the dude who wrote it pops in on here and is working on a cool sounding project that is more like a local personal search engine, I forget the name, but I've been meaning to check it out.
There is also Common Crawl.
https://docs.openwebui.com/features/chat-conversations/web-s...
Doable if you had couple million dollars to burn. Cheaper than private jets new.
I imagine if set some constraints you could get index size down quite a bit but I still suspect it'd be hard keeping up with content churn.
Edit: Looks like enwiki bz2 is coming in around 46Gi which isn't too bad considering the amount of content it contains.
It’s instant, works offline, auto-updates, and includes all the websites you listed, and allows for custom ones too.
Looking now, I've just noticed they no longer give a count of results.
For example, DST starts and ends on different dates in the UK and the US. Which dates should google return when someone from either country searches for just "DST end date?" Someone lives in Orange County and searches for "Orange County Sheriffs," which one of the eight Orange Counties should google return?
These are both examples where a localized — not even customized, just localized based on IP addresses — search results will easily help reduce headaches.
It's when two people in the same neighborhood got different results for the same search that I said "wait a minute, they're personalizing search results now for ad-targeting purposes" and ditched them. The potential for them to deliberately hide things from you was too great.
If you could find what you want, how would they ever sell you what they want you to buy? And I'm not just talking merchandise, though that too. Your political narratives, your values, opinions, everything. And everyone likes it so much they just sit there scrolling and swiping and tapping.
Yes, the fact that they could do it does not prove that they were doing it, not right away. I ditched them as soon as I found out that they could do it, because I was absolutely certain that eventually, they would end up doing it. And I wanted neutral search results, not biased ones, even ones biased towards my own point of view.
I would love a search that lets me ban results from certain sites. I don't like search that's showing skewed results for reasons I don't know or control.
Now, all Google search results appear to go back to Google.
2. It is non-bypassable tracking of every single click.
3. It does not allow you to inspect the URL to see where it goes to before visiting.
4. It breaks the feedback signal of extensions which redirect sites. E.g. Fandom wikis are shit so I have them redirected to equivalent much better wikis like. But now any such redirection has to be done post-click tracking meaning Google still believes I want to see the Fandom site.
5. It breaks extensions which hide certain shit search results based on URL.
Also, though more niche, it would make archived search result pages (e.g. on the Wayback Machine) less useful.
This could be, for example, step one in the return of AMP, but with a new twist. Where google conveniently returns the content of your website, without directly sending the user to your website. With whatever changes it chooses to make.
Users still have your articles full url in their browser when they read it.
Well, I hope ultimately this will lead to even more user loss for them. Fortunately, I myself don't have to suffer due to it, because I degooglified my life.
Google being the cesspool it is, can serve whichever (ad laden) domain that fits their own interests the best.
This is yet another move to remove power from the users.
Google has previously tried to prevent scraping of search results using legal means, but courts correctly think that scraping of Google's search results should be legal, just as Google's scraping of the whole Internet is legal. This is Google's reaction to that.
In effect, they’re removing attribution from the content they quote from other people’s websites. It would be interesting to see if courts object to that. It is one thing to crawl other people’s websites and display snippets of their work as your search results when each result is properly and transparently attributed. But if the text is quoted and the source is not there alongside it in plaintext, replaced only by a vague promise that, if you ask, we may or may not tell you where this piece of content is from, that is a very different deal.
Think about it: if you want to set up something like jina.ai you need to build your own index or piggyback on Google. My guess is they use residential proxies to fire requests to Google then scrape the URLs.
Opaque URLs now give Google another gateway to detect circumvention of their anti-bot controls, helping them monetise their search index rather than allowing providers like jina.ai to succeed.
As a regular user, it's a minor annoyance.
As others have elaborated, the reasons are so they can track who you are and sell your profile advertising.
What? Like they weren’t doing this before? Obviously Google’s telemetry is tracking every link you click regardless; there’s no extra tracking benefit to this.
The reason they’re doing this seems to be to stop competitors from scraping their search results.
Kagi can be "better" than Google (for some very narrow definitions of better) because they basically don't have to think about SEO at all. They're small enough that nobody does SEO against Kagi. If their algorithm is sufficiently different that typical Google tactics don't work on it, even if it's much more naive because of that, Kagi wins.
https://developers.google.com/search/blog/2020/11/timing-for...
You can't. Google will ignore robots.txt in some cases (e.g. "The REP isn't applicable to Google's crawlers that are controlled by users (for example, feed subscriptions), or crawlers that are used to increase user safety (for example, malware analysis)").
robots.txt is just a suggestion that Google loosely follows.
https://developers.google.com/crawling/docs/robots-txt/robot...
It is also a measure of how enshittified and exploitative thing have become, that we look towards litigious copyright holders for assistance...
It definitely is. The extension-based redirect in Safari is also unreliable. Furthermore, many of my searches (and others', apparently) unexplainably defaulted to Groningen in the Netherlands, even though I'm nowhere near the place.
I ended up not renewing my annual subscription. Since then, I vibecoded a small userscript that replicates domain ranking for DuckDuckGo – plus DDG already lets you turn off ads natively.
Also, if you try to search for "download Chrome" (in Russian) then the first result in Yandex leads to a scammy website: https://ibb.co/HDRJGgZD The real link is the second one, but I remember a year ago or so there was no official link at all. You can also note that official link to Google has a grey text saying: "the owner of the resource violates Russian law" (Yandex is required to show this notification).
Yandex has also been caught "accidentally" removing the site of Ekaterina Duntsova who was planning to nominate for presidential election in 2024, and showed fake/phishing sites instead.
So, Yandex is only good for searching torrents/pirated movies (which you can watch on rutube) and nothing more.
Re-read the comment you replied to, and the one above
> Yandex said its image algorithm normally gave low priority to very recent material for a bare place-name query, because historically someone searching a city name was usually looking for ordinary pictures of the city.
That's a lie. I was unable to force it to show me pictures of the massacre no matter which search terms I tried to use. And that was many many days after the fact. Like, weeks.
Even if they're only a layer around Bing, having your Bing searches coming from DDG's IP addresses rather than from your own IP address almost certainly makes it harder for Bing to track you, since your searches are being pooled with everyone else who uses DDG. Naturally, Google will track you, your computer, your phone, and would even track your dog and your Roomba if they could figure out how.
It's good for your mental health to be exposed to arguments you disagree with. Many times they will be bad arguments and you can dismiss them, but it's good to know what the people who disagree with you actually believe. And sometimes, just sometimes, you might see something that makes you realize that it's your own worldview that was mistaken, and adjust your worldview to better fit reality. If your search results only show you echo-chamber results that already agree with yours, you'll rarely learn the areas where you were mistaken. (And nearly everyone is mistaken about some things; the person who is right about everything is a rare creature indeed, and you should never gamble that you're that person).
If it only gives you the one you already know about, it's a useless tool.
I won't be first, second or third in the AI race. I'm not even participating in that race. I don't care who wins. However my private data are mine and I do care about them.
It's Google and those other companies that may not care about my privacy, because the AI race is more important to them.
If AI is going to cost too much, I will use a cheaper one (Ferrari or FIAT?) or if every AI will cost too much, no AI all and there will be billions of people like me.
Parent was pointing at the value exchange, and I argued that users' privacy is not the currency Google deals with.
Your privacy can be valuable to you, it just has no weight on the exchange.
However when I run an adblocker and Blockada on Android, when I use alternatives to the YouTube app (and Google is technologically fighting them) when I don't log into Google, then those exchanges happen with very little of the currency Google is interested in.
what does this even mean
that's the most innocent example from the top of my head. There probably are many more serious censorship issues
https://hal.science/hal-03217497
https://euvsdisinfo.eu/yandex-from-tech-innovation-to-inform...
https://pmc.ncbi.nlm.nih.gov/articles/PMC10130930/
https://misinforeview.hks.harvard.edu/article/a-story-of-non...
And then there is the very handy assistant, that I can jump into using follow-up questions to the quick AI queries one can choose to use or not to use by appending a "?". Again a simple idea, which empowers the user.
Google's actual search results are a waste of time visiting, both for the mindless CEO content and the ad-laden, analytics-happy, javascript-heavy websites.
So I tend to use the AI overview. But plugging myself into the all-seeing corporate oracle, that grew on all the web's content, and now seeks to supplant it seems unseemly.
It's just sad that kagi will likely only be a fringe thing, and google will continue to promote these foul, foul, mindless websites and then supplant them with its AI.
Actually sorry, it's beyond absurd.
So is Fox News. That's the OVERT propaganda.
And the Soviet has no conception of what that is - in his fantasy the US state, and all the "satellites" are controlled by one single narrative thread like in the USSR.
I think that's the actual punchline: he doesn't know what free speech is, so he thinks he's the one with the insight over the American.
The sad thing is that still echoes today in Russia, they tolerate a corrupt regime and cope saying "the others are also corrupt and filled with propaganda, so this is ok, at least we know, but they don't" not realizing there's no free speech.
(I dont agree to this but ...) using your argument of " If you use a X as your eyes to see what exists “on the internet” .. " - we should all be mad at Apple. I use iPhone as the primary device to access apps, and they not just hides but actively ban and cut whole swathes of developers.
If I ask Siri to give me a link to illegal streaming site and if it refuses, is that cause for concern? I'd say no. Infact, I dont expect it to give me that and I get it. Same for Google Search in my humble opinion.
Why would it be stronger? Google has a near-monopoly on search.
> If I ask Siri to give me a link to illegal streaming site and if it refuses, is that cause for concern?
Yes, because you cannot replace Siri on a device you own.
What does that mean? I use kagi, ddg etc. Nobody is forcing anyone to use Google.
Woudl you say HackerNews has a monopoly on tech chatter? Sure seems dominant, but nobody is forcing anyone to use HN. You can use lobsters, or reddit or whatever.
Your description is vague enough to encompass every system that I’m aware of, from feudalism, through to mercantilism, communism, and capitalism. It may best fit communism and feudalism, both of which are most notable for fostering negative-value-added firms.
Agreed. And webrings still exist in certain corners of the internet.
> the oracle currently relies on humans publishing new information
New? When I ask it how to do something with a piece of software it's perfectly capable of answering me by means of direct interrogation of the source code.
I'll grant you that it owes ~all of its knowledge of the world at large to having been bootstrapped using the more or less complete body of humanity's published works. However I think that was merely the quickest path to bootstrap it as opposed to the only one.
It's the only recommended Chromium browser by Privacy Guides. https://www.privacyguides.org/en/desktop-browsers/#brave
Ok, maybe not the war *with a neighbor* (yet), but US has an open war with Iran (and has bombed a few other countries recently also) and it also threathens to annex the neigbor to the north plus another island country.
Sure, americans might consider themselves to be "the good guys", but the rest of the world doesn't.
A uBlock Origin developer now confirms, regarding Google results click tracking:
It existed in a way or another, but it could be blocked. Now it can't.
https://old.reddit.com/r/uBlockOrigin/comments/1we7491/how_t...
Next time, please consider listening to people who know how the web works and avoid overconfidently parroting what Big Tech gatekeepers want you to think.
Thanks!
And btw about the result filtering the uBlock dev wants to do: of course this can still be done, if you preload all the goto links on the page and then inline the real URLs returned by the preload requests. Perhaps not easy to do as an extension but at a browser level (Brave?) totally possible. Though Google might then think your users are scrapers...
Linked below is an explanation which includes confirmation of that fact by a member of the uBlock Origin team.
It means exactly that: it has near-monopoly on search. On mobile the situation is close to to complete monopoly.
> Woudl you say HackerNews has a monopoly on tech chatter? Sure seems dominant, but nobody is forcing anyone to use HN.
Google literally pays Apple $20 billion a year to force people to use Google only. But that is quite beside the point. The definition of monopoly does not include "forces you to use it".
Would you say HackerNews is a monopoly? Any activity that the user has a choice to use something else cannot be a monopoly.
> Google literally pays Apple $20 billion a year to force people to use Google only
Apple pays TSMC $XXX billion dollars to get preferential treatment, but that doesnt make TSMC a monopoly or even Apple a monopoly.
PS: I do not understand why people keep using Google search, the results turned biased and mediocre.
Why are Google apologists flagging my other comments?
Firefox, Waterfox, Iceweasel, Icecat, Seamonkey, LibreWolf, Pale Moon, Mullvad, Tor Browser
Chromium, ungoogled-chromium, Google Chrome, Edge, Brave, Falkon, qutebrowser
Safari, GNOME Web, Konqueror
No difference.
I am 100% certain it has nothing to do with my browser.
This discussion is about search results pages with JavaScript enabled.
>And btw about the result filtering the uBlock dev wants to do
For a long time, uBlock Origin has kept up with blocking Google's click tracking out of the box with the default Privacy filter list (privacy.txt).
https://github.com/uBlockOrigin/uAssets/blob/master/filters/...
This means that all uBlock Origin users (even people with no Google account) would NOT be click-tracked, WITH JavaScript enabled.
You say "They own the JS on the page", so the topic of discussion here is simply whether users could block click tracking on the client side.
And until now, they could have: by installing uBlock Origin or any content blocker with a sane privacy list.
Now, they cannot.
I don't, but thanks for confidently assuming.
Sure not everyone benefitted from US but a ton of people/countries did and still do.
US never felt a need to build walls to prevent their citizens/allies from leaving. Russia and the others very much so.
With US the track record may be mixed, but a ton of countries from Europe and Asia benefitted tremendously. Russia otoh doesn’t have a concept of win-win, they tend to exploit even their closest allies, which anyone living in Baltics/East-Central Europe can tell you.
I'm from the border of central europe and balkans, I don't benefit at all, it just costs me money to pay for a van full of soldiers every time americans decide to occupy some country half the planet away.
Nonbombed countries - a ton, Ukraine for one, but the whole post-communist block.
>Our search results also include anonymized API calls to all major search result providers worldwide
There are a few other indexes that Kagi’s aggregator mixes in (such as Bing Search) but those haven’t been contributing much in terms of meaningful results. The sheer size of Google’s index still dwarfs all the others, including Bing Search.
So yes, Kagi doesn’t scrape but they pay SERP providers who do.
I believe they are building their own index but targeted towards useful results not included in the others
Advertisers are sold the idea that 1000 clicks/impression is X dollars. The average impression might be priced at 1000/X$.
But you are worth much more than that for two reasons.
- you are a person willing to pay 5$
- Google can sell a “collectivized” product. The same way that eg collective farmer crop insurance creates actual value.
and the third reason (as consequence of the second) they dont want people to think about: it gives them more opportunity to fudge the value by making it all very complicated.
The more money you're willing to pay to avoid ads the more you're worth to advertisers.
That's why tools like uBlock and YouTube morphe are the only answer, negotiating with terrorists never works.
And eventually when I want to buy something I research it and buy it and nobody had to pay anything to Google.
Natural next step of the ad lobby is obviously to pay the lobby to make it illegal to bypass the money making machine if they haven't done so yet. I don't doubt that capitalism still works, it just takes time to "boil the frogs" dead [enough] to stop them from buying such crappy products.
This is silly. The economy doesn't work if no one is willing to pay for goods. The content you're consuming won't be made if theres no market value to create it in the first place. Pirating is not a solution to our data privacy problem.
To anyone who didn’t find Kagi useful in the past, I strongly recommend you try it again, as they have made huge strides in usability and quality of surfaced data in just the past year…. Huge strides since even a few months ago too, with more adaptive curation, data labeling, and UI/UX
It's not. In addition to their own indexes the results include calls to "all major search result providers worldwide"[1].
There are independent search engines that only use their own index, like Mojeek[1]. Kagi is explicitly something like a search engine aggregator.
[1]: https://help.kagi.com/kagi/search-details/search-sources.htm... [2]: https://www.mojeek.com/
I too feel the yearly price of $108 for one person, $155 for two people and $216 for a family is expensive. Ok, maybe the family plan is cheaper if you can find five others to share it with.
When i do actually use it for search; it's amazing... assuming I've not already burnt my quota.
> OneLook scans 16,965,772 entries in 805 dictionaries. Use it to find definitions, related words, quotes, names, lyrics, colors, and more.
Also, super cool link, thanks for the share.
That's confidence in the product right there. I'd argue any subscription which won't do this is designed to exploit people who don't need or use a subscription.
And Google's ad revenue is likely more than that. Or, if it's not for every user, the ones who would opt out of ads are the ones who can pay. You're cannibalizing your highest value users.
That is interesting, which LLMs? Asking as someone paying monthly Claude subscription.
You can even choose a model for each turn.
Kagi is the stickiest digital subscription I have.
Kagi has limitations like not showing sites with ads which many people with ad blockers don't mind.
Most of the time I need to find out something, and in that case, Claude / Gemini / Grok / Perplexity / you name it work better. Most of my queries are technical by nature, not interesting for data mining on me personally.
But Kagi’s SERP API provider is going to have to adapt, I guess.
In other words, you owe me $1000 as a condition of reading this comment. Your options are to unread the comment, pay me $1000, or pay me nothing to incentivize me to charge a price you'll actually pay (likely $0.00 for comments but not for everything)
Basically it doesn't make any meaningful progress towards a better outcome. It just temporarily makes the content more enjoyable to you at the expense of the person who created it and maybe to you if you enjoyed it and wanted more.
Yes, but if you are so against ads that you spend $20 to not see ads (I am definitely in this group) and then see an ad for a "cool product" anyway, then that product is no longer cool. Any time something like this happens, I legitimately develop a grudge against that company and their products.
I might have bought that product before seeing the ad, but there is no chance of that after seeing the ad.
Before the ad, you didn't even know the product existed. Now you know it exists, making you infinitely more likely to buy it.
I'm likely old school here, but I never liked "paying for what I use" in the online world because it required revealing some personally identifying information (i.e. to make payment). My attitude is almost certainly irrelevant these days, with the scope of online tracking, sharing of data, and the near necessity of disclosing one's identity to sites other than one's ISP, but it was an attitude that was established in my mind nearly 30 years ago.
(I also don't trust the pay for privacy model. First of all, you can never assume that paying for something implies your data won't be sold. That was even true before the public Internet. Then, even with statements about privacy, you cannot assume that will be true in the future. If the company is sold, management changes, or the company decides the need/want additional revenues, that will change. And that assumes they don't use weasel words about what privacy means, or the ultimate "we reserve the right to changes this agreement at any time".)
Did those studies have any outliers that DID have a negative reaction to ads? I am 100% certain I'd react EXTREMELY negatively in a situation like that.
The same way I wanted to buy a Tesla and rented one a couple of times in the past. Now I would NEVER AGAIN even go into a Tesla. Fuck that company.