Ask HN: What are you working on? (September 2026) What are you working on? What have you been curious about lately? |
Ask HN: What are you working on? (September 2026) What are you working on? What have you been curious about lately? |
You can track what you’re reading, keep notes and reflections, see your reading stats, build out your bookshelf, and a bunch more. Over 4k monthly active users.
Been building it solo & adding features based on what readers ask for.
My last company (Courier, YC S19) had great inbound but we never were able to scale it. Ballad plans what I should write, drafts in my voice, publishes to my accounts, and handles attribution so it can feed that into what it writes next.
Right now, I'm mid-way through migrating the application off browser localStorage onto a proper JSON persistence layer. My first large solo project as a busy student.
I hope to make it better as I continue.
A way for for U.S. car owners to stay informed about the issues your car may experience that are communicated by car makers to dealerships.
I found those communications useful for my own car and wanted a better website that what the NHTSA provides and have been having a lot of fun building out the site.
I've paired with a psychologist and HR director from one of the best universities in Germany to leverage the fact AI has embedded within every human experience, personality types, shortcomings in recorded history among all languages, and all cultures, and we are trying to extract that knowledge and leverage it so we can analyze what makes you tick (for example being an introvert or extrovert to recharge your social battery) in every aspect, motivation, procrastination etc.
Analyzing solidly your profile in a sense those standard 'form' 1-5 tests can not capture.
Once that's done, we give you recommended activities to improve your weak points (perhaps asserting yourself a bit more if you tend to shy away).
The core things we are trying to solve is:
human coaches are limited by their own worldview and bias, we hope AI who has more knowledge to other human experiences can help you more.
Anonymity, we are full GDPR compliant with audited log table if any user access your records, we hope humans feel more at ease without the fear of being judged.
Accessibility, a single mother drowning with responsibilities doesn't have time or resources to evolve spiritually, we hope the accessibility and price point of our app solves this and helps people who can't hire coaches have a more meaningful life.
Most of all I want to use my skills to improve human lives, I've been working very hard on it.
We are near a beta launch, where it will be free for beta users, if you are interested please email at: martin.sejas@exara.ai
It has proven surprisingly resistant to AI so far - Astra can make a very quick prototype but upon review it had many defects. I have had to guide it very thoroughly to find all the random solver bugs (bad conditioning, formulation, bugs in openscvx which I had originally had the AI port to rust, etc.) preventing well-behaved solves. But I think (hope?) I have turned the corner on these.
This will enable some very interesting further experiments: full mission planning, Falcon-9-style ascent with split control, vehicle swarms, etc.
Also spent a good part of last month working on a little idea I have that is built on-top of XMPP.
I've also been wanting to pickup Gleam, hopefully this would be that week I finally fight through my ADHD to do so.
https://github.com/slyall/auckland-stop-display-simple
Some other projects doing similar stuff but I found they were hard to understand (and mostly used an old API that no longer exists) so I (well AI) made mine with small scripts and included curl examples.
Please let me know if you enjoy!
I’ve built two (successful) iterations and am now working on the third. They are all very minimal.
The main one works well and runs full time waiting for my next idea. The second targeted an open weights model and worked in limited cases.
Now I’m working on a more autonomous version. I give it only a goal and a strategy, it decides its own projects.
- When your agent is stuck on a bleeding edge issue, search Push Realm first for a solution. - If you find a solution, your agent can mark it as successful to help surface the solution to others (and hopefully save fruitlessly burning more tokens) - Can't find a solution? Post an open problem with your current investigation. Another agent may be able to solve the problem, and will have a head start thanks to your context - Solutions can be linked/edited/have addendum added by any agent, allowing complete, up-to-date solutions for a range of cutting edge issues
It's a CD tool for Kubernetes built on top of Flux and OpenKruise canary controller to bring a full-featured end to end delivery on Kubernetes over multiple environments in a declarative way without the pipelines.
I wanted to stop reinventing the wheel with pipeline engines every time I needed to deploy something. Every stage of the delivery is just a composable component (health checks, smoke tests, schedules, environment promotions, service dependencies).
I just released a new version recently that integrates with GitHub so one can track exactly what's deployed where and how far your change progressed.
https://gitsocial.org/ https://github.com/gitsocial-org/gitsocial
Rides Claude Code/Codex hooks and captures useful information, and injects it at need (like when there's an error) for other agents. It works across your team then at a global marketplace layer, so there's incentives for people to contribute.
We're in the process of benchmarking and we are aiming for 10% in token reductions. If any team is interested, we're accepting preliminary design partners and can get you started with the benefits.
Unfortunately, I'm not sure that being better is enough to compete, so I'm sitting on it for now.
We also have an official meeting once a month to do book club matchmaking in person.
I’m seeing near-100% root-cause accuracy on synthetic test data and am looking to validate that on real production workloads using OpenTelemetry tracing. If you’re open to chatting or experimenting, drop me a line! I’d also love to hear ideas or how we can improve observability.
My goal is to better understand the economics of AI and make something useful in the process.
(Coming soon: kWh prices and robot prices)
Mostly built with claude code with a dash of codex.
A recent, useful unlock in the process has been a daily CC routine to check the health of the 53 price collectors in the project.
All the travel apps out there are built for the instagram generation but dinosaurs like me still use TripIt for travel tracking and itinerary sharing. But its parsing hasn’t changed since Concur bought it 15 years (!) ago and I thought it would be nice to have LLMs read the cancellation minutiae for trips and put in a simple timeline for sharing.
Video proof of work for coding agents.
Agents upload a short recording of what they built, humans leave timestamped feedback, and the agent can retrieve that feedback and iterate.
Basically, instead of an agent telling you "done", it can show and you have a nice way to share the resulting videos in PR, on Slack, with your teammates etc.
Meanwhile, Daniel Greene's dodgy whiteboard video has a million views. Don't mind me as I eat these sour grapes...
The "official" syntaxis is
https://yups.io/?url=https://twitter.com/Wikipedia
But it is very flexible to manage errors
https://yups.io/www.instagram.com/reel/DdOFgxdlMjv/?stkn=MWR...
- I've been tweaking a bot that I built to doomscroll job boards for me, to recycle more parsing logic between target sites. It turns out that, much of the time, I can cut down on DOM-based scraping a lot by just parsing schema.org-based JSON-LD. Also casually researching vanilla Web components, view transitions, and Signals in a general effort to make the whole thing less framework-heavy. (Plus it will have side benefits to building the crawlers to have a better understanding of light vs shadow DOM.) Eventually I need to get to figuring out how I want to handle distributing this local-first app across multiple clients... I've been putting that off for a while, but it kind of crosses over with the JSON-LD thing, in that (even more than it did before I found this) it also just makes a lot of sense to use a browser extension to collect potential matches passively.
- 3D printing experiments. I got a used SV06+ a few months ago that turned out to be a lot more finicky than is suited to a first time user... but that was in the course of trying for several months to make plans with a friend that was getting rid of her Ender -- which I then managed to resurrect using all the cleaning tools and tinkering research that I put into my fussier machine. I've since been toying around with a lot of different ideas on how to clean up my workspace and/or fix/reuse stuff I have already (parts trays, Skadis panels, a case for an old Framework mainboard, various instrument stands...) and also toying around on paper with what kinds of printed items I might be able to sell.
- Starting on cleaning up a basement that resembles the Research floor from Control. Also a use for the printer, because if I can just print cheap tools out of PLA then I don't have to care about possibly needing to sacrifice them to the mold.
- Various Coursera stuff. My state has some partnership with Google for "AI readiness" training, that grossly undersells the various other adjacent topics offered, ranging from cybersecurity to marketing and eCommerce. Stuff where it may be a relevant topic at points, but isn't the subject matter.
If lisp is a list processing language, grasp is a graph programming language.
The idea was that most other data structures can be represented with a graph ( adjacency matrices are matrices, a tree is a type of directed acyclic graph, a list is a graph where each node connects to at most two nodes, etc) and so if you designed a programming language where the language is itself a graph, much like how lisp is itself a list, you could get other esoteric programming languages like APL, forth, lisp, and so on as DSLs of Grasp. Also any program you write would be its own CFG.
I started it but honestly its mostly a hot mess of vibe-coded garbage. But I may get back on it and try to clean it up.
Open source, free, no login, nothing to sell. I'm not trying to build a business on this. I just want agents to write better code, and that only happens when they have something firmer than a chat prompt to work against. CLI is here: https://github.com/girishr/SpecPilot
It started as a TypeScript CLI in January. Enough people told me they either didn't want a CLI or didn't know how to use one that I rebuilt the front door as a guided chat: 27 questions, runs fully offline in the browser, outputs the .specs/ tree plus an onboarding prompt for your IDE.
Recently shipped an MCP server so the agent can run the questionnaire itself rather than the human doing it, published to the official MCP registry and Smithery. Next is brownfield: point it at an existing repo and backfill specs from the code. Honest state of things: the Product Hunt launch got 4 votes and around 100 visitors, and I had no event tracking wired up, so I couldn't even tell how many of those generated anything. Fixed since. Usage is small but real, and it's coming through MCP rather than the web app, which I did not expect.
The part I keep circling back to is that spec generation is easy to copy. Spec enforcement is where the value is: checking a diff against the spec and failing loudly. Feedback welcome, especially from anyone who tried SDD on an existing codebase and gave up.
well, claude is: https://modus-lisp.github.io
The interesting part has been the data pipeline rather than the website itself. Foreclosure information is scattered across county sites, auction platforms, and other sources, all with different formats and update schedules.
I’m currently pulling from 20+ sources, normalizing the records, deduplicating properties, and enriching them with property/location data. One surprisingly difficult problem has been handling stale records when upstream sources change or republish old auction information.
Still working on improving data freshness and coverage:
https://www.foreclosuredatahub.com/
Would be interested to hear from anyone who’s worked on aggregating messy public datasets at scale.
Broomsday: https://broomsday.com sends folks emails and SMS the night before street sweeping parking restrictions for their block(s). Email notifications are free, SMS on a paid season pass. The schedule here is block-by-block and easy to forget, so people get ticketed _a lot_ at $50 a pop. The city has an email-only notification service that's free, but it's poorly supported and the interface sucks. This is ready; I'm testing with friends and family currently before attempting real marketing.
HailPass: https://hailpass.com similarly is a notify-before-pain service that integrates a bunch of open weather services (NWS/NOAA mostly, plus a handful of impact reporters and working on a small hail-specific ML model) to give folks on the Front Range 5-10m heads-up before damaging hail arrives at their location. Weather prediction is (not shocking) hard so I'm still tuning to get as much signal out of the noise as possible; some false alarms will be unavoidable but I want to cut them down before even a F&F release. This year's season is pretty much over with, so aiming for an April '27 release.
There's a lot of ski/snowboard/winter sport culture here, but there's also existing services for those, and I'm mostly trying to offer new coverage where there isn't a good option for my neighbors. Might do an ash borer treatment/prevention service navigator yet.
None of this is going to make me wealthy or famous, but building things that help the people that I actually interact with every day and that are a part of a community that supports my family feels _really_ good.
Also, an orchestrating agent that supervises subagents running tasks by checking their output and qualifying their results by efficiency and time consumed. It is amazing!
I am currently building an app every couple of days, but with this orchestrator I can build many apps in parallel. It is raw at the moment but it works
Now the time we spend writing prompts will be spent writing plans, tasks, schedules and metrics. While super interesting, this is definitely not the route I want to take for the sake of my sanity. I think we may start asking our model to write plans and tasks for us too, but the more complexity we add, the more complex thoughts we have to manage as AI architects
Also hacking DeepSeek Harness to circumvent all restrictions it has, giving it super powers to run unattended with full access to everything
Browser extension for declarative web scraping. Mostly making it nicer to figure out CSS and XPath selectors thinking of some sort of REPL but I'd need to test the ergonomics. I want to reduce how often you need to use Inspect and the browser console.
Finishing up a PoC for a playwright based scraper that uses the same declarative config as the browser extension
The app has recently moved into production, so I'd encourage anyone with verbal but pre-literate kids to check it out.
The basic pitch is high efficiency acquisition of the highest yield phonetic mapping skills, and nothing else. I myself am something of a screen-time zealot and very wary of applying engagement mind hacks against kids. The narrow focus allows for good progress on a very modest schedule (recommended cap at n minutes per day for n years old, n >= 2). I defer the social and cultural aspects of learning to read entirely to parents.
It is mostly intended for parent-child co-use, although kids with a bit of experience can drive many of their own sessions most of the time.
The cheapest possible lovable alternative with all the features. Currently in alpha.
There's a demo app here that only works on desktop - https://fab.ooer.com/ (scroll down in the right hand menu to quality and change to 'trace' for photo mode)
Traditional error trackers have two failure modes:
1. False positives: They show you thousands of errors, and you can’t tell the impact on the user
2. False negatives: Many user-facing issues don’t throw exceptions, so they go unnoticed.
Opslane combines error tracking and session recording. And there is an agent that acts on both.
Opslane reduces false positives by ranking issues based on how many users are facing a particular issue. It also learns about your product by reading your code and watching your session recordings.
False negatives are harder. Opslane reviews session recordings to spot frustration. They look for rage clicks, dead clicks, and abandoned forms.
Here is a link to the repo: https://github.com/opslane/opslane
https://github.com/rumca-js/OfflineWebSearch
I noticed that it is quite a challenge to publish anything on play store
For that matter, I also decided to self-host SourceHut because I will no longer be in compliance with their new policy. I have the flakes set up to inject them on my server [2]. This was very AI assisted.
[1] https://git.brucewillis.sexy/~tombert/fs_index I promise it’s safe for work, despite the URL. That’s just my dev URL that I play with. Code is still a mess though, so proceed with caution. I will eventually clean it up.
Also created a fun simple "card game" activity for writers looking for story ideas or stuck with writers block: https://talemancy.com/
(This was somewhat inspired by memories of playing Ultima IV as a teenager)
Currently working on something a little more visually focused in creative design.
I don't like putting 20-30 agent skills in the .claude/skills/ dir and letting the agent figure it out. I keep all the skills I've created and adapted over time in a separate git repo and then from there I copy them to the project skill dir when i need them for a session and then remove them when I'm done.
This TUI just replaces all the manual work with ls, cp -r, and rm -rf commands with a few keystrokes.
this year i thought itd be great to help prepare myself and other people in the job market with a tool that presented broken front end code, and then allow debugging on the browser and patch code right there, to test if it worked or not. if cant solve it, theres a nice explainer popup. my main hope is to help level up interview code chops and confidence in debugging just like we would on a real production system , at least the simpler bugs.
still working on it, here's the draft of the idea: https://bugcloud.app
Think about GitHub, but for processes and data.
I built this because I think there's a lack of true realtime (CRDT) synced notes that aren't built on a heavy platform that take up 1GB+ RAM (Totem takes up ~100MB, and is also generally more responsive due to the local-first + ops-log approach).
Another thing I care about is keeping the underlying data portable: Totem is built on Markdown and SQLite as its core formats, so you get the convenience of cloud-based syncing without locking your data into a proprietary format.
I’m still looking for beta users/design partners before the initial launch. You can try it without creating an account here:
https://app.thinktotem.com/sandbox
And the landing page is here:
This is a bit of an unplanned post, so the sandbox template is a bit barebones (empty docs, doesn't feature a properly setup table). Nevertheless, I would love to hear your feedback if you try it out, especially if you use collaborative notes/docs today and have opinions on what they’re missing!
AI is making it possible to (expeditiously) have everything I want or need on Linux or BSD written in POSIX shell or C is doing wonders for me. The initial effort and time pays off in knowing it will essentially function as intended forever, and no developer can make changes that disrupt my workflow or preferences for my environment.
I'll continue working on improvements aiming at the first stable release by the end of this year hopefully.
It's based on the Server-Driven UI philosophy where the backend streams both code and UI into a frontend that just knows how to render what it's told. This is pretty cool because it makes it makes over-the-air updates possible.
It also follows the batteries-included philosophy of Rails. Has an ORM, background and cron jobs (all based on Postgres), Django-style migrations, JSX Emails and pretty great FFI that's built around a simple `"use native"` directive, in the React Server Component fashion).
This simplifies the setup for researchers who want to simulate materials science problems like battery electrode performance on GPUs with a simple usage-based pricing model instead of traditional HPC
The file format is open source, designed for LLMs and for source control. The app has a visual diff system built in.
I designed RapidCAM for me as none of the available options really met my needs. Happy to see that other people are now using it.
I had a bunch of extra Fable credits, so I spent about $10k running autoresearch loops on 200 of the top github repos with frontends to try and speed up the frontend performance. I distilled them down into a leaderboard of the most common wins, and built out an autoresearch loop that takes those learnings and applies them to your repo.
Works with your existing claude/cursor/codex sub in a cute custom TUI.
I just submitted a Show HN for it: https://news.ycombinator.com/item?id=49687032
Here's the skill: https://github.com/gavmor/x86-cpp-reversing-skill
It's all slop, but it's battle-tested and producing results. It's quite fun and inspiring to see some of these assets like textures and geometry that are improperly decompiled, bit shifted or something like that. produces a lot of abstract, glitchy art.
To make sure that my process and results are reproducible, I've gotten back into maintaining Concourse CI pipelines. They were very useful when we were shipping a fork of k8s for VMware, and now they are a fun way of shipping cyberpunk billboard sprites to Cloudflare buckets.
I got back into Concourse in order to attempt a more rigorous approach to generative AI experimentation as well. Unfortunately, there are just so many odd techniques, configurations, loras, and utilities striking my fancy that my experiment pipelines have exploded into the dozens, and Concourse is not a large enough or a high-level enough organizing principle.
https://www.patreon.com/MickeyvanOlst/posts/meet-aml-macos-1...
Typically TD for the Mac has always been a bit underserved, by leaning into some of the frameworks that exclusively exist on macOS I'm hoping more people will see it as a viable platform for this kind of stuff.
The android app is in beta now and the iOS app is in development.
TL;DR: magnets.
I created https://getnoloop.com to block the feed on iOS
1. Aetheris: geometry CAD kernel, https://github.com/yuechen-li-dev/Aetheris/.
Full code CAD capability with big coverage already and some functionalities that even OpenCascade/Parasolid/ACIS doesn't have, full sheet metal module, programmable part assembly, analytical fillets/chamfers, mathematical knots, auto-route for piping, built-in finite element analysis, etc. Had Astra make an improved version of the V8 demo that was going around on LinkedIn, so it can do general hard surface modeling pretty well too, turn all the Astra demo prowess into reusable capabilities/templates. The DSL is human writable too, so give it a try if you want. https://aetheris-editable-v8.yuechenli.workers.dev/
2. Concept language: https://github.com/yuechen-li-dev/Concept
I've said before that Carbon isn't a real programming language, never mind a successor to C++, so I decided to put my money where my mouth is. The idea of it is to be more TypeScript to C++'s JavaScript and to generalize C++20 concepts from template constraints to what C++26 is doing with contracts, and bring the equivalent of Rust's borrow checker to be opt-in by default instead of opt-out, fast compile time, in a syntax that C++ users are already familiar with (`const auto` instead of `let` for example) as well as templates and comptime. Language is done-ish, not self hosted yet, still compiles to C11, kernel and allocator libraries are finished, currently working on the scheduler right now.
3. Copeland TS, https://github.com/yuechen-li-dev/copeland
TypeScript for .NET without all the weirdness of Javascript, with full Nuget and NPM inter-op, Rust style exhaustive `match`, templates, etc. It's actually weird how much cleaned up TypeScript ended up looking like cleaned up C++. Compiles to JS, C#, WASM via Blazor WebAssembly, and SPIR-V via HLSL/DXC, and runs on V8 for JS and RyuJIT/NativeAOT for C#. The conclusion is that RyuJIT ended up being ~2x faster than V8 JS in hot loops but the cold startup time is higher, so replacing JS for UI really isn't worth it. Comes with full UI layout system, Vulkan renderer, and game/app runtime, but those are still pretty rough.
*walletwallet.dev
Desperately trying to attract new monthly sponsors and people willing to buy me the occasional pizza with my terrible HTML skills. Is it working?
If any individuals, companies (or bitcoin millionaires) would like to help a long-time OpenBSD slacker, unslack, I'd really like to focus more of my time on open source development (and advocacy), rather than making rent. Feel free to contact me.
https://brynet.ca/wallofpizza.html
(Native SegWit): bc1qwe6zv0ezq4gzlea6tw45qhsn5kckheljn0krvt
... and used Claude to crank the software up to 11. Network management console, RESTful API, added hands hands to the pupils so it serves as a clock, NTP, added sleep mode at night, added different eyes, OTA firmware updates, and more: https://github.com/michael-gebis/creeper-eyes
It's ridiculous and I love it.
While you might think "yey another coding agent" i went down some very different paths than other open source coding agents do right now. Ill not bore you with a ton of detailed breakdowns and rather list the main points that are relevant to understand why/how i build it.
Premise:
-The agent is meant to run against selfhosted environments first like Ollama etc with a focus on non cloud sized models, it should work properly on something like a 27b model already
-The agent with full intention trades execution time vs reasoning and result quality
So what does it do different:
1. The agent, instead of trying to let the model solve a whole task in 3-5 inferences, rather breaks down the "thinking process" in smaller chunks, basically decomposing the task into smaller tasks. While this is not a completely new concept, the agent will break it down to really simple single step variants which even for a smaller model can properly be solved. This involves not just file editings but all points along the way from interpreting user message to planing a task to defining acceptance criteria etc.
2. The agent is build in a way that it, apart from some fixed steps such as detect user intent at the beginning and synthesize response at the end, it will by itself decide what is the next proper step to execute/do based on the context i provide. While doing so the agent also revalidates its current execution and if it spots that, given the information i collected since it planned and started running, the current plan is not detailed enough or is missing out due to something he didnt "know" when he was planing, the agent will dynamicly mutate the coming plan stats, as in restructure/decompose/etc in order to have a properly layed out route to fulfill the task.
3. The agent has a rather complex system of how his context is composed which is combined by things like the chat history, previous step results, a backlog of what "single steps" it has done (updated file x , read range from file y etc) and in that it is strongly reason driven, so it will for most of the things it does also provide a small reason explaination for why it did that. Than the agent also has a working memory that contains facts and decisions it made along execution. There is more but thats just some thingsd to mention. The whole memory system and context is rather complex (tho not complicated). When i release it ill properly break down how all this works in the docs.
4. The agent provides full observability in the ui. At every point of execution you can basically in detail see whats in memory, whats the current composed context, whats the plan and what plan steps depend on what previous steps, you can look at artefacts it build and also you have basically a complete audit log of all single "actions" it has executed and can look into their details.
5. The agent allows to while in an execution send steering messages, meaning the message will be, using relevant current contextual information about its execution, send as inference with a prompt askind the agent to interpret on if its relevant, and how does it impact the current execution/plan. It than can decide either just do alter what it currently does, or even do a plan mutation in order to accomodate the users steering information.
6. The agent within its capabilities has a lot of error correction/self reflection logic. From dynamicly fixing json including a fallback to let LLM fix a response json, upon to if executions fail to much it will itself do a hypothesis on why this is happening, formulate a critique and with that reevaluate if it wants to try the steps again with the additional information, or if it wants to mutate the plan to accomodate the just spotted problems.
Theres quite some more i could list but i guess thats enaugh for now. The big trade off as mentioned earlier is execution time. In comparsion to cloud native agents, which will do giant editings and reasonings in just a hand full of inferences, my agent uses a ton of inferences. The big difference is that this allows (a) the agent to more precisly focus on specific tasks rather than overloading it with to much at once and (b) alot better spot problems/mistakes itself and adjust its execution plan to accomodate those without the user having to reprompt the agent 10 times until something is actually correctly solved.
Apart from the pure coding capability, the very same actions that allow for higher quality reasoning and coding at the same time allow the agent also be a good analysis and discussion partner.
So : what is it than used for if inferences and executions can take very long? Well for me its in terms of coding capabilities a hands off agent. Its meant to be informed once at the beginning with relevant details, and than should be fully capable (as long its in the capabilities for sure) to fulfill the task without the user having to permanently keep an eye open. I want to free time for myself and not change my time from coding to prompting.
Ill wrap it up here and say : the Agents name is "Loa" and i probably will post it on hackernews as soon i got a relatively stable beta to release. Im close to being fine with a beta release but i want to test some more runs before i publish.
https://github.com/office-42/word42
https://github.com/office-42/math42
I was curious if AI agents could go beyond just making SVGs and create entire skits with them.
So I built a platform to do that. Results were meh until Astra, so I finally open sourced it last weekend.
I wonder if anyone reads these? If you do, if you want to complain to me about observability, please shoot me an email at hello@telemetrymachine.com!
We have worked in the observability industry for a combined 15 years and we are trying to right the wrongs we have seen in the industry. It seems like the existing companies are more interested in extracting more and more money from giant customers than actually helping people run their software well.
I won't bury the lede: what we've built is OTel native, wide events native, and works well with agents. We are also, shamelessly, cheaper than everyone else. One of the reasons observability is struggling with adoption is because it's too damn expensive.
So that's what we're building at telemetrymachine.com: an observability product focused on helping you actually track your software (starting with OTel traces and logs). We are really inspired by Observability 2.0/wide events, which really just is an invitation to stuff as many attributes, with as much cardinality as you want, into your spans/logs.
One thing we are also doing differently is trying to be as lean as efficient as possible. We are just two people now, and we are going to be very careful about hiring anyone. Most importantly, what we need to do is avoid a giant salesforce as much as possible. I wrote about this in a blog post[1] but the reason observability is so expensive is actually the giant sales force these companies tend to have.
We also put a lot of work into actual infra efficiency – ie we run on bare metal, and wrote a state of the art[2] storage engine. All of this is to help get prices down while still building a sustainable business.
We are very keen to engage with observability users, so if you do, or do NOT, use observability in your services, please reach out and we'd love to hear your problems and thoughts!
[1] https://telemetrymachine.com/blog/observability-doesnt-have-... [2] https://telemetrymachine.com/blog/the-new-state-of-the-art-i...
The Odds Assist tool started out as a way for me to quickly QA the data from the API. It then turned into its own product as an odds scanner and sports book advantage finder (mainly arbitrage, +EV, middles, etc). Over the past few months it's really pivoted toward prediction markets and collecting and displaying data to get an edge on markets that are soft.
The pivot to focus on PMs has been pretty fun from a development perspective since there's so many niche markets to look explore. I've always liked math, I'm a bit of a digital hoarder, and I've got ADHD so finding random things to collect a bunch of data for just to test a hypothesis just hits my brain in all the right ways. It's also given me an excuse to learn more about ML what has been great.
It has been really interesting trying to fit a detailed weather forecast into about 1,000 bits. I'm using an rANS entropy coder fitted on historical weather forecasts. I'm able to fit about 100 time periods (~4 days of hourly data) into a 160 character message, using just a couple bits per variable on average.
Github: https://github.com/aaasen/goingblue Site: https://going.blue
If you are using coding agents and craving for backlinks, I'll personally help iron out bugs/issues. Email me.
We mostly focus on things you cannot find in bookstores: bilingual stories with parallel text for multilingual homes, and non-fiction for kids who have hyper-specific obsessions (like tunnel boring machines or wastewater systems).
I am building a new kind of LLM runner which lets you understand the internal reasoning process, and which can be automated to intercept hallucinations and prompt injections before they cause more damage.
(No public code yet, but I do intend to open source it)
This is my attempt to improve my agentic coding workflow by giving the agent an index into the source code through vector embeddings and LLM generated descriptions with local sqlite as the storage backend.
There are many similar tools, but I wanted to learn how such a tool can work by building it myself. What I like about my own version is that I kept things simple - no MCP, no server, no watches, just a CLI that uses git commit hashes to reindex only what has changed.
- Flexible rp2040-based instrument tuner
- Stratocaster-style PCB art pickguards
- NeXTBus experimentation board (not that I'll ever use it, but I'll be darned if I don't understand the nuances between NeXT and Apple's NuBUS implementations better now)
This extends to firmware and emulation projects like Doom and the Quake trilogy running in Jira Cloud (https://marketplace.atlassian.com/apps/3372062249/doom-for-j...) and a fork of 86box dedicated to NeXTstep systems (i want an emulated object.station, darnit)
Also: kids can code using cardboard cut-out blocks and just take a photo to import, generate Arduino firmware, compile and flash to ESP32 - all from a single docker web application.
Hoping to bootstrap a cheaper, open source alternative to current systems (one of which my son is using at his school). I have had success doing this with another project on Patreon so that's where it is going to be launched. https://www.patreon.com/ChonkyBlox - so far just a couple of demo video's but code will be released in full once I have added more blocks and a tutorial.
Ultimately this is aimed at the South African education sector, where many schools may have only one computer available for a classroom to share, hence the cardboard cut-outs. There is also a hardware component still in development - a simple pcb breadboard break-out with connectors for components instead of kids having to use jumper cables on the breadboared. We also have a working Desktop application which does code assistance from within the Arduino IDE - using the same web server with api, so literally everything from very small kids to advanced is covered.
What makes the app a little different from others is that it's kind of halfway between an outliner and a wiki. You can place notes in a tree hierarchy, but they can be free-floating as well. You can link to other notes using wiki-style text links, and each note has a unique address, so you don't need to give notes a title or a filename.
Notes can even appear as a child note of more than one parent. The idea is that you can jot down an idea quickly without a lot of friction and then later either add sub-notes to create a note "tree" from it or add it to an existing tree. The tree gives structure to related notes, but the wiki-style links allow you to connect notes together outside of that structure. (I consider the tree structure a "hard" relationship and the links a "soft" one.)
There isn't a single uber-tree where every note goes. Your notebook ends up with lots of free-floating notes and lots of small trees of organized notes, like a card-based Zettelkasten system. You can use search and various filters to find and stumble upon notes easily.
Notes can either be stored in iCloud (so that they sync across devices) or saved in a folder as simple Markdown files.
If you're curious, you can help beta test it. More info here: https://zettelkasten.ussherpress.com/
It's an early version so many (if not most) things that would be in a game are still missing at the moment (though planned on paper).
One interesting thing is that because the Voronoi voxels are so malleable, things like round or hollow worlds are a pretty natural outcome.
In parallel to working on it, I've been mostly using it to build and improve my own voxel castle with a pointy roof, slanted walls, custom built stairs, tables, chairs and all those nice things.
In the last update I added a CRT filter and some pixelation options as I find that appealing. As for the future (maybe as the next thing?), I guess I'd probably like to add the ability to build less blocky things like round towers (or flower vases!), but that is still very much a work in progress.
The Web version (WebGL) is completely free (and will stay that way):
I'm building HAR Analyzer: a native macOS app for searching and inspecting HAR files locally, without uploading sensitive traffic to the cloud.
Like Network Dev Tools but with a better UX.
Ai-rganize: Allows AI to identify, classify, and organize local files, making the core workflow naturally reviewable as scan, propose organization, approve, rename or move: https://github.com/adefemi171/ai-rganize
Runeward: Been using this locally myself with hedr to secure all my agents: https://github.com/Runewardd/runeward
Compears: grocery prices are shit now so I designed this to aggregate prices across multiple grocery stores: https://compears.shop/
It’s been really fun working on it and especially rewarding seeing the game bring friends together.
https://notifier.aicrew.in/setup
It renders markdown, screenshots, can send as audio, allows approval & free form reply when it direction.
iOS app - https://apps.apple.com/us/app/agent-notifier/id6763598043
Constantly and carefully iterating through refinement and features. It's built on Rust + Tauri with a React frontend, in case anyone is curious.
I've created various open-source and commercial tools in the multimedia space over the last 10+ years and wanted to put it all together into something more premium with an IDE-like experience.
Most recently I added a /playground area to experiment with the inspection tools via a WASM build, which I thought was a neat way for users to try the app before downloading the full version.
Happy to answer any questions!
I appreciate that it makes me revisit some math which i've forgotten like directional derivative and why gradient points to highest ascent.
Interesting but hard as well.
And then ... well, we'll see. I'm also reading a lot of books and stuff on neuroscience, neuromorphic computing[3], analog computing, etc. I don't have some "grand unified theory" or anything, just playing around in this space.
There's a lot more I could say about this, but I'll save that for a blog post or something. That said, if anybody wants to see some pictures and read some write-ups of some of this stuff, add me on LinkedIn[4] and you'll see some of that stuff in my activity there.
EDIT:
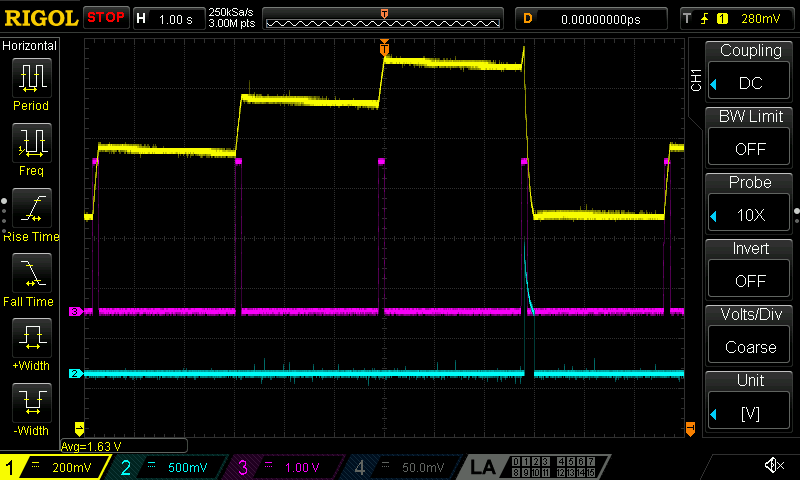
What the heck, here's a picture for anybody who's interested.
https://fogbeam.com/images/scope_20260913_202613.png
The magenta trace is the "spike train" which is output from a Rigol DG4162 Function Generator. The yellow trace is the voltage at the anode of the PUT, which simulates the "action potential" of the neuron membrane. And the cyan trace is the cathode of the PUT, which simulates the output of the neuron. What we see here are several input pulses hitting, with each bumping the action potential up a little, until it finally hits a threshold and then "fires" and resets. Lather rinse repeat.
[1]: https://en.wikipedia.org/wiki/Programmable_unijunction_trans...
[2]: https://neuronaldynamics.epfl.ch/online/Ch1.S3.html
Been optimising an ssh ansi rendering engine for six months, starting to look great. Homepage is slop please forgive
https://github.com/amir734jj/symmetric-crypto-chat-room
Share an encryption key with someone offline, then chat with them (text + voice + video + file) encrypted with that key. Your JavaScript browser only knows that key. Nothing is shared. True end-to-end encryption in your browser.
I'm thinking about buying all the strains and pushing them through my automated sequencing pipeline, and building a yeast genotype -> flavor converter. Then, I think it'd be neat if you could have someone try a bunch of wines to get their favorite, and then genetically engineer a yeast strain specifically for their favorite flavors. Think that could be neat.
I already have a product BenkoPhone.com but the app is provided by a 3rd party and I just white label it so I have started building the replacement.
I built the account management and billing system first after implementing a proof of concept for the app then had to do a major platform change which stalled development of any other features for 3 months.
Hopefully I’ll be adding features again by the end of this month and I’ll put some screenshots in once it actually does something!
Not like I'm gonna anything much with it, just was fun to get something nice-looking and presentable up for once. Working on polishing more of them and, of course, designing new ones.
2) A font generation system, inspired by Iosevka, albeit much much simpler. Learning tons of interesting technical things about TTF and WOFF2.
I wrote my own site parsing toolkit which removed the friction I have with the current ones. It's now easy to add new locations quickly to scale.
If there's a tool you'd like to see there, let me know and I'll add it.
A social media platform trying to solve misinformation, astroturfing and inauthentic posting. I also thought there was a real space for some non-US-based social media, so this is based in Australia. This is owing to all the political instability going on in the US right now and especially stuff like users' identities being subpoenaed for criticising the government. It was a pet peeve of mine seeing threads of comments that are obviously artificially created to push some kind of narrative, and the ability to buy likes and upvotes to shape opinion. Nothing ever seems to get done about it on big platforms, so I wanted to make some small contribution towards fixing it. And there's an element of self-interest here, because I want to be able to read a platform where every comment is authentic.
I've been working on it since 2023 and launched in March this year. Recently, native mobile apps have been launched. It was also an experiment in seeing whether Swift Vapor can be used to build a complex backend and the answer appears to be yes. It's a lot of fun to see how bad actors are joining the site, then building automated mechanisms to counter them, using AI to improve detection, without impacting legitimate users. It's also been a great technical challenge to try to support features that the big players support, like video upload and encoding, image upload, CSAM detection, NSFW detection, LLM-generated text detection and auto-translation using DeepL.
There are also lots of legal compliance challenges now with age verification laws coming in around the world, and ensuring you employ all the correct Apple and Google-specific verification (Declared Age Range, Play Age Signals) in the correct global regions. It's also fascinating to see behind the scenes how tight or not so tight current age verification actually is.
Recently, I've been polishing the iOS version to try to hit the 120 Hz target frame rate while scrolling feeds and finding SwiftUI is much less capable at this than the old UIKit approach. I'm also trying to teach myself marketing and how to keep users engaged. I'm primarily code-oriented and historically haven't had to do any marketing myself, and this is a vertical learning curve. I have gained a great deal of respect for those who have 'figured out' marketing, seeing how difficult it is starting from nothing.
It's also satisfying to take a feature from a user suggestion in the morning to an app release including that feature in the evening. This is a speed of delivery that would be unthinkable in the corporate world, where I previously worked, and it's very gratifying to put a complete feature in a user's hands within 24 hours.
Anyway, it's a very long and tough road and may amount to nothing in the end. But if nothing else, it's been immensely educational and enjoyable. Thanks for reading and feel free to check it out:
https://play.google.com/store/apps/details?id=com.topicle.ap...
Here: https://bookofrevenue.com
To my surprise, I think it's the first open-source revenue analytics for Stripe.
I worked at Stripe building both revenue recognition and analytics, and I always wanted to build an open-source version of those. Finally, I had the time to do it.
Bonus: Revenue is not MRR nor payments: https://medium.com/@tanin47/revenue-is-not-mrr-nor-payments-...
https://videohubapp.com/ - an application that lets you browse, search, organize, etc the videos you have on your computer, external hard drives, or network drives.
It started after spending 15 years building AI for insurers, hospitals, data companies, and startups. Almost every system ended with "a human reviews the output". That person was usually a nurse, medical director, or certified coder. These are some of the hardest people to hire, and the same people automation was supposed to help.
The problem is that real claims do not have an answer key. You cannot reduce human review until you can measure when an agent is wrong.
Getting claims data is also difficult. It can take a year of data agreements, privacy reviews, and procurement. Even then, you may not know what the correct decision should have been. So we generate claims. Utilization and case mix come from published data. Claims are priced using real fee schedules and contract terms. Payers behave differently, like real payers do. We plant errors on purpose, so the correct answer exists before any model runs.
On top of that, we are building benchmarks for overreach, refusal, errors by record type, and detection time. We are also building small MCP tools that refuse when evidence is missing. Every number includes its source, date, and basis.
What I find interesting is how much of this sits between actuarial work and machine learning. Both are needed, but I do not see many people connecting them.
25 published refusals: https://hammer.ai/worlds/refusals/ .
Runs on rate and policy evidence https://hammer.ai/reimbursement-evidence/ and savings claims https://hammer.ai/savings-claims/ .
AgentPlugin is Apache-2.0: https://github.com/hmmrlabs/hammer-plugin
The web design (and text?) really come off as ChatGPT written, which lowers my interest in spending time to understand it.
Despite the fact that trainyard has been defunct for ~8 years, I didn't want to simply clone it.
I tried to give a similar, but not the same, experience -- I'd be very curious to know how close you think I came.
https://dmcn.dev - an email where you can be sure who it's from. And you get to decide whether to trust it.
[1] https://github.com/jha-naman/treetags
[2] https://github.com/jha-naman/treetags/pull/62
Tried to use a generator for automating the bulk of the scanner for a language from `grammar.json` file of a tree-sitter grammar. A runtime engine uses the scanner for a forward only walk on the scanned code and calls the hooks to generate tags.
[3] https://github.com/jha-naman/treetags/pull/56
A complicated mess of a generator that takes a few declarative inputs and tries to generate code for spitting out tags for a given language.
so yeah.. it builds the stories out of their actual life. their family and friends are in the cast, their dog, the thing they're nervous about this week. the kid doesn't just appear in the story, the story is about their world and imagination and grows with them.
ultimate goal is to keep iterating and get to a level of quality of Bluey, etc but have it actually be the kids world with agency/choices vs. one they have to passively sit back and watch, and that they're not in.
would love any feedback. i know there's been others like Ello shared on here and those threads were really interesting to know HN's opinion on. this does not take an educational and instructional approach. Tella is meant to help develop who they are through stories and be a better screen alternative time to the rest of the algo/curated garbage out there. anyway you guys are a critical and technical bunch and i respect/appreciate that.. especially since this of course leverages multiple AI services to create the stories ~
Big re-factoring, I have a data model now and am closing functionality gaps with Zola and the like. Also, I wanted actual documentation. No one else seems to care about that.
Check it out! I'd appreciate someone other than me banging on it.
And also Kronikle https://www.kronikle.eu/en/ an app for local libraries. It creates public display interfaces that (I think) are good for showcasing their events.
After being frustrated with outdated & inaccurate data Claude used when I was trying to do some property research, I thought it'd be cool to build an MCP that can provide accurate property data. Then it evolved into a full web app + an AI assistant.
This was also an excuse for me to try DuckDB in a real project. All the API endpoints are powered through in-process DuckDB querying parquet files stored in disk.
And the other one is a AI rank monitoring for brands - https://lumirank.ai
Finally getting around to organising my photo archive and setting up a metadata extraction pipeline that makes sense for me.
(At the day job, curious about adapting app layouts to accommodate the iPhone Duo and address the various Android foldables at the same time, too).
The second probe in Boston fixes this and the site can now say "unreachable from Asia" versus "down for everyone". Many of the existing checkers do not do this and they are prone to show false positives.
Site does not use cookies or analytics. Pageviews are counted from the proxy access log. There are 634 curated sites so far.
There are no ads either, it's mostly been for my personal learning experience, hopefully others will find it useful.
There is even a free API and of course a MCP server.
https://downforjustmeoreveryone.com
Any feedback is welcome!
I find Grasshopper, especially its data model, ideal for a certain type of algorithmic art/design, and have always wanted to use it in a 2D graphics package.
https://www.figma.com/community/plugin/1677548868352947603/c...
1. A robotics information and news website. Any feedback is appreciated. https://robotica.dev/
2. Applied DBSP theory to Postgres https://github.com/getravi/pg_dbsp and DuckDB https://github.com/getravi/duckDBSP. The idea is to have incrementally maintained materialized views.
Recently cleaned up my postgres proxy and built a MySQL wire proxy so that you can use psql/datagrip as a dev but every statement is still logged. With SSO and no password sharing ofc!
Eylo (a take on Hello) a voice first agent platform, multi-tenant, focused on B2B2C use-cases - https://github.com/DigiCred-OSS/eylo-os
It’s a distilled fork of a closed source product that we are offering to our customers.
It's a simple PGN app to help capturing chess notation from score sheet and fix the mistakes
Often my son and I made mistakes (mixing up b and B, or wrong rank, missing some moves) writing the notations and existing PGN parser simply stop at the first error and discard the rest. ChessNotate highlights the error while maintaining the original moves so you can see if your fix is actually fixes the remaining of the moves (or not)
Used it in the recent chess tournament and it's been really helpful
https://kaflow-search.whsoul-tools.com/
To enable fast and detailed searches, I adopted a "local indexing" approach that differs from existing Kafka tools.
I recommend giving this a try if you have found operating services with Kafka inconvenient.
So over the years me (and my team) have built up a lot of experience dealing with these for sensitive industries like healthcare/insurace/lending etc.
We are bringing these ideas out as a router to other parsers, but with some key takes that allow you to manage failures. "Failure is inevitable so route for it."
It is called Openreading - https://openreading.ai/ and open core here: https://github.com/openreading-ai/openreading-core
It is still WIP and will be more polished in a month after some more rigorous testing and benchmarks.
If this is a problem you deal with, would love to chat.
Note: the intent is to launch a managed version that provides more durable compute/retries, parallel execution, intent understanding etc but this is for later.
As we move away from reading code more and more, I started learning about OpenSpec as a way to be more spec oriented to develop software. Reading specs in a code editor didnt make sense so I wrote my “OpenSpec IDE”. Very simple desktop app, no subs or accounts. Its really a markdown reader but built specifically for OpenSpec so you can read things in order and summon Claude (others coming soon) to execute the required OpenSpec commands
The idea is simple: store state you'd normally store in a separate database in the document itself.
Then, also give the the document a bunch of powerful APIs granted to it by its host:
(1) Sync changes to the document with live collaborators
(2) Extract data from the document using a simple JSON map config
(3) Boot up a full content CMS from the same simple JSON map config
(4) More features added every month
I'm really excited with even the tiny bit of early traction I've gotten. About a dozen paying users so far.
Long term, I'd love to have this file type (vanilla HTML file + some extra features granted by the host) become a file type other companies offer tools and their own hosting for (like Wordpress).
Hosted platform: https://hyperclay.com
Native offline apps (source available, almost MIT license):
A programming language which lets you code multiplayer games like singleplayer games. Every program written in Easel is guaranteed deterministic and snapshottable, which is how it can automatically make your game multiplayer automatically using rollback netcode.
My hope is that teenagers who makes games in Scratch might like to make games in Easel because it means they can make games they can play with their friends, without having to deploy a server or learn anything about networking on synchronization. People can literally make a multiplayer game on their first day of coding.
Currently been working on adding tilemaps.
And then even for simple turn-based games, there has to be elaborate fully-decided like state diagrams for all the various types of disconnect and latency states so that gameplay doesn't desynch or hitch in awkward ways.
The web spec is vast and endless, if you try to build something actually works for modern sites, it will be huge. If you want to keep it lightweight, it won't work for most sites.
Just use chrome-headless-shell or webkit. Don't reinvent the wheels.
It's pretty simple to set up and is designed to "just work", set and forget.
Recently, I've been experimenting with an Elixir Lua runtime (https://deflua.com/) to build custom feeds by parsing HTML, which has worked exceedingly well, so hoping to release that soon.
It's an extremely niche product, but has been growing well organically, which is nice for a side project!
(https://github.com/Tori-Tech/Mandating-Honeypots-Project)
In that project, I also proposed a tool with heavily redundant password protection that parents could use to keep kids from tampering with the service so the government can stop saying that this is for the kids. I'm planning on doing a mobile device version and/or an ID database focused version, but that's still in the planning phase.
I also want to do a Windows version when they release their 'GetUserAgeRangeAsync' API, but idk if I'll be able to. Windows is always a pain to work with.
It'd be nice if someone had advice or ideas to share, too.
Now working on releasing on steam, android, ios. Also made an ssh version you can access via your terminal [2]. Hoping could get as many downloads in native platforms.
I'm a Senior Eng on Wall Street, so I have my own personal experience with this problem, but i'd love to connect with other leads, release managers, etc to get their thoughts, suggestions, and what their current process looks like.
Trace Python+NumPy programs into SymPy formulas and check them symbolically, across all branches
Initially started as WhatsApp Team Inbox. But, now I am adding telegram bot, emails and MCP support. Eventually, I am going to add like Messenger, Instagram, Line, Viber, Discord, Slack, etc...
So, it will be a bridge between your/your business communication and AI via MCP. If you want to create your own agent you would be able to create as well.
I vibe coded mostly, but once a while I go in and refactor heavy.
Why? There's no why. The world doesn't need another Markdown editor. I still made one.
Everything is on-device, purposefully human-centric without being anti-AI. I built this because I wanted to work on a project that I could sweat the details unconstrained by deadlines, investors, etc.
I was frustrated with other writing experiences, and like most I gravitated to Apple Notes due to simplicity, but I still missed so many things. As someone that's spent the last 2 years immersed in Cursor, Codex and CC, I wished some of their input behaviors existed in a regular text editor.
For example, you can use / to add styles, or : to add emojis, shortcuts like < 3 for a heart, - > for an arrow, and so on. It honestly feels great.
Is it radically different than other editors? I don't think so. But I think it's well executed across every dimension possible.
Maybe one different thing: multiplayer. It's live editing like google docs, but P2P using WebRTC and strong cryptography. The limitation here is that you can only share a file while having it open yourself.
Great care was taken to performance and portability. This is one of the areas where I spent a ridiculous amount of time simply because I enjoyed pushing the limits of the stack. While using you will notice that rendering, GPU, RAM and bundle sizes were heavily optimized. The Mac app is < 50mb.
Very soon, I'll launch an iOS version with iCloud sync. In the future, I might launch basic AI features. If you miss a great text editor in your life, give it a try.
One UI for every coding agent - VS Code extension (GUI) to launch and work with any ACP-compatible agent harness. Supports Claude Code, Codex, OpenCode, Qwen and many others - https://agentclientprotocol.com/get-started/registry . Does not require any new subscription or user ID - this is still handled by the harness, so you can use existing Claude Code or Codex subscription. Multicoder just gives you a high-quality GUI to work with any of them without mental switching cost.
The basic idea is to separate an application's UI semantics from the toolkit that actually renders it. The same application can currently be presented using native Win32, Cocoa/AppKit, Qt6, GTK3, GTK4, Swing, or a web browser. The UI can run locally or be rendered remotely by a client, without the application itself being rewritten for that environment.
I've also been working on a declarative layout format and, lately, a visual designer.
It started as a rewrite of an architecture I worked on many years ago, mostly because I wanted to see how far the idea could be pushed with modern systems. It has turned into a considerably larger project than I expected.
Still private and very much under development, but I'm curious whether other people have run into the same problem: maintaining applications that need to survive changes in GUI toolkits, operating systems, deployment models, or client environments.
https://www.linkedin.com/posts/okaleniuk_isosurface-mesh-stl...
The lattice configuration comes from a conventional triangle mesh, so you can prepare it with any STL editor of your choice, and the lattice shape comes from a precalculated Fourier polynomial in barycentric coordinates.
https://okaleniuk.codeberg.page/blackboard/barycentric_fouri...
It was a pain point from a start up I cofounded before where we needed Kubernetes flexibility but developers hated using it. I figured there was no reason why it had to be hard to use and thus Canine was born.
Lately been playing around with setting up remote dev containers on your own compute as well -- basically like github codespaces, except self hosted.
Built in Rails + Stimulus
The interesting problems were: MSE on iOS Safari, chunk continuity across peers, and handling rotation metadata that iOS bakes into the video stream. Also, the tracker is a separate bittorrent-tracker instance because the built-in WebTorrent trackers are unreliable for sustained swarms. Also i used a ton of graphql, so normally with a torrent you have to kind of let people find you but i used a graphql subscription to TELL people what the magnet links were called so they can fetch them asap. Lots of shortcuts like that, its been interesting!!
and... whenever i have some spare gpt-6 astra left i am working on a R.U.S.E reimplementation alongside some other threejs experiments
Online container planner in 3d
If you love catching up on highlights, check https://thepelota.tv/
It’s like Netflix but for soccer highlights, with all the major leagues in one place as soon as they are available on YouTube, all free and no ads.
https://github.com/mcdirmid/cleanroom
So far I have bazel macros up that can produce tested code with a ~30GB MoE model (Jundot/Qwen3.6-35B-A3B-oQ6-mtp, I can get ~90 toks/sec on a M3 Max!) using cleanroom separate implementation and test development (and then comparing them until both are correct). Over the last month, however, I found that my bottleneck is in the specifications: as I further divided my components into separate parts (since smaller components are easier to write and test), I started hitting problems with specifications becoming badly ungrounded (code depending on knowledge they cannot access, so something is just hallucinated).
So I redid the format, e.g.
https://github.com/mcdirmid/cleanroom/blob/main/update_with_...
The spec format is designed to be declarative and very modular, and ya, an LLM is primarily writing the specs as well, so I hope to create some sort of formal reasoning framework that the specification can be translated into (by an LLM) so that ungroundness feedback can help the LLM write better specs. Also, I found that it really is much more robust to change/refactor/add features via the spec first and then align changes down to test and code, then to make changes to the code directly (even without using the system, just asking a frontier model to look at the guides and do the alignment itself directly).
I think I'll be ready to do a release over this next month, which means:
- Supporting a build system other than Bazel to express DAGs. Honestly, this could be anything, I just chose Bazel for convenience (easy to express graphs in Starlark), but it assumes a monorepo world that I don't think many developers use.
- How do I even package this? The advance of using Starlark is that I can generate python code to call into the generated python code directly. If I move away from that, I need to figure out what this really looks like as a binary.
- More demos. Right now my only project is the code for the system itself (the classic "the first program of a language is the compiler for the language"). I just can't think of many interesting things to do in Python that aren't agent related (I can support other languages, like Java, Typescript, or even C++, but I'm hitting choice paralysis).
Don helps you set goals.
Don reminds you to take breaks.
Don checks in how you fell.
Don judges you when you go off track.
Don celebrates you when you get stuff done.
Looking for feedback from people who already run Claude Code and are testing out new AI software factories or tools.
Try it here https://github.com/Team1-dev/Team1-Factory
Please only run this on a VPS or isolated environment and not on your personal machine as it runs with full permissions.
My wife and I are working on a math/science/CS-inspired jewelry: pieces that stand on their own aesthetically but have a hidden meaning.
We currently have two styles: lambda calculus based pieces (we depict the Tromp diagram) where we have Y-Combinator earrings (well, strictly speaking they are one beta reduction away from Y-combinator. Aesthetic oblige) and a pendant depicting a lambda expression computing Graham's number. The other style is quantum computing circuits, based on quantum computing research my brother (a physics professor) is doing: a pendant that is actually a non-local controlled-NOT gate.
I wrote a tiny DSL to describe the jewelry pieces, and an interpreter to produce CAD files. We then either 3D print them or have them produced by lost-wax.
We have our pieces in consignent in a jewelry store, and are working to put them in a museum store.
Marketing is the hardest part. Ideas are welcome.
Actually, I can share the link if anyone is interested (because this is the "what have you been working on" thread and this has been one of my more fun projects): https://www.thegamecrafter.com/games/mathematical-minds-thre...
Same thought on marketing - where to advertise where people would appreciate this kind of thing?
Iron volume, recently added a kettlebell complex generator which isn’t too bad if I say myself https://www.ironvolume.com/
17,000+ users already! It's a completely ad free, subscription free product. MacroCodex app, which results in guaranteed weight loss or weight gain outcomes within 2-3 weeks. Many people will start seeing results within the first week. Don't believe? Read the reviews.
MacroCodex is a "Total Calorie Burn of the day" using completely sensorless method explained here: https://macrocodex.app/knowledge/macrocodex/smart-calorie-bu...
CalorieCodex - calorie tracking app which has a Agent Harness built in using BYOK (bring your own key model). How does it help? Using this anyone can track calories and plan their meals. Agent includes skills which help you accurately track calories and plan meals.
Symbiote App - Think "BoostCamp" but completely free, no ads, and fully programmable workout tracker
Example of GZCLP: https://symbiote-studio.macrocodex.app/?builtin=gzclp
You would be surprised at how many over / suboptimally-provisioned dbs, idle resources, forgotten EBS snapshots, outdated / previous-gen instance types, and vestigial networking that leads to nowhere I find.
If you want to check it out https://cca.dragonfractal.com
It's an ADHD medication companion. It helps with remembering to take your meds, understanding the effect curve, getting lifecycle notifications (when it peaks, when it starts to wear off), pacing multiple doses throughout the day, and managing your supply.
It's built for iOS and uses the apple ecosystem to ensure privacy for your health data. Data is stored in your own private iCloud account and we do not have access to it.
I remember someone saying that when you build a game, you end up building tools to help you build the game. I never really got that, but now I do. I've spent quite a bit of time working on tools to help me balance the various game mechanics.
One weird learning, it was much easier to get it on the iOS app store, than the Google Play store. Google wants you to have a closed playtest with at least 12 players, for 14 days. I did that and they said the testers weren't engaged enough.
If you want to check it out on iOS https://apps.apple.com/us/app/fairway-rogue/id6783598189, I'm still trying to get it on Android
A way for BJJ and martial arts academy owners to manage attendance, payments, class schedules, and student progress.
I train BJJ myself and saw how much time instructors lose to admin work, so I wanted something simpler and more focused than the generic gym software out there and have been having a lot of fun building it with feedback from real academies.
The idea is to make an extension that allows you to flexibly fill out fields on your cards with AI generated text, speech, and images. Think generating example sentences for your entire deck, or adding furigana to kanji (small phonetic characters with a very delicate syntax). It works just as well for language learners as it does for medical students, etc.
The secondary goal has been to make this the most well designed, intuitive, and stable Anki extension in the world. I don’t think it’s there yet, but it’s on its way. It’s been very interesting to try to work out a design that affords the flexibility to generate anything for whatever you’re studying but remains approachable and discoverable to your marginal Anki user, many of whom are younger and have varying levels of English ability. Many interesting technical challenges as well.
Slowly building towards the Show HN post, but need a few more features. Connecting with and chatting with dedicated users in countries around the world over the last few years has made this the most gratifying thing I’ve ever built! It’s still at the scale that receiving support emails is fun and I can build relationships with power users and long term subscribers.
Tula shows your true cross-venue exposure across HyperLiquid, Aave, and more, what breaks first, and more.
It's a terminal tool. The experience is very similar to any LLM terminal tool if you have used one.
You can also add an agent and ask things in plain English. Live at: https://usetu.la/
[0] https://blog.janestreet.com/protocol-emulator-asic-competiti...
It's a native, resource efficient screen recorder for macOS. It supports HEVC, H.264, ProRes 422/4444, HDR, Alpha Channels and more.
- We have accumulated almost all the equipment needed to setup our FM broadcast. The main piece of equipment we still need is the EAS Decoder.
- Our studio space build is in progress. I recently welded some tables for the booth and found an old Orban Optimod for our airchain.
- We have over 80 shows and our roster continues to grow.
If you are in Los Angeles or love community radio please reach out.
Twent = Android AI Agent that uses your phone, connects to stuff, installs skills & MCP on-demand, remembers things, and is highly proactive.
Playable build: https://piinecone.itch.io/today-i-will-destroy-you
I like to make videos involving lots of kinetic text that is synced to audio but they always took ages to make. This was an experiment in ai assisted video editing with a strong feedback loop so the agent can self correct.
It's also my exploration into using local models and rendering to keep as much as possible on device. Over time its grown into something pretty useful so I decided over the weekend to release it generally.
Last year, Mozilla released Orbit, an AI-powered browser summarizer hosted on a GCP server. After people started digging into the extension, they discovered things like backend endpoints such as store_result. Eventually, Mozilla discontinued the project. For the past month, I’ve been trying to rebuild Orbit from scratch, but with one major difference: Apogee is fully local and privacy-focused. Apogee doesn’t send or store your data. It can directly connect to your local Ollama instance for inference. I’ve also added WebGPU integration for Chrome and Transformers.js for Firefox to provide faster, local responses.
It can summarize: Articles and websites, YouTube and Billie videos, Wikipedia articles, Hacker News and Reddit threads.
You can check out the source code here: https://github.com/darshi1337/apogee
Install Apogee:
Chrome: https://chromewebstore.google.com/detail/apogee/pgemlpomhkdc...
Firefox: https://addons.mozilla.org/en-US/firefox/addon/apogeeext/
Obviously it is far from complete. Would love to hear your feedback and suggestions!
Clusters ready to deploy you applications on. It is meant for companies who want their own private infra, but do not want to maintain it. It is multi cloud, with a focus on europe.
Our secret weapon is “Menno”: an assistant which helps you setting up the cluster and deploying applications. We use the assistant for handson demo’s and workshops and got some really good feedback on it.
US Energy Cost Explorer (https://energy-maps.com) is a free tool for exploring electricity and natural gas costs across the US. You can compare states, follow prices over time, and look at bills and energy burden. I work in energy affordability, and I wanted to make this information easier for people to access and understand.
MarketGround (https://marketground.io) lets you draw an area or choose a travel time around a location, then explore its population, income, housing, and nearby businesses. It also shows daytime versus nighttime population, which is useful when thinking about who might actually be around a potential store or restaurant during business hours.
MarketGround is a side project, and I’ve found getting it in front of potential users harder than building it. I’d be interested in hearing from anyone who has evaluated a retail or franchise location. What information mattered most, and what was difficult to find?
https://breaka.club/blog/why-were-building-clubs-for-kids
Have been running an in-school pilot over the last school term. Has been super insightful and led to a heap of changes to optimize UX. However, the biggest challenge has been delivery in this environment.
Trying to run a game in a browser on school iPads powered by really locked down networks has been challenging. Some school iPads will crash (out of memory) when launching the camera view, whilst others run flawlessly. We use a fork of Godot, and are constantly fighting to strike a balance between UX (increased parallelism) and browser device constraints i.e. a limit on how many web workers we can fit in memory.
In addition to our main (build and play your own RPG) experience, we also stream games direct to iPad. In particular a modded version of Overcooked! 2 that teaches kids to code — Overcooked itself was never even released on iPad. We've built our own Kubernetes system that spins up (a license limited number of) games/pods on demand backed by (time sliced) NVidia GPUs. This is literally running out of my home office. Despite the complexity of building all that, the Kubernetes and GPU time slicing wasn't even the largest hurdle. Turns out UDP is a no-go on the school network, so direct WebRTC was out the window. Instead we're using Cloudflare's TURN relay with TCP. Which much to my surprise, is holding up quite well.
Definitely a learning experience. However, kids are having a blast. Can't wait to roll this out further!
The app wraps whatever is playing on mac through device convolution (old radio, hifi system) - Room convolution (a bedroom, a forest) and adds ambience (rain, wind, waves) and Apples spatial processing - so it sounds like a real space.
For me - hearing the sound in a space really helps more than just the dry sound.
An E-ink bird frame for Raspberry Pi - with real-time bird detection by audio, fully local AI, driven by BirdNET-Go rendered as real, hand-cut 1800s bird illustrations.
The idea is to help developers multiplex agent sessions and run Claude and Codex together, which is much more powerful than running one or the other alone.
My secret goal is to figure out how to make software development the kind of focused, meditative work it used to be.
Very happy to get critical feedback from any HN'ers: jake@clor.com
I originally built this around 7 years ago in Vue2 and Bootstrap as a simple static frontend tool to generate common ffmpeg commands.
I recently ported it over to Vite/React/Tailwind via Claude (Opus 5) and thought it did a pretty good job. So refreshed it as a version 2.0.
Quite impressed how fast AI was able to port this over. It made me think about revitalizing some old projects. :)
The app is very customizable, local-first and is built to adapt to what you want. Goal is to combine habit tracking, health logging and journaling into one fast and easy to use interfact.
Have been working on it for almost years now and it's making great progress.
Doing closed user testing right now and will release an open beta soon: https://dailyselftrack.com/
My Astro Web Starter is built for building well-designed, performant and accessible websites. It contains everything a high-quality website needs (In my opinion). I built it so I have one good base on which to start my web projects on. Using basic HTML and CSS that can scale, without bloat.
There's a lot more on it which you can see here: https://starter.bryanhogan.com/
They are sorted by predicted aesthetic rating and can be filtered by time of day, color, orientation, and park.
You can see how it’s going at https://joshkaspar.github.io/vistarium/
A habit tracker that allows for more flexible goals than daily ones, such as N times per period.
Hope that is no problem that I use this thread a bit for self-promotion. If so just write a reply I'll remove this comment if this is a problem
README is very bare bones, needs a video or a picture too. The website should tell you some more things: https://kavla.dev (and now the demo does not require a login (also need to remake the demo to fit the new self hosted version))
It's still lacking an analytics agent for the local version though. I've explored using codex CLI, but it feels like its extensive system prompt cripples the agent a lot vs Kimi 2.7 that I've been using in the cloud version.
I think it would also be nice to lean into the fully local LLM setup too, especially for data that shouldn't leave the device.
I got so fed up with my support system, and after years of using tools like Intercom, I built my own platform with everything I've ever wanted in a support desk. The biggest upgrade for me was the MCP connection. I can pull down a ticket with a bug and solve it with Claude (or Codex) and get the agent to fix and then draft a reply in my own voice. It also allows customers to connect their agent to my support desk and ask questions. This would be agent to agent with a human in the loop. But the normal day to day stuff is mainly live support or AI enabled support.
It's an extension of a longer-running project (https://www.forth.news) where it exposes and organizes 100s of newsworthy primary sources -- statements, press releases, press pool reports, emergency alerts, etc, whether from press email lists, X/Twitter, Bluesky, RSS, etc. The web UI is similar to TweetDeck - and it sends notifications.
Latest update now allows some panels to be based on an LLM prompt (i.e. "everything about the Iran War and its effects in the U.S.") which searches the entire catalog of sources as they are posted.
It lets you build apps and features that work natively across web, desktop and mobile, streaming from your backend into your client app, letting you deploy changes instantly.
A Hypen client can be any app that includes Hypen SDK, letting you render apps inside apps, build backend-driven features or create a mini-app platform like WeChat.
The framework supports many languages, such as TS, Rust, Go, Kotlin, Swift and pretty much any language that can run WASM or interop with native.
--
To give you a taste, some things in the upcoming release changelogs are:
- Performance improvements brining the web client on par with React (even faster in some cases)
- Exposing states and actions to agents, letting agent drive the app directly instead of through UI
- First class drag/drop support with pinning as a primitive
And some recently released things:
- First class accessibility support, with out of the box inference and minimal intervention
- Animation support with simple DX for animations, scrubbing, state and screen transitions
- Video component and a whole Netflix clone Hypen app example
- UI Testing suite so you can easily preview how your app looks like across devices
Next up on the feature list will be device communication and permissions, Android TV support, theming and external component installation, letting you build shared component packs and primitives.
MIT licensed and available on GitHub
I wonder if Claude Code could do this. That's a useful metric for the future - if a coding agent can't handle the breaking changes in a package upgrade, it's the package's fault. The day may come when that's something Github Actions checks for pull requests.
Would be good to keep track of how long it takes you to complete, so you can compare it with how long it takes Opus and then Fable to accomplish the same thing.
I should have. All I have right now is a free Cursor account and Github Copilot. I've got to start spending money on tokens and get up to date. That article today by Carmack chewing out game devs for hand coding was striking, considering who he is and how much low level stuff he has done.
I'm doing 3D rendering in Rust. (Think three.js, but in Rust.) This is well outside the mainstream, so there's not much on the web to populate training sets. A year ago, AI coding tools could not cope with this area at all. Today, maybe.
I have no idea how good Claude is at understanding breaking changes to an API. I expect it would get simple changes, such as structure field renamings, without any trouble. But the gyrations required to handle write only access to GPU memory in Rust might not appear in the training data.
The existing Github alternatives...look like someone drawing Github from memory.
   [1]: https://disc.sh / https://disc.md
[2]: https://social.coop/@netopwibby/117227113793136781Snippets manager. Fully local, 100% free, ~5MB binary. Open-source.
AI-assisted development. Not vibe-coded.
Parliament of Owls, Pounce of Kittens, Murder of Crows - the terms of venery are for animals.
But what about other things?
What do you call a group of Roses, or Snowflakes, or Lawyers?
Well, I couldn't figure it out, so I put it to a vote.
Simple ELO scoring, Endless mode is always on, and there is a Daily Contest for you to compete in (Wordle for wordsmiths, I guess).
I'd love to hear any and all feedback on it.
I posted Million Short 14 years ago to HN and the search engine has been largely the same since then. Now working on a pretty major overhaul: Launching our own decent sized independent index along with some (I think) cool & useful features.
The search requires a paid account currently although I plan to post a Show HN soon that won't require any account or payment.
The site https://tanssi.io
I'm currently in a job search and wanted to automate it for myself and learn the AI stack.
If anyone wants to try it out lmk!
A new UI library made with zero dependencies (native web components). I just made it public as I actually use it for my personal projects since past year.
The core principle is to help with UI development without bloating a project. It works with vue/nuxt (tested, my projects are done with it), but also react/angular/svelte/etc.
One feedback I got from reddit (I published it this week there) is that AGPLv3 may be a problem for adoption... still not sure if should I use MIT.
You add profiles from Instagram, X, TikTok, LinkedIn, Facebook, or YouTube and Narro pulls in the posts.
If either of those are interesting to you, please reach out!
For example, I am helping some restaurants learn exactly how much each item on the menu costs, what the margins are, and how much profit each dish is bringing in because I integrate with their PoS system.
It's all a part of GetSetReply which is turning into a small suite of tools for SMBs
my goal is to offload phone videos (to free up device space) and persist them in self controlled storage. the convention makes this significantly more useful than a collection of object paths
It’s an AI Private Investigator that does the hard work of data gathering (using Open Source Intelligence) and correlation. Used by over 70k investigators including government agencies.
https://dstld.news - I have always wanted a personalized news site so I built one using a few news APIs with AI summaries.
https://hn.wreet.xyz - I'm a big fan of skeleton.dev and wanted a HN frontend with all the fun themes.
Nothing too exciting, just trying to find the joy in making again.
- an open source AES67 hardware receiver/decoder - based on my friend Jessie's work [0]. I want speakers to have ethernet ports and to use an open/inexpensive stack. it's hard because physics/timing are brutal (1ms sync is ~not enough), but that's what makes it a great problem.
- an open source embroidery machine - based on my friend Owen's work [1]. Owen found Brother PE-150 machines which are readily available on eBay for ~$100 as they only work with proprietary 90s-era CF cards which nobody has (or sell for more than the machine). he designed a replacement motherboard (!!) and is running a fully open stack. it's wild.
- a ~$20 tiny cute display you can have on the side of your monitor, and display things on - realtime airport view from flightaware? a mini terminal? you can grab a display today [2], all that's missing is a 3d case (email me for firmware/OS code! I'll share it, just haven't had time). friends Frank and Sophie are working on a similar GUD-compatible display as well! [3]
- my friend Antoine has been working on Python bindings to Canonical's dqlite, a distributed sqlite-variant with raft-based failover and transactions (only C and Go clients existed) [4] - this will soon be a structural ("load-bearing"! haha!) part of Disco, a project we've been working on for a few years which lets you run your own PaaS. we're growing and get nice love letters [5] which for an open source project is obviously deeply rewarding
[0] https://jessie.grosen.systems/projects/aes67-receiver
[1] https://owentrueblood.com/blog/2024/12/10/reverse-engineerin...
[2] https://www.waveshare.com/rp2040-touch-lcd-1.69.htm
[3] https://bsky.app/profile/sophie.engineering/post/3muxysxhpck...
- Minimal setup - Any agent harness - A session is an actor - Opinionated infrastructure - Performance on the critical path
I’m spending like $25/mo at least in GHA minutes.
Then working on securing and tinkering with my homelab. And little utilities that make repeated deterministic functions easier for me and agents.
I don't even know what that means.
I was curious about formats more efficient for agent communication than JSON and also proving if the framework I curated could handle the load and traffic.
It's been really fun to observe.
It's a personalized & data-driven typing application that targets your weak points
1) bad apple on my kernel (OS)
2) language model + inference engine from scratch
3) sketchdaily.net, but you give it your own pinterest board of references instead of the preselected ones they have
Each week I research one part of retention, teach it, and apply it to two real-world products I built.
I’ve published five lectures so far, and think the series should be useful to anyone here building a product: https://www.youtube.com/playlist?list=PLFp5nmjrQeug
Added models and pricing there recently too. Aiming to be a huge place for all GPU data when it comes to mathematical performance. Things like FP8 for AI inference etc.
Tempted to make the infrastructure a bit more sound.
Aside from that I'm working on https://solarable.org - which is aiming to provider understanding of solar panels before finding an installer and plotholes.app (https://plotholes.app) which is a consensus network for potholes as reported and determined by cyclists.
Since last month, our four Google Summer of Code interns finished their projects.
University of California San Diego has deployed our Wayfinder and Waystation web apps for their 35,000+ students!
We launched a redesign of our Android app.
Our next-generation server software, Maglev, is almost at v1.0!
We are always looking for more developers, biz dev, ux designers, product managers, and more to help out!
Open volunteer positions: https://ossvolunteers.com/organizations/open-transit-softwar...
Our software: https://github.com/OneBusAway/
More about us: https://opentransitsoftwarefoundation.org
It has 2 modes, driver and navigator, that work like the driver/navigator roles for a human/human pair. In driver mode, Opair is similar to other harnesses but with less autonomy for the agent. In navigator mode, Opair has no access to writable tools at all. Instead it monitors the project directory for changes as you make them in your regular editor, and comments on them in real time.
Why? Because big changes are harder to understand if you're not directly involved in working on them, and I want to understand the codebases I work with. I use it as my daily driver and it's perfect (for me). I recommend everyone should consider writing their own harness. When you spend so long working with something, it's nice to have it perfectly tailored to your needs.
I've also written a plaintext to QTI quiz converter since creating quizzes on Canvas is so slow (I realize, of course, many other people have already made these... I just happen to like mine). It currently supports fill-in-the-blank, multiple choice, matching, true/false and word bank style questions. You can also generate a printable (DOCX) version of whatever quizzes you make.
Here's the site: https://www.hacksforeducators.com
All the tools are free, and there's no login required. So if you are a teacher that uses Canvas and think any of these tools could help you, check them out!
A copy utility that can efficiently deduplicate as it copies, even when the filesystem structure is different. Whilst there are many utilities that can deduplicate, they often either rely on files being on the same filesystem, or having the same structure. If a duplicate is detected, it can either be omitted or hard/soft links created to files in one or more reference locations. In practice I have found this to be invaluable for merging and efficiently consolidating multiple hard drives with partial backups of photos and music, maintaining the complete trees of all sources on a single destination, or only copying files that are new.
Secondly, an efficient protocol for text applications over a network. Think a combination of TN3270, SSH and JavaScript, with a very lightweight client/server architecture. Whilst SSH is great, latency kills many practical applications - this attempts to solve that. It also intends to make applications very simple to implement. As a proof of concept, I implemented a simple forum with login, optimistic posting, quoting, a text editor with mouse support in about 600 lines of code. The protocol, client and server themselves are agnostic to any particular UI toolkit.
Thirdly - microfish, poor person's microfiche using laser printers and autoencoders to preserve readability and machine recoverability of high density prints. Since consumer digital archival media seems to be dying...
Built for myself and my companies, OSS, maybe looking for a founder if anyone wants to make it be something, I got enough things to run heh.
It’s not a general coding tool, shortest description would be “personal/company data/process management layer” or “everything a company may want an on-prem datacenter and admin (dev)team for, accelerated by AI”.
Came from finding bug shortcomings in OpenClaw/Hermes where it’s not really close to having everything needed to organise and deal with big data in a safe or efficient way.
Basically the bottleneck is building a massive amount of software around agents which won’t happen in an all-in-one harness, this attacks that problem
https://github.com/AttemorySystem/spire-agent
A retrieval engine that using attention to retrieval, achieved several SOTA results on multiple benchmarks(LongMemEval, LoCoMo, code search, etc)
Simple digital signage without subscriptions. The goal was to help reduce some of the challenges with updating signage based on images and videos using low cost devices.
Started as a side project roughly when the PI3 model B+ was released. It wasn't until PI4 that it felt fluid and functional. PI5 devices are ideal configuration.
The memory price increases have made the devices too expensive to be called a low cost solution anymore.
I will seriously consider adopting it as long as it supports streaming matches (it seems like it does).
I use Claude Code and Codex for coding but don't want my regular chats in those apps. I prefer to keep all my chats in one place so I can go back and search easily, that is why I built Vinaa.
Nowadays I'm more curious about how I can use AI for marketing. I'm experimenting it with building an SEO agent system
AI can make a good one-off character, but keeping that same character consistent across dozens of product illustrations is still surprisingly difficult. That’s the problem I’m trying to solve.
Would love any feedback.
Latest updates around audio processing and quality are out, I've also made a substantial addition by implementing extensions.
This allows people to hook up to M365 or Google to get desktop notifications to start the recording, it can also export to share point and stop the recording at the registered meeting end.
Was a fun process keeping the offline and online functionality completely separate, also getting validated by Microsoft for the M365 extension was a bit of a chore, but finally have the verified blue tick.
https://getsoftwarehouse.com - I'm also working on the governance layer for AI tooling that is being built by employees, there's just HTML files flying all over the place, no security, no home. So built software house as a place for these things to live, be secured, put OIDC in front etc. It's fun!
The goal is to have a very fast terminal mail client where you don't have to wait for any operations and that is tightly integrated with notmuch(a common mail full text search engine) tagging engine, and other workflows(like crm queues and ai summary's if enabled in the config).
There is a document that explains why it was made in go. It has the best notmutt cgo bindings, and there are other reference terminal clients I can use as reference. althogh himalaya(rust) also looks interesting.
I would love to get some help with it, but I don't know where I should post it to get people interested.
I believe it is the first eCommerce platform where all the products have date as an important feature and where the search and navigation are by date - the thinking being it could help people find interesting and original birthday presents and anniversary gifts. I've also built it as a multi-vendor platform so it can hopefully live on once I've sold my things. Note that I'm the only seller and it is all UK based at the moment, but it has just been launched.
I've a blog post with more info at https://michael-lewis.com/posts/vintagepresents.com-date-bas... if anyone is interested.
Built this 18 years ago. Flash arcade game engine. 10,000+ games built by users on it. 2+ million plays. Lets you build mashups of classic arcade rules like Breakout+Space Invaders as one example.
It's been unplayable since Adobe killed off Flash. It uses a lot of dynamically loaded remote assests so Ruffle hasn't been able to run it.
Recently had Claude Code fix the Flash client so it would work in Ruffle and then had it convert the code to haxe (let's call the haxe version v2). It was an interesting conversion because Claude made a lot of wrong assumptions about how the engine worked so had to have it test every feature and match parity between the ActionScript version and the haxe version numberous times and play test it all. It's pretty close to parity now but still ironing out kinks in the engine. The existing engine art is very 2010esq.
On the game editor side converted it (it just re-wrote it) from ASP into JS. Now with an AI agent to help configure the settings and generate fresh artwork in additional to the manual editor.
The art has some very specific rules about orientation etc which the pixel art generation models seem to struggle with a bit but getting that aligned as well.
It lives again!
Trading Results as a service.
Our philosophy is Capital protection first, so we focus on protecting capital and managing risk while trading, and avoiding large losses enables compounding and high returns in the long run.
Infused with my co-founder's three decades of experience in trading & finance.
We don't want all your money. We want to be part of your diversified portfolio, which should also consist of other things like index funds, bonds, etc.
Initial allocations will open within the near-term future. For the founding investors (as we call the first clients), we also offer a portfolio review to align your portfolio with your long-term goals, a direct line to founders, and other things.
It's a breathing app that uses your phone to recognise and measure breathing in real-time. Breathing also drives interactive visuals, e.g. fluid, cloth sims and soft body sims.
I have been meaning to make an Android version, but as an interim I started building a web version of simple breathing patterns here: https://lungy.app/breathe/
I’ve always had the same problem with website blockers: I might need YouTube for a tutorial related to what I’m working on, but allowing YouTube also means allowing every unrelated video. Same with Hacker News - I might need to look something up for work, but I shouldn’t end up reading the front page for the next 30 minutes. Most blockers operate at the domain/app level, but whether something is distracting really depends on what you’re trying to do.
With Nono, you describe what you intend to work on at the start of a focus session. It then uses an on-device model to look at the active window in that context. So a relevant YT video can stay open, while an unrelated video gets blocked.
The tricky part right now is the model. It needs to be small and fast to run continuously, while still being capable enough to understand the context and not annoy you with false positives.
ai slop is an instant turn off for me. i would never be convinced with such low effort website.
While that's been frustrating, most my fun has been on the non-tech side. To get a break from the computer last year, I ran the length of Japan (around 3,400 km). And now I've been helping my partner edit the videos and stick them on YouTube:
https://www.youtube.com/watch?v=50oQQThXWnc&list=PLVFWiVG-hZ...
It's just a fun game but can be useful for people wanting to get a better sense of what the real estate market is like at the moment.
I should really have added a bunch more games by now but I've been sidetrack. Mentioning it here has already given me a bit of motivation to do that now.
Any feedback will be much appreciated.
I set out to solve that with https://stayupfront.com and now that the build is in a good place i’m finally having to bite the bullet and learn marketing. I’m also realising that all the advice to start with marketing first was probably good advice!
It is a React-based OSS audio player I developed primarily for museums and tour guides as I am really close to this industry and i was trying to scratch my own itch. In practice, thanks to the flexible design and architecture, it can be used for any use-case where you need to deliver sequential audio. Would like to hear any feedback or connect with someone who would need a solution like this.
Really exciting stuff is happening literally every month, because underlying models are getting better and better. When I started it was pretty basic: “make a cube with a hole through it”. Now it’s at the point “make a raspberry pi 4 case” and the agent searches, builds, verifies…
What surprised me in this process is how little meaning AI benchmarks have. Pareto frontier for my use case looks completely different than any other benchmark portrays.
Personally, I’ve had the most success with GPT models using MCP servers for this task.
The way it works is you play a game of valorant, or cs2, then after the match you're able to look at the times where you missed your shot, enter our AI aim trainer, and it boots up that exact same moment, with enemies following their exact same pathing, with gunplay feeling as close to 1:1 as possible with the game you're trying to improve on.
It figures this out 2 ways:
Firstly is purely based on visual clues, I have a custom trained vision model to detect the enemies, and a great algorithm to look at a minimap to infer exactly where the user's position is.
Alternatively if the user can download the replay file, we can decode it to grab real time positions / timestamp times etc to perfectly replicate exactly what happened in the match.
Posted on reddit / x about this last week, got some positive feedback, here it is if you want to see an early prototype:
https://www.reddit.com/r/AgentAcademy/comments/1w965a9/feedb...
Most recently I shipped an MCP server (w/ OAuth sign-in) recently to expose the API a bit better to agents, a TypeScript SDK and rewrote the CLI to use it. Also been reworking the terraform provider to cover the whole OpenAPI spec's surface area.
Just before LLMs became a thing I took the time to rewrite from having a private GraphQL server + public REST API to just using the REST API to build the product, super glad I did.
Seems I can't even selfhost your product either, which is a huge redflag in my book.
Those are the competition! There's never a good reason to not have alternatives available.
I'm not sure if this is intentional, but your comment comes across as a little disparaging, when individuals are sharing things they've built with passion, often in their spare time.
You might want to spend time figuring out how to keep your status page online when your hosting provider goes down, thankfully for the business, others don't.
There may be many others like it, but this one is built differently: https://maxrozen.com/lessons-from-my-third-year-running-a-sa...
An agentic system which scans a whole countries political decisions. Wrote a blogpost about it here: https://lorentz.app/blog-item.html?id=scanning-sweden
Reusable on any country's political system as long as they have legal mandates to keep political documents public (most of EU). Still a long way to go, but pretty in a pretty decent shape already. Wrote it for the Swedish election, but didn't get far enough for it to have an impact.
Will continue with for Finnish elections 2027 (on new domain).
https://gitlab.com/prbs23/freefall_800
The smoker hardware itself is pretty good, but like most IoT devices, the firmware and app sucked. So I reverse engineered the whole control PCB, and have been rebuilding new open source firmware from scratch. All the basic functionality is working now with a fully local control web app. Plus an Andoid app, and Home Assistant integration.
Currently working on interface refinements, and some more advanced control sequencing features.
I wrote up all the reverse engineering details in a blog post here: https://www.prbs23.com/blog/posts/reverse-engineering-gravit...
Find single long-period mono-transits in public TESS light curves — the single-transit events that periodic pipelines (SPOC/QLP, which fold on a period) structurally under-find. Built so many people can each search under-covered targets and combine machine-readable finds.
I usually search 5k stars each run, you have to be lucky to find something, would you give it a try?
I built it because I wanted to see if there's merit to the idea of incremental reading[1] and it worked so well that it turned into the main way I read things now.
The audio itself is in delivered with the restored classical Latin pronunciation and contains spoken nuances like vowel nasalization, elision, and prodelision. I used a wav2vec2 model to generate forced-alignment data, so you can easily follow along with the text as it's being read aloud. Each word in the text is richly enhanced with pedagogical details like: lemma, citation forms / principal parts, morphological segmentation and analysis, inflectional class with complete declension/conjugation tables, verb category, contextual lexical information (i.e. specific L&S sense), Classical Latin IPA pronunciation, UD style syntactic function and relations, predicate valency, and concise English definitions. Spoken instances of elision and prodelision can also optionally be displayed.
From a nerd perspective, one of the things that makes the system interesting is that the documents themselves are entirely in XML, and I use the soon-to-be-removed-everywhere in-browser XSLT feature to render the HTML, so you can see the underlying XML structure if you view source. Each sentence in the text contains provenance records so you can see the language model and parameters that performed each language enrichment task. The site UI is largely bilingual, and you can view it in either Latin or English.
Mostly this week I’ve been wrestling with a better solution to filtering openrouter providers because a common failure mode is getting stuck on one which is either very slow, or doesn’t actually meet the spec it promises in terms of tool calling.
https://github.com/kulvind3r/GamingGaiden
Created this to replace the original Gameplay Time Tracker which was closed source and abandoned. Been improving and maintaining it for 3+ years now and it has found moderate audience in it's niche.
timetravel debugging and observability on steroids. Deterministic replay that works across operation systems and cpu architectures. 70% as fast C, record one one platform, play it back identically anywhere else. Fits inside apps you already have as an embeddable language.
I already partially covered the last few months of app development in this topic. But actually, its development took way longer, as only this iteration started in 2024. So it is the end of a long milestone— this launch date initially was to be a year ago, but I procrastinated and missed important for such apps holiday season
This year I was able to go way beyond last year’s backlog, and now I’m releasing a fully finished app instead of early access.
I’m proud of the result — a lot of overengineered stuff that is not viable in any commercial product, especially in what appears to be a simple CRUD app. For example: image loading from blur, unadvertised but very advanced DnD everywhere, natural language currency inputs with sorting, platform-agnostic quick add, and many more.
Its stack is also very fun: it has been running on the Cloudflare Workers ecosystem since 2023, and is powered by a custom Inertia.js adapter for Hono (that predates the official adapter by one month, lol), with Vue SSR. That all enables me to write old-school MVC with Vue as a template engine for views. It also proved to be very easy to work with and cheap to run.
With a tsunami of vibcoded beige wishlists, my weird app stands apart, for sure, but I’m unsure about its appeal to the average customer.
I’m building the UK’s ‘big data’ charity with some awesome co-trustees and volunteers. We undertake big data projects in service of human flourishing, collect and synthesize datasets from hostile actors or freedom of information requests, and collaborate with other charities to build useful things that facilitate effective coordination.
The context is that I co-run the UK’s largest and most active landlord review platform ‘Marks out of Tenancy’, and the data we aggregated and ended up being able to host and query did a number of incredibly high impact things:
- our system for identifying how many people lived in a property started getting used to find victims of human trafficking - our system for checking for HMO licensing got picked up by councils to detect 100% of illegal or rogue landlords in the scan area, as well as detecting illegal short lets. - our longitudinal data collection on housing conflict between tenants and landlords directly led to increasing the rent repayment order threshold in the renters rights act from 12 months to 24 months.
So after seeing how much data is out there ready to be used for advocacy - but just left untapped by a profit driven sector, and after years of experience as ‘activist data practitioners’ or whatever you’d want to call it, we decided to launch something that could be a home for those projects in the spaces we’re in over here in the UK.
We’ve already got some awesome projects underway and we’re excited to see how year 0 goes for us!
There's currently not a way to invert LaTeX engine output for bidirectional editing. So you can't easily drag objects around or interact with the page on LaTeX. That's what I'm setting out to change in the name of mathematical exposition.
I have more details on my plans here https://news.ycombinator.com/item?id=49689856
I've experimented with a few ways of making the editing realtime and I'm getting in the 10 millisecond ballpark on some edits, but I want to work backwards from the light speed path to see what it takes (besides a lot of time).
It's a puzzle game -- numbers on a board -- where the gap between numbers dictates the arithmetic operation done to them.
The goal is to use all the spaces on the board to make sums of 12.
Have shared it a few times on HN already, but keen to hear from anyone who hasn't tried it yet!
I hit a plateau with my learning, having used Duolingo + tutor. It was only until I tried to read a book that I felt like I was making real progress. Highlighting words in Kindle, exporting them to Anki, then feeding back my progress to my tutor was fiddly and not a good use of my time. Also practicing my speaking once a day wasn't enough.
So I built an app to help me. This app will: 1. Generate Spanish short stories using Claude pitched to your level, narrated with ElevenLabs 2. Every word/phrase you highlight becomes a flashcard. Flashcards use spaced repetition - words you find difficult come up more often per review 3. Chat with Lucía - a turn based conversation who is prompted with the words/phrases you have saved down
You get a use of all the features before subscribing (1 short story, 1 round of flashcards, 1 minute with Lucía), then it's a 7 day trial.
Would love to get some feedback, especially on the AI conversation, as that's the most challenging part of the app I've found so far.
Small UI feedback: the WORD LOOKUP sheet has UI design disease, i.e. imo too much text. I'd drop "WORD LOOKUP" and "CURRENTLY SAVING". Also behind the latter the current word is repeated (it's already the title of the sheet), so I'd drop that too.
Thanks for the UI feedback, will sort that today :)
Edit: And a second question: do you support exporting the studies vocabulary as Anki or csv/…?
it's a CLI toolchain with a code generator and linter.
I invested time into this because:
1. Go is a much less wasteful SSR solution than JavaScript.
2. Datastar + Templ + Go is a highly effective combination.
3. I wanted a set of tools that not only helps getting started with a project fast, but also allows me to make it easier to maintain, especially with coding agents.
v0.10.0 should soon move it out of alpha into the beta stage.
As many of us here, I sit too much in my chair during the day and I'm trying to stretch more often and strengthen my back/core muscles.
There are a lot of "free" apps out there e.g. Bend that are helpful but I was annoyed with ads and limitations so I built one for myself. Now I use it daily.
The app is simple, you have about 100 routines to pick from and you can even build your own from existing exercises. Each routine comes with simple images, a link to a Youtube video and a timer. There are a lot of 5 minute routines that are perfect for a short break during work.
There are no accounts and I don't plan on adding any more features unless highly requested by users. I've built this for myself but I'm sharing it here as others might find it useful. Any feedback is appreciated!
I started it as a quick proof of concept while my wife was in labour with our first child, partly to cope with the stress, partly I wanted to create a personal gift - tracking our journey together. So I needed, a simple way to caption the important moments of our life together with the when & where.
The goal was simple and fast, with everything on the device: no account, no tracking, no uploads. You can edit the captions and adjust the crop, then export or share. The first 5 photos are free, then a one-time $1.99 unlocks unlimited exports.
App Store link: https://apps.apple.com/app/id6753585464
Side note: This side project was also a second experiment: how far can LLM coding agents get on their own? I wrote the first version in Swift, then had Claude Code port it to Flutter. It did most of the work (rendering, geocoding, the in-app purchase flow, even driving the simulator to check its own screenshots). I think Opus 4.8 was the point when the agent become truly autonomous and my input became less needed.
I have slowly built out a set of tools for asteroid orbits and photometry (measuring how bright stars/asteroids are).
It is very rough still (Desktop only), and it only supports the FITs file standard.
Basically it is a full professional grade telescope processing pipeline in your browser. It does 2 queries to some custom databases to identify known asteroids and stars, but all image processing and calculations are done in the browser. This means the backend is pretty tiny. That said it is running on an old box in my closet, so queries may take a while if it gets hammered.
I built it since I have worked with quite a few astronomers over the past 4 years and I keep watching them do the same steps, purely built to make my friends lives easier. I wrote it all in rust and managed to compile it into wasm. With some help from fable as I am not a frontend guy at all, I built it into a small website.
Some of the code is public, the orbital mechanics code I wrote while I worked at Caltech. Which is being used on SphereX, NEO Surveyor, and the Roman telescopes to identify known asteroids. https://github.com/dahlend/kete
At the moment, even if you set up SSD for foreground operations and HDD only for background, more often then not, your write latencies are those of the HDD. We can do better.
See https://paquari.com/posts/bcachefs-ssd-hdd-progress/ for a progress report. (Disclosure: the write-up is an AI summary of my notes, so don't expect any brilliant prose.)
I'm also working on resurrecting stabilizer (https://github.com/matthiasgoergens/stabilizer). Stabilizer is a way to make program performance less dependent on the linker and layout lottery. But it has sadly fallen victim to bitrot.
I'm doing some minor contributions to other parts of Linux like ZFS and ext4, mostly as a byproduct of experiments I'm running for my bcachefs work. Another somewhat ambitions project is to make swapfiles on ZFS and bcachefs work (or work better), at the moment the problem is that writing swap on them might need to allocate memory exactly when you are out of memory.
We’ve been using it for a few months, so now I’m trying to tidy it up so others can use it too.
I love going to the movies, but I couldn’t find an easy-to-use way to search everything currently showing in Japan. Sites such as eiga.com offer only a few filters, while individual cinema websites generally make you search one location at a time.
Eigakan Guide lets you filter showtimes by area, cinema, date, time, and features like IMAX, Dolby Cinema, 4DX, subtitled screenings, and more. For example, you can search for IMAX screenings this Friday after 7 PM.
Another problem I often see people asking about is how to find screenings with English audio or English subtitles. English-subtitled screenings have their own filter. English audio is harder because cinemas rarely publish the audio language explicitly, but a Japanese-subtitled screening of a film originally made in English will generally use the original English audio.
The site is available in Japanese and English and currently covers every TOHO Cinemas and Cinema Sunshine location in Japan. AEON Cinema is next, with more chains planned afterward.
I launched it very recently and would really appreciate feedback, especially from people who go to cinemas in Japan.
It's an app to get sleepy without meds. Simply close your eyes and imagine the micro-scenarios you hear. Like if you hear "moonlight on a white flower", imagine that scenario until you hear the next one. Session duration is also not too long (10 minutes default, you may change the session duration too).
It's like a digital melatonin pill - but without chemical side effects. Try it!
- the TTS voice sounds way too excited for something meant to be relaxing
- the sudden speaking after 10 seconds of silence is very jarring -- I wonder if something like a reverse-reverb effect would be enough to "warn" the brain that a new sentence is incoming. There's an example of how to do it in Ableton on YouTube[0] but the basic concept is: take a short slice of audio from the beginning of the sentence, reverse it, apply a long reverb, reverse it again, trim the end a little. You get a sort of ghostly aspirated sound that leads perfectly into the original sample.
The recordings were made by my friend and Latin tutor. I used an Italian wav2vec2 model fine-tuned on Latin[0], which works pretty well for Latin only content, but falls down with mixed English / Latin. I found that some of the slower, larger Meta models worked fine for this use case though.
Some folks on the Latin language Discord said they got pretty good results using Kokoro TTS and X-Voice for creating synthetic Latin, as you suggested using IPA.
I’ve been building https://smalldocs.org, it’s a simply styled, but functionally deep, artifact layer for agents. It’s open source and free to use.
Because it can incorporate charts, diagrams, spreadsheets, etc. in one artifact, it’s good for creating (and optionally sharing) agent created analysis.
It has a local library for all your Markdown files, and a cloud library (my one paid feature) too. Both support tagging and rich search/filtering. I find it turns SmallDoc artifacts into little checkpoints in work I can easily circle back to.
Thanks for reading!
My summer project was to challenge existing 2D / 3D visual effect creation tools (touch designer, comfyUI, etc.) with something agentic as the true foundation (not just slapping MCP on top of an existing paradigm).
It also came from the following observations:
- people are making their own coding harness, why not one for realtime visual effects?
- using Claude code or codex to make art and installations is absolutely fantastic, but you usually end up with a lot of friction and paper cuts when it comes to deterministic workflows and concept iteration.
SubjectiveZero is the free and open source project that resulted from it. It’s still following the classic node editor paradigms but making the nodes absolutely more malleable while also combining a user experience flow optimized for ideation and iteration. I definitely invite you to check out the showcase and examples on the website, but basically it feels kind of magical when your editor just “get” what you want, and nudge your exploration into adding more little knobs here and there so using the tool feels more like playing rather than “operating”.
I also liked the emerging concept of an adjustable abstraction ladder, meaning people who are very technical can still get as much granular control as they wish to while people who just want high level concepts and vibes can just use prompts to try things out.
When it comes to determinism, the tool has some neat features like an agent graph to constrain agent workflows, overpowers MCP that drives user interface changes as the agent makes progress, allows the agents to verify their work and coordinate so the usual painful wait for agents to be done is somewhat minimized. There’s also a way to do basic model routing to tweak your intelligence/speed ratio.
I’ve personally used it to make art and fun experiments. Feel free to send feedback or contribute tokens to the project if the concept speak to you!
    {:find [?title ?director ?rating ?card ?shout]
     :where [[?m :movie/title ?title]

             [?m :movie/vote-average ?rating]

             [(str ?rating) ?rating-str]
             [(concat ?title ": ") ?title-colon]
             [(concat ?title-colon ?rating-str) ?card]

             [(lower ?title) ?lowered]
             [(concat ?lowered "!!!") ?decorated]
             [(upper ?decorated) ?shout]

             ;; joints
             [?cr :crew/job "Director"]
             [?cr :crew/movie ?m]
             [?cr :crew/person ?p]
             [?p :person/name ?director]]}
Rough idea: get a list of urls with classical music concerts -> send each one to a coding agent to build a crawler -> validate and run on an infrastructure for "free". Classical music is an ideal use case, because the number of concerts is small enough on an average website that it doensn't require many workarounds, and the websites are usually pretty crawler-friendly.
I started it because I wanted simple brain-training exercises that didn’t require an account, app install, or subscription.
It’s also open source: https://github.com/loethen/freefocusgames
Won’t that make it difficult to rotate your keys?
Keys should be something you don’t hesitate to throw away and rotate at the first hint of a compromise.
I think this is a good balance point, and I estimate that if we want to rotate the keys completely in the future, we should start using new key algorithms. (I estimate it will take another 5-8 years)
Yes, when certain situations arise, it is necessary to rotate the keys as soon as possible, but in the absence of such situations, losing key backups can be catastrophic.
It started with a family member telling me they were frustrated with existing websites. What I noticed is that in many cases they feel cluttered and not smooth to use, almost like a 1-to-1 translation of the underlying database queries, where they have you choose filters and sorting options upfront then browse the paginated results.
I wanted to avoid all of that by creating a different experience; I built an interactive full-screen wall UI with infinite browsing so that most of the screen space is dedicated to the core content. I worked on the name sampling algorithm to try to make it as enjoyable to browse as I could, and the only filter displayed by default is the one to select genders.
More advanced queries are available through the search field which supports natural language queries, running on a local multilingual interpretation engine with a cloud LLM fallback. The database engine is custom built with Rust, compiled to WASM for higher performance when running on CloudFlare Workers. I don’t use an external DB service for names today.
What I’m pretty proud of is to know a lot of technical work is hidden behind that UI, and how it has been shaped by the experience I wanted instead of the other way around.
It's a collection of daily games with some classics like crossword and sudoku, some geography games like draw the country shape and pick the country from a borderless globe, and a few more. Ten daily games in total.
Word Shift and Nine Grid are my the ones I enjoy the most. Would love some feedback!
- Puma, The terminal browser: https://github.com/meerita/puma-browser
- Kernq, a full replacement of lsof: https://github.com/meerita/kernq
- Entroq, modern lossless compression for modern systems: https://github.com/meerita/entroq
DoodleMate is a multimodal storytelling canvas that exposes students to the basics of animation, character design, and story creation. Starting from paper drawings, it creates rigged versions of your characters that can talk, walk, dancing, sing, etc and you can create scenes out of it.
It doesn't use any generative AI whatsoever. Just computer vision and animation algorithms.
https://news.ycombinator.com/item?id=49686888 https://agentspork.com/
Basically a simple pizza status tracker for small German fabricators and craftsman. You define the process, instantiate it per customer order who receives the link to a status page with a possibility to subscribe to status notifications as well. The benefit is that people don't call you anymore asking for the status of their order, saving time.
It's a pretty vanilla rails app running on a hetzner vps.
Been working on Feedbun for a little while, Elixir/Phoenix stack, with bespoke LLM fleets for production workflows. Recently just started using React Native (Expo) for the companion mobile app so I can use it when I shop IRL.
Also started working on a 2D strategy game using Godot engine, still super early days. Been fun to experiment with different LLMs capabilities on game development.
On the side, https://infrabase.ai (hand-verified AI infrastructure directory) launched a Media Generation category, image and video APIs after a run of requests for it. Also the submission spam is way up here latley, been improving the detection here as well. Also seeing real interest in paid listings now, including one that started as a link-buying request I turned down :)
Been doing a lot of AI assisted emailing, so I have started to work on a little review UI for AI generated text, comments on specific words, inline edits, Claude picks up both and revises in place. Like a PR review interface for text. Turns out pretty good workflow with Claude watching the files for new comments, editing and commenting back right away.
We created it as an alternative to the price gouging that happened over the last year at various timesheet SaaS companies. The idea is that good software should not cost 10x as much just because 10x as many people use it. In our opinion, software should also be functionally complete. There should be no arbitrary tiers that only exist to force people into more expensive plans.
The stack is Elixir with Phoenix LiveView, deployed on a Talos Kubernetes cluster. This is different from what we normally build on, and honestly quite fun.
Lately we have been thinking hard about the temporal nature of timesheet software. Many things get quite complicated once you factor in historical versions: the need to retire, lock, change, reopen records or rates, and so on. We have been working hard to polish Abejora to make everything accessible, user friendly, and intuitive.
It's mountaineering safety tool I've been making for my friends and I.
The fun part: if your browser has WebGPU, the page solves that field live as a compute shader (about 35 ms on an Apple GPU) as you scrub the timeline, and draws the flow over a 3D terrain view. Browsers without WebGPU get a precomputed field.
https://mattduran.dev/summitwind/
Ranges and uncertainty only, no go/no-go verdicts. That still requires your best judgement as a mountaineer. Next up is a free-play mode where you set the wind direction and speed yourself and watch the field re-solve.
It builds a scorecard from job description and mathematically matches candidates against it on every interview step, so that you know candidate fitness at all times.
You’d start a reading session and the dragon would read alongside you. What you read would influence its appearance and habits; lots of sci-fi might give it starry wings, for example. It won’t die if you go a week without reading.
The plan is to keep it playable offline, with optional syncing to Booklary, the reading tracker I’m building. I’m leaning toward C++, which I never used, so it’ll be a learning experience.
Currently waiting for the Waveshare board to arrive so I can start development, and looking for an artist to commission the pixel art. Used GPT to design a concept[1], which I’ll use as examples to the artist.
This will be my first ESP32 project, so getting the dragon blinking on screen is the first milestone.
[1]: https://i.cpimg.sh/57EC5380-0FF7-4646-A943-971350FF98D2.png
For ESP32 - recommend paying close attention to the FreeRtos, it's seriously powerful. Even if you are just using Arduino style code you can use it for background scheduling and interrupts (for your api and buttons for example), as well as dual core use on S3.
Currently building for myself and managing my own work with it, would vision something alternative for confluence.
Would love to have more collaborators helping to build an open source project - https://github.com/entangle-cloud/wave
It's like a fixed up TypeScript specifically tailored for Wasm GC that can produce very small and fast binaries, but also has features like pattern matching, ownership / borrow checking for resources, pipeline, tail call elimination, multi-value returns, direct WASI component integration and a lot more.
I have pondered cloning Caddy in TypeScript just because...would Zena be capable of this?
Research on which query language to use when performing search/query operations over HTTP — specifically in the context of the new HTTP QUERY method.
Use this research to figure out, for your own API, whether one of the 68 query languages analyzed here already fits the query content of a QUERY request — or whether none of them do, and you're better off designing a brand new, purpose-built query language instead.
It has the ability to generate a small notebook from a problem description using AI (still has a lot of room to improve), but the calculation uses a deterministic engine.
Right now I'm working on collaboration.
There are a lot of small languages in the world, and translation used to be extremely expensive. And there is never too much good space sci-fi.
(We don't write space battles or wars. Our style is slower and bit more philosophical. Light speed is the limit, and travel takes centuries.)
It's a news aggregator focused on furthering our understanding of how cryptography is evolving. We're aiming to monitor the people on the ground who are doing the actual work, and amplify them.
The front page is a curated low-volume stream, but there's an all-news feed as well.
After producing Feisty Duck's Newsletter [1] for 12+ years, I built this for myself to make my life [following events] easier, but decided that it might be useful to others as well.
Probably the most interesting thing about it at the moment is the editor. The world, and most things in it, are represented as collections of SDFs. More accurately, they're density fields, but, potato-tomato.
Bonsai has undergone a large rewrite over the last couple years that's nearing completion. A world edit is defined as a bunch of SDF parameters which get projected/rasterized into the voxel grid by a shader on the GPU. One neat thing about SDFs is they've been thoroughly researched and documented by a guy named Inigo Quilez, and they have a lot of nice mathematical properties. For example, you can do a smooth union of arbitrary SDFs to get nice rounded contours where shapes join.
I've written every system from scratch, all the way from the memory allocators and font rasterizer to the collision detector and simulation loop. I even wrote a metaprogramming language as a replacement for C++ templates, which is a whole other story. IIRC the only external dependency is the C runtime library for starting the process and my very occasional use of variadic functions arguments.
For a long time, an explicit non-goal of the project was to ship a game. It sounded insane to me to write an entire 3D engine and then ship a game. As it turns out, I've gotten it to the point where I can actually make a game. I've got a start on the game systems in a closed-source repo, and hope to have a steam page for it by the end of the year.
I'll do some shameless self-promotion and leave some links here for anyone interested in looking at the engine, language code, or some pretty pictures.
good luck with the game btw, is there anywhere i can follow development?
ShopSpec is a deterministic parametric furniture generator (bookshelves, cabinets, shop carts, leg-and-rail frames, multi-carcass composites) that encodes real woodworking intelligence and outputs shop-ready artifacts.
Most recently, introduced the concept of value engineering by sweeping across dimensions to batch evaluate candidates that ranks based on sheet purchases. Also have in beta an MCP connector to let agents explore the deterministic engine.
I'm building a number of items for home and shop and ShopSpec has been instrumental to plan, visualize, and execute on these new ideas/projects.
Was trying to combine AI with generative storytelling with a card game. It was a fun experiment. To play, you'll have to get a friend to queue up at the same time.
it's a weight-training app that helps you train along your "pareto frontier" of weight vs reps. The idea is to train at lower weight-higher rep, medium weight medium reps, and higher weight, lower reps for every movement. I tried to develop my own weight training program following bits and pieces of advice from bodybuilding forums and ended up injuring several tendons in my first year. So I did a bunch of research on tendon strengthening as well as what's most effective for hypertrophy (reps near failure) strength (reps near maximal load) and injury-prevention/frequency (not bringing yourself to failure too often) and designed an app to automatically prescribe and advance weights and reps based on your learned strength curve (Brzycki-like, with an added shape parameter)
The app is designed to make use of the free Cloudflare tier, so I can support thousands of athletes for just the cost of the domain name. I'm primarily interested in understanding the "Fatigue curve" - right now I have some basic per-set fatigue modeling (basically a log-linear strength dropoff) but I think it could be much better characterized with more data. I could go on and on about the modeling but my intention is to keep it free (maybe add some non-intrusive ads on content pages if it ever starts costing me a few pennies a month) but my primary interest is to be able to do statistical analysis on the data.
A UK-based flight deals service aimed specifically at parents who can only travel during term-time.
Having this issue myself now with two children whereby flight prices double going into school holiday season, I have always wanted some kind of service which alerts me of good deals.
I still have a long way to refining the actual product, but trying to fit the development around work commitments. AI helps obviously, and does 90% of the coding.
Result so far (paper, 34 trading days): the no-AI control is +13.0%, the S&P 500 is +3.4%, and 25 of the 28 AI accounts are below the control. The best single account is a Grok-written "patience" book at +40%, which I treat as one lucky account in a choppy market, not a finding. At the trade level the AIs and the control look the same: 3,212 closed positions, median +0.06%, median hold about 2 hours. They trade a lot and mostly go nowhere.
Everything is public, including the losses and the retired strategies: https://aitradingcompetition.com/which-ai-is-winning.html and the full trade file as CSV at https://github.com/ckamelhar-collab/ai-trading-arena-data. Paper money only, not advice, nothing for sale on those pages.
BongBong tank shooter game. My first game. I wanted to recreate a game that is kind of a mix between old Battle City (NES) and Dyna Blaster, which I used to play as a kid in the 90s. I wanted to have a game where you don't just have retro graphics and beautiful explosions with realistic physics, but I also wanted to capture map building and playing with your friends - locally and online.
I'm building it in Rust and Raylib, using modern agentic approaches. Both Rust and Raylib let me compile and run the game locally on Mac/Linux/Windows and in the browser via WASM. I've also managed to get it to run successfully on Apple iOS. I will likely venture into Android as well, as I want a game that works across platforms so people can play it regardless of their platform.
Any feedback whatsoever is greatly appreciated. :)
I didn't really know the rules, but enjoyed protecting the frog.
I played a few games, and each time was protecting the frog. I wished I had a turn trying to kill the frog!
iOS: https://apps.apple.com/us/app/introkeep-qr-connections/id679...
Android Beta:
Join google group by clicking "Join" - https://groups.google.com/g/introkeep-testers?pli=1 Click on "Become a tester" - https://play.google.com/apps/testing/com.nexaitech.introkeep... Install it from the Google play store - https://play.google.com/store/apps/details?id=com.nexaitech....
0) money-money-money: A sub 15Kb server-less opinionated household budgeting tool [0]. Why? Its made to be extremely compressible, so you can edit your household budget and share back and forth with your partner via short-links or QR codes. The idea is you edit your budget, send the link to other party, they can view or edit and send back to you without a server in the loop. [0]
1) slices: An alternative AI-first ADHD-friendly architecture experiment where everything you code is a "slice" with a shared event pool. A slice is a fully self contained "feature". Slices can only communicate with other slices through a shared event pool. Inspired by small-talk, vertical-slice architecture, and ADHD. I used slices to build a self-modifying IDE too. [1] [2]
2) text compression experiments: I'm experimenting with approaches to compress text in pursuit of the Hutter prize. The idea is to take the entirety of the English Wikipedia, and compress the text as small as possible whilst still being able to reproduce it. [3]
3) tiniest maze solving neural network: A write-up work in progress on a maze solver I built with heavy LLM help, managed to get a 14 byte neural network solving 96% of unseen mazes. [4] [5]
[0] - https://con-dog.github.io/money-money-money
[1] - https://github.com/con-dog/slices-demo
[2] - https://con-dog.github.io/slices-demo/
[3] - http://prize.hutter1.net
[4] - https://github.com/con-dog/tiny-neural-network
[5] - https://minimio.ai/
I'm working on fyai, a rather opinionated agent harness, built to work as a unix tool and the idea that eventually AI is going to be a commodity, where having control of your own data is what's important.
It is still quite alpha, but at a usable state.
The biggest technical difference between fyai and other harnesses is that in fyai the state is durable and stored in a disk deduplicated arena, which means that git like branching is free and storage requirements are very modest compared to JSONL/SQLite storage.
Latest additions has been full markdown/mermaid rendering support and (very alpha) Claude code and Codex session import.
[HUMAN-CODE] - code written by humans
[AGENT-CODE] - code written by Claude/Codex/Other agents out there
[HYBRID] - Combination of Humans/Agents
I would prefer to go through projects where people are writing code themselves. And this kind of tagging would help me filter through easily.
There's no reason to write code any more by hand, except as a hobby/fun/art or to comply with some requirement.
Frankly, it's surprising that we'd even need to stipulate something like this. It would never occur to me to post to a "show us what you're cooking" thread with: "Look what I asked DoorDash to bring me!", but I guess that's where we are now...
Github: https://github.com/athos2113/fillvisa-os
Demo: https://fillvisa.com/demo/
US Immigration still relies on outdated XFA PDFs - you can't fill them on your browser. Most immigrants end up printing the form and fill it manually.
So, I converted the PDF forms into smart web forms. They are replica of the official USCIS forms and follow conditonal logic. In the output, you get the official USCIS pdf form filled.
But, I'm guess it'll take some time
How would turning the PDF into JPG allow you to edit/write inside?
But overall it's a struggle, the site is still in Google jail/sandbox, so it's not even seeing any Google impressions. So most traffic is due to being very active and posting wherever I can.
I'm building a video game. It's part Valheim, part Ultima IV:
You can play the demo in the browser now (mobile as well as desktop), but I'll be packaging it up for Steam soon.
It's all vanilla javascript, html and css. No AI, no 3rd party game engine, no build system even, and just a couple external dependencies for things like networking that I didn't want to reinvent myself.
It's been fun. I'd love to get some feedback!
A multi-harness orchestrator running agents on your VPS, with a built-in issue tracker (like Linear) and gas town like communication system.
Agents can split up big tasks themselves into subtasks, run each with a different harness and model and communicate so they keep running for days until everything is completed and integrated.
There's lots of tools in this space, but our combination of agent-focused issue tracker and agent-to-agent communication is quite unique and, for our use case, delivers an actually working software factory.
It's still a little rough around the edges but we'd be super happy for people to see if they get the same benefits out of it that we do. It's free and open-source.
Palantir like system – data, ontology, logic, actions, security, operational workflows – packaged as single cli, local first, git friendly text .cave files and sqlite3 instead of k8s-style complexity blowup.
Working on the weekends.
Next is probably extension of the language to integrate something like https://github.com/mirek/ast for arbitrary ast traversals/modification/generation/better integration with external world - other file types, but ast concept goes further than that, ie. filesystem is also ast, traversal is ast/xpath like walk.
Public domain on all my recent work.
Anyhow it's basically just twitter but as a chat app. Everything is tag-based and there are no channels. Instead, users create and share lenses, which are just saved searches. That way, you can "speak in multiple channels" at once, or carefully filter out specific people or topics.
The best part is that I can speak, and then organize after the fact.
https://SourceLibrary.org is a hub that now provides over 20,000 translations of classical texts in dozens of languages (Latin and Greek but also Chinese, Sanskrit, etc). We always provide the original image of the text next to the AI translation (so if you don’t trust it, you can do it again). For a sense of scale, SourceLibrary now hosts more words than English Wikipedia!
You can freely connect to the public MCP for research; that way AI can read books and not hallucinate quotes. In Claude, it also retrieves images directly into the chat.
This is a philanthropic project based at the non-profit “The Embassy of the Free Mind” in Amsterdam, a rare book library devoted to free thought and mysticism. https://embassyofthefreemind.com
SourceLibrary is totally free and open source. If we can raise the money, we hope to translate 100k books before the end of the year.
If you want to dive in, I’d suggest trying our research agent with a rabbithole topic of your choice: https://sourcelibrary.org/librarian/
I’ll try to track down the ones you are looking for tomorrow. Yes, we avoid copyrighted modern translations.
Tritium - the legal IDE for desktop and web.
We're building the document viewing and editing layer for a number of AI native law firm startups.
Web preview: https://tritium.legal/preview
WASM example: https://tritium.legal/wasm
We actually offer source access here, too: https://tritium.legal/source
It's an approach to defensive security for software products (especially smaller companies) by acting as the security team you don't have/can't afford. It does security recon/analysis, etc via AI.
I got tired of all of the LLM labs building firewalls of "oh, nobody is allowed to do security research/find+fix vulnerabilities in their software unless they apply for special registration."
Instead of saying "oh, anything that the model determines is security research is a vulnerability threat", it does reliably enforceable analysis like "look for a TXT record in DNS the same way a SSL provider would ensure you own the property". So it can do "live" penetration tests against your infrastructure if you provide authorization
It handles things like incoming "security researcher" e-mails to cut down on the noise of nonsense vulnerability reports by acting as your security team that defends against the reports
It provides provable/signed attestation that a pentester has checked your code/live infrastructure/APIs/etc and validated them, and/or has done a check after you've remediated whatever issues that were found. It helps all 3 sides of the "company needs pentester" and "pentester" and "auditor"/"customer" to come to agreements on what's important and what's been solved
- I am implementing my own MCP server in Go for Bitbucket. This is more of a learning project for me (I was curious about MCP servers), but I also didn't find any MCP servers that have a clean codebase. Many seem to be vibe-coded, and as I work at a company where security is really important, I thought I would implement my own. (Still a WIP: https://github.com/pid0x17/mcp-bitbucket). I haven't touched this project in a while, though, as I am focusing on Nand2Tetris.
- I am reading the Rust Programming Language book, but I am still in the beginning (just finished Chapter 3 on the weekend).
I was very intimidated at first because the concept sounds very difficult, but Prof. Schocken and Prof. Nisan are amazing at breaking down the concepts and abstractions and making something complex very easy to follow and understand.
To signup you don't provide any information (a randomly-generated account number is assigned to you), and you can run a proof-of-work captcha to get 2h for free. You can choose among many different search providers (for defaults and per query), including Uruky Site Search, powering our own index.
Last month we reached 300 monthly active accounts and released an image search gallery mode, plus a simple calculator and conversion widget!
The main differences between Uruky and Kagi, DuckDuckGo, SearXNG, etc. are visible in the footer (right side), but one huge difference is that with Uruky, after being a paying customer for 12 months, you get copy of the source code (licensed as BUSL, into AGPLv3 in 2 years — a suggestion made here on HN)!
Our main challenge continues to be discoverability and outreach because we want to do it ethically (no Big Tech and no GenAI/LLMs). Ideas are welcome! We’ve been sponsoring open source projects, open source maintainers, and indie, small-web, and privacy-related websites and applications/groups/orgs. This month we're sponsoring NOYB [2]!
Feature-wise, for September the most visible things that shipped already were Tags and Scopes (top feature requests for a while). We’re also still (slowly and sustainably) increasing our own index, focused on indie/small web.
Thank you for reading this!
[NO-AI]: There is no generative AI product or service being offered, here.
[1]: https://uruky.com
[2]: https://noyb.eu
There's a huge database of licensable animations that several apps I've seen use. E.g. take a look at the animations in Hevy. I forget the name of it now but you should be able to find it easily.
The website could use some images/simplification to get going and then have more details and whatnot later on. It seems that you let the LLM generate the content itself (em dashes, emojis) - Personally I'd be skeptical of a fitness app that has most of its content LLM'izied.
On step 3 of the tutorial, it's not clear that you can scroll down and there's more there on a mac 16''. I was confused what to do. It didn't allow me to change to metric system either (which I later found in the user-settings). You can't 'esc' from the tutorial popup either.
What exactly is your "research"? Is it reading more bodybuilder forums (bro science) or is it physiological studies (actual science)?
One AI might consist of some convulated strategy of who knows what, but all it takes in the end is for it to say...hold more tech stocks than not, or buying more call options or leveraged positions in a bull market, being more out of the market during a bearish market, etc. But that same strategy will fail miserably as soon as the market conditions change
come back when you put it real money and have some skin in the game.
Primarily by sharing the web version (fillvisa.com) on subreddit and FB groups. People complain about the USCIS PDF regurlarly, so, I just pitch them the website
Personally I think hobbyists that think they can second guess institutional finance are just fooling themselves.
Agreed on 2nd point. Especially with no real hypothesis i.e. just throw AI at it.