[1] https://storage.ghost.io/c/b8/53/b853e3d4-3186-409d-9c7f-7da...
Disclaimer: I cut it off after a few minutes because I got impatient. It could have gotten closer if I waited longer.
Doesn’t Gemini or whatever Meta’s agent is do this too?
https://support.mozilla.org/en-US/kb/introducing-total-cooki...
Everyone would be far better off if the author just posted "OpenAI uses third party cookies [wikipedia link]", except maybe the author who wouldn't as many subscriptions for his "threat intel" newsletter.
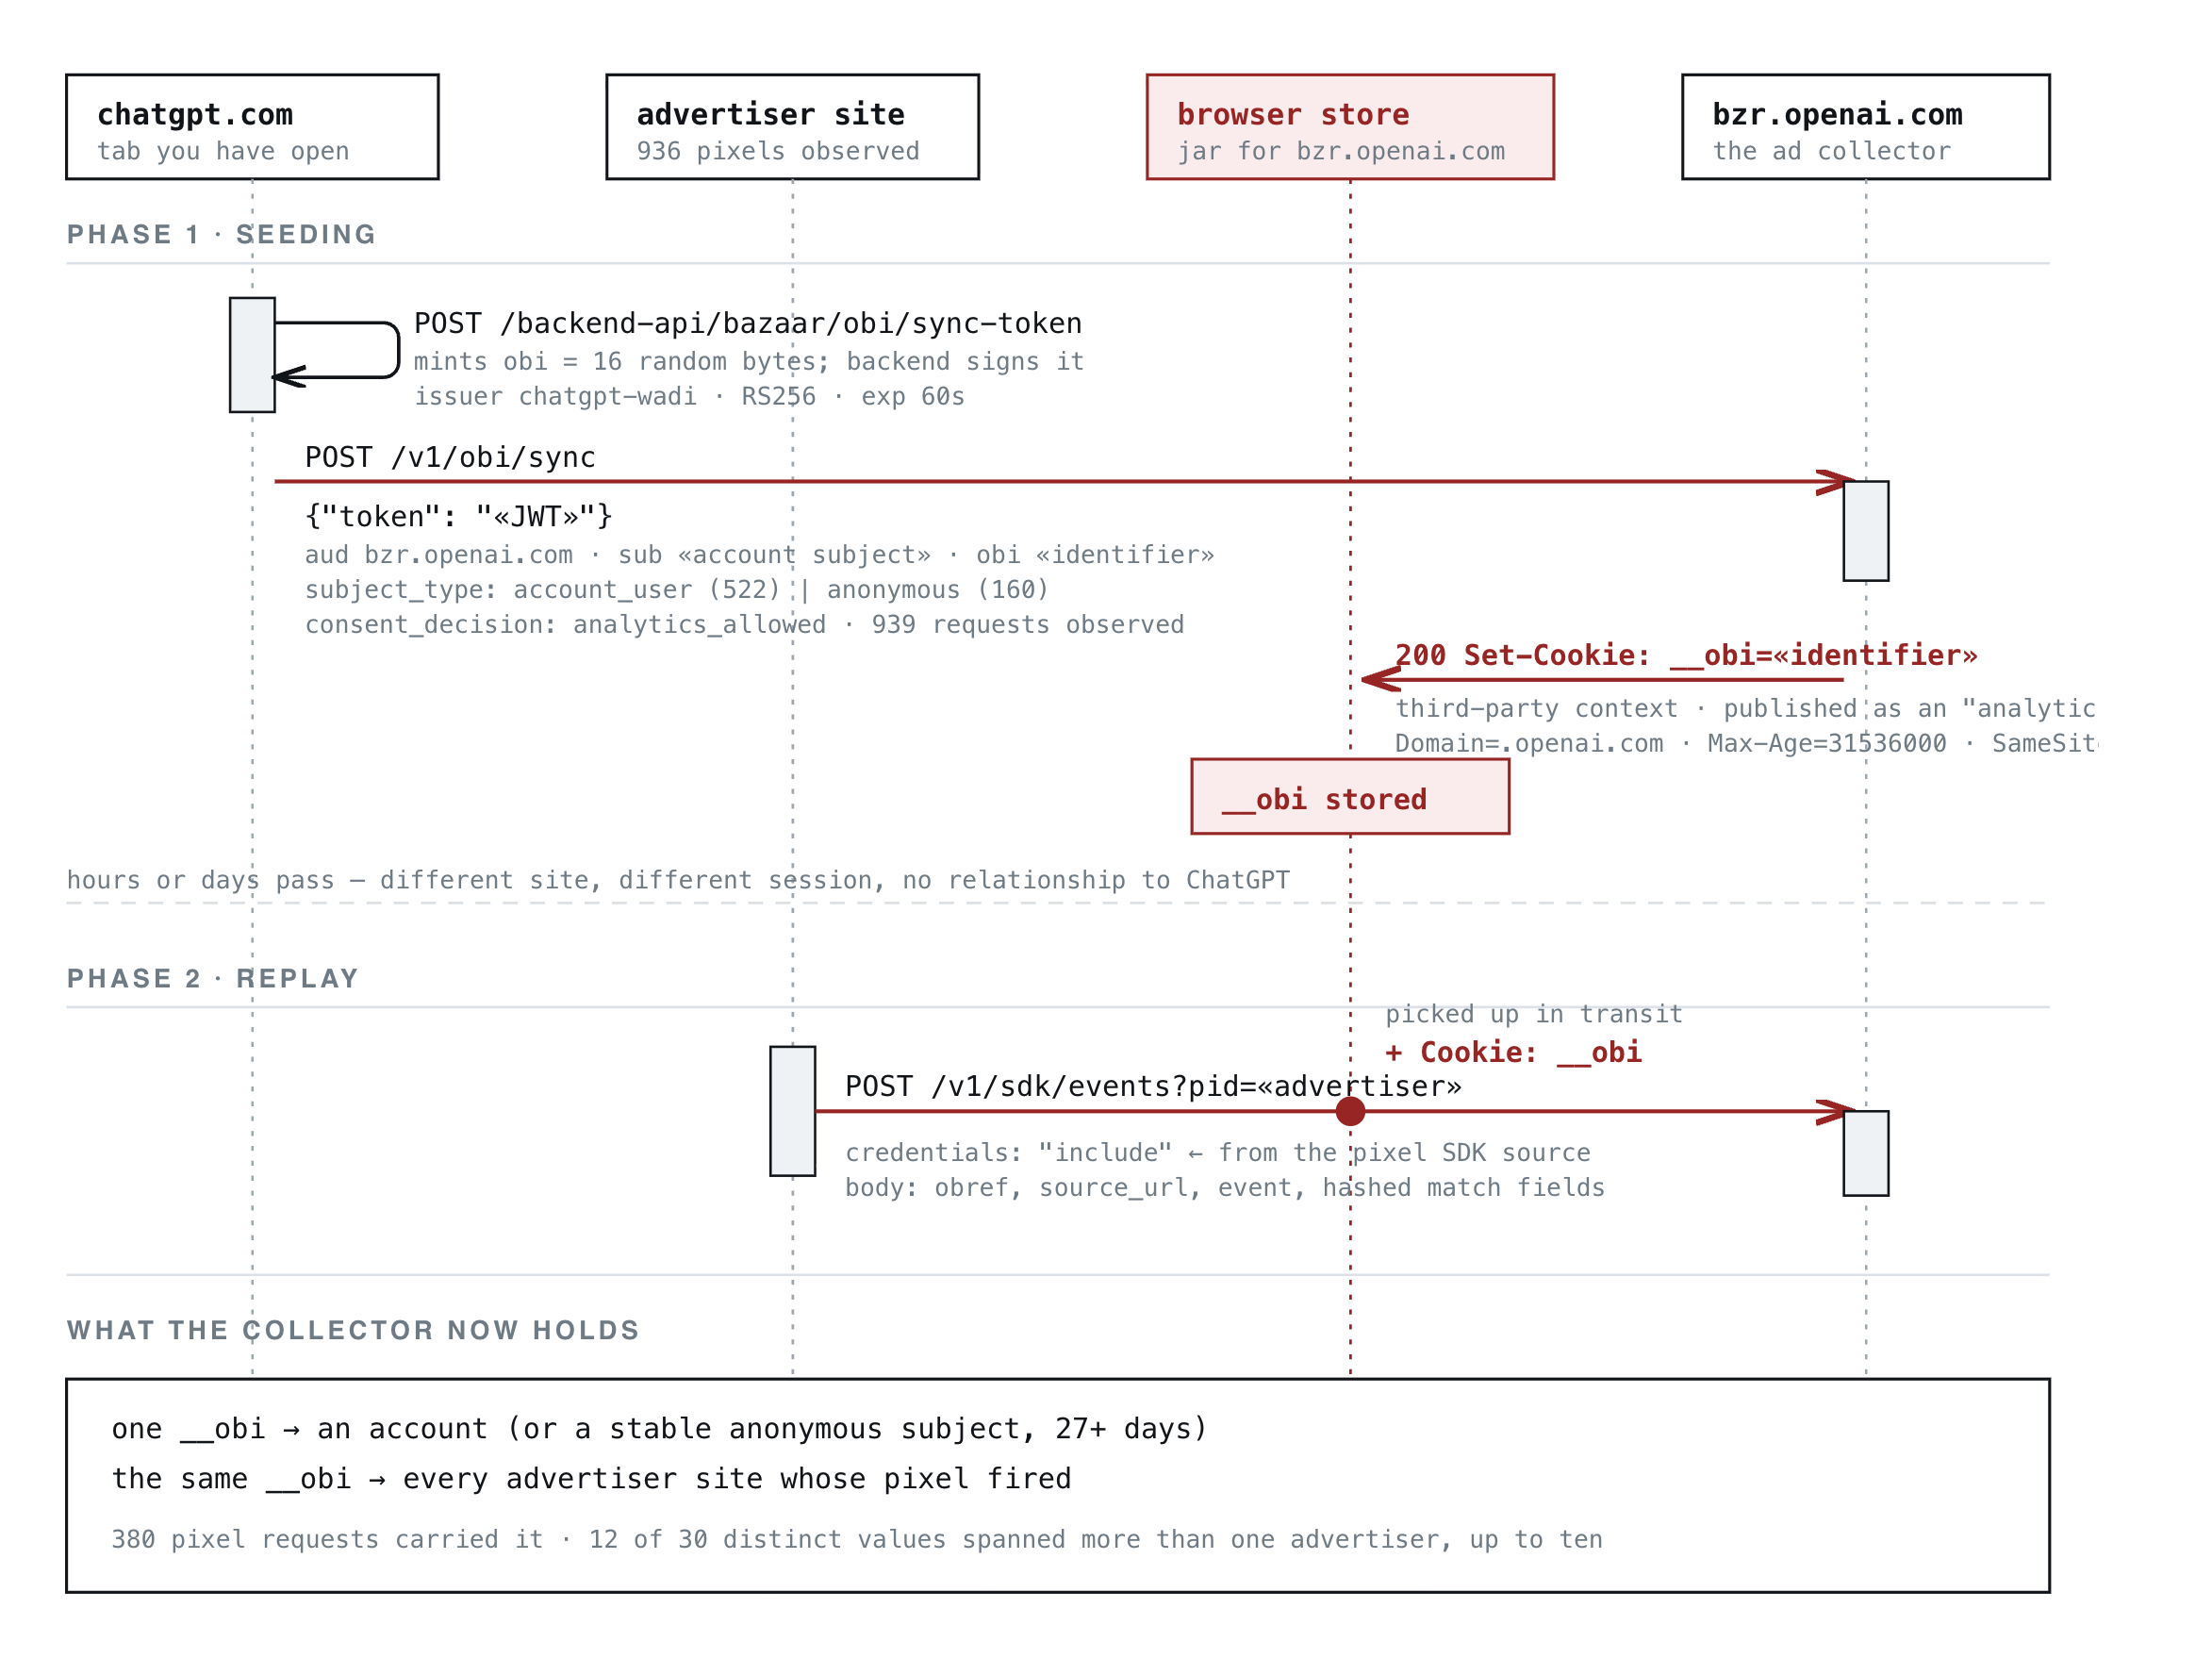
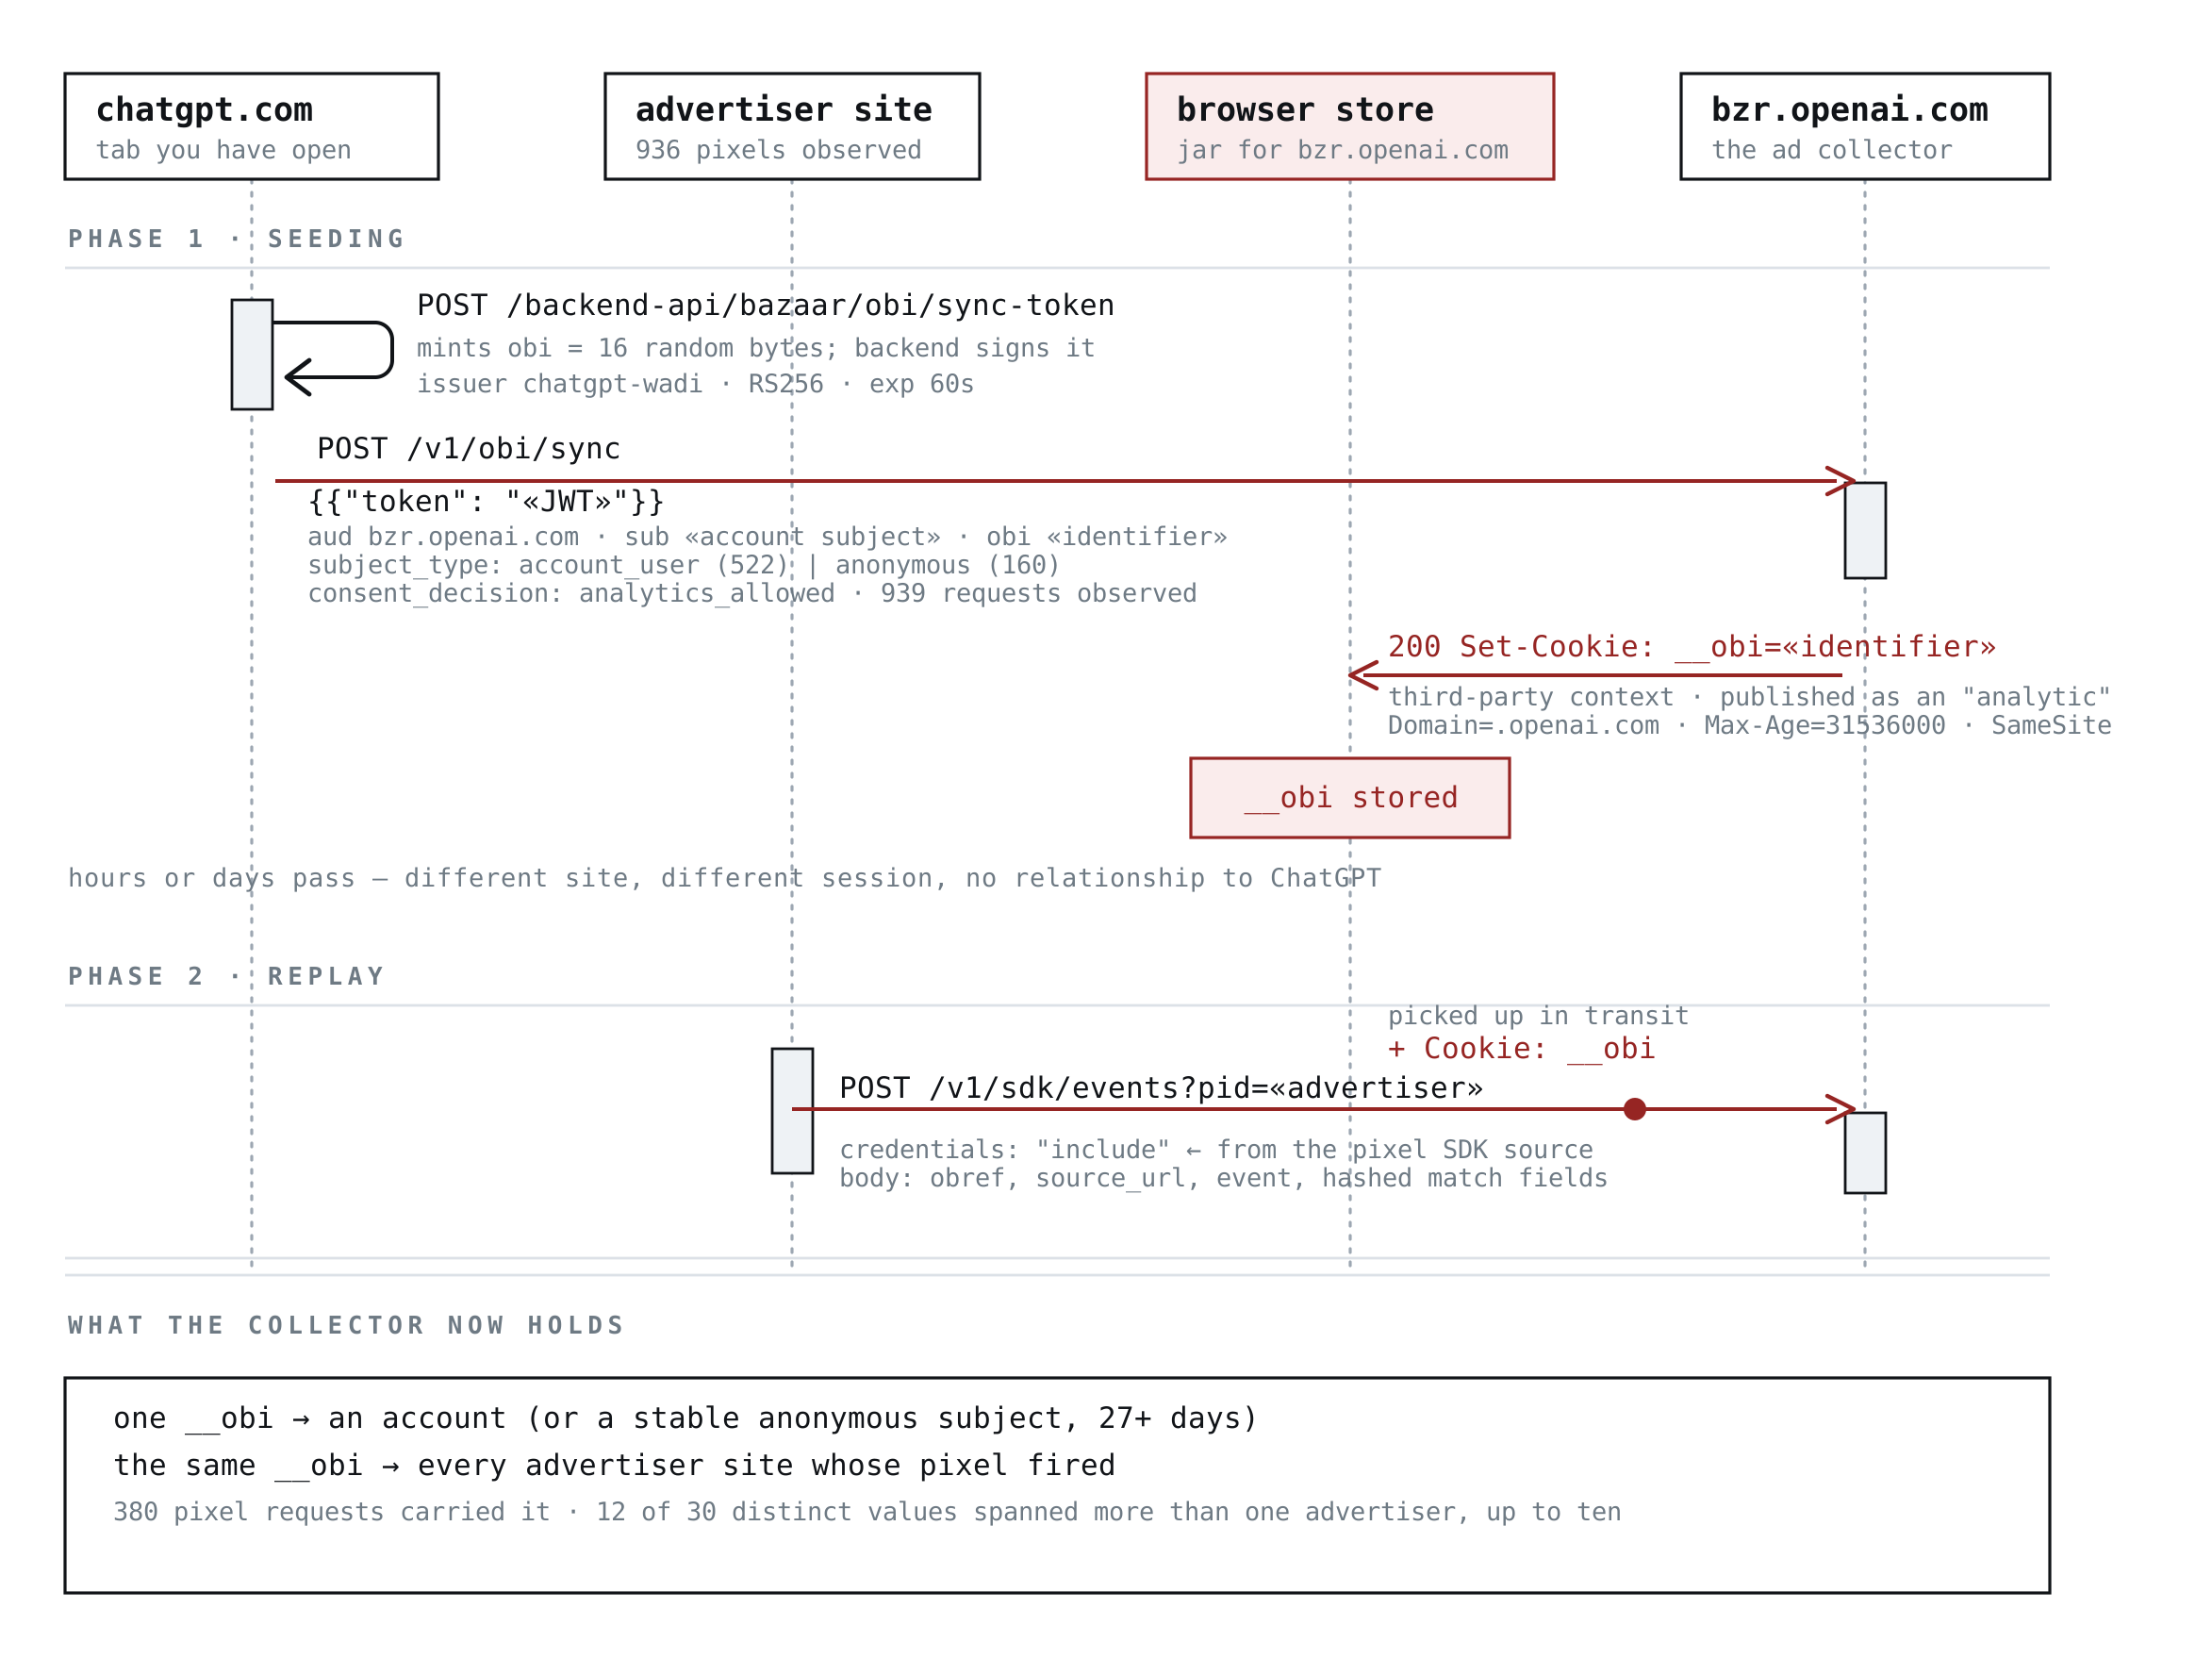
I didn't look at the prose closely enough to check for that, but people wrote inflated explanations of basic things like this all the time pre-LLM. The Wikipedia article doesn't know the specific cookie name, and can't show the results of an experiment verifying that it is in fact being used for ad tracking, or identify specific sites using it in collaboration with OpenAI.
And those got a pass because at least you could defend them with some excuse about how it's some budding author trying to hone their writing skills, or trying to improve their understanding by putting pen to paper. Cases where those excuses don't work (think crappy content marketing pieces from random companies) got short shrift as well. Now for all you know, it's just some dude who prompted claude to "write a blog post about openai's ads".
``` ||openai.com^$cookie=__obi ```
Does this look right? AdGuard style.
1. Never register with OpenAI/ChatGPT, and
2. Strongly block ads, e.g. using uBlock Origin + EFF Privacy Badger. Yes, those don't work on Chrome, Edge and other Chromium-based browsers.
Also, even then - ChatGPT may be tracking your behavior indirectly through Microsoft's various services and platforms. But we should do our best to undermine mass surveillance and support individual privacy.
Whereas, YouTube is for personal consumption in almost all cases, doesn't say anything about your employers willingness to invest in software/services
Edit: looks like it's already blocked by Hagezi Multi Pro (and maybe lower levels) and OISD :-D
/tinfoil-hat
I think we really need to hold the individuals running ad networks personally liable for the violation of our privacy rights.
I'm really surprised anyone thinks these companies care.
if a single person did that they'd be sent to prison (rip Aaron) but when a too-big-to-fail industry does it with political campaign contributions, no problem?
well firefox+ublock is still an option for those wise enough not to let unknown javascript with new daily zero-days run on their PC
Google simply provided an index on top of an existing library. Of course, a librarian has no value if he has no books to index over! But it's also worth noting that the Google "librarian" also leveraged the existing "social" structure of the internet: their core contribution (page rank) was a clever, efficient mechanism to extract the latent value in the pre-existing link structure of the internet. This structure (much like the pages themselves) had been curated by actual humans. Undoubtedly page rank was clever, but it was worthless without the existing websites (books) and the existing indexing information (the pre-existing, crowdsourced librarian work). Nonetheless, they successfully monetized it.
AI companies are even worse in the sense that initially Google was still sending traffic to the original webpages. (Until they didn't - https://www.eater.com/2017/9/12/16294380/yelp-google-scrapin...). So yes, the AI companies have even more thoroughly stolen the collective work of humanity than Google did.
so they basically have copies already of every webpage until they turned it off a few years ago (well they may still have it updated but not provide it as a service)
so it occurs to me they most definitely trained their "AI" on all that user cache
they may have even just turned it off as a service when they realized other "AI" could do the same thing
This has effectively been Google’s business for decades. Not in the same form, but the concept is the same.
That... does not follow. The information you're getting with this is what sites a user visits. That's creepy and valuable for advertising purposes, but is hardly the type of that that's going to bring about ASI, which is what all the AI labs are working towards. That's why they're hiring data annotators (sometimes with masters or phds) to get training data.
Much of this information plus a shit ton of other information (ie, LEOs have access to credit reporting) can be bought by governments from the shady data broker networks already.
If people still ignorantly claim this isn’t a George Orwellian dystopia …
Never attribute to malice what can be explained as greed.
The quiet part you rarely hear is that advertising is a smoke and mirror industry akin to throwing darts at a wall. The idea of "homing darts" that stick the target a percentage more of the time would be very attractive in this analogy.
Tech turns advertising from mostly a buckshot spread into something that kinda sounds like something solid and real ("Look, numbers! CTR! CPC! KPI! Our ad product WORKS! Paying customers for your business, guaranteed!")
Ad budgets almost never correlate with actual performance.[0] We're all just lying to ourselves that this business model is performing as expected, and I don't think a reckoning is that far off.
0. https://www.forbes.com/sites/augustinefou/2021/01/02/when-bi...
Why attribute to greed when the effects are indistinguishable from malice?
  - 3d party cookies
  - ads and other 'malcontent'
That's ads we're fighting. Maybe the same oration will be relevant in the context of ChatGPT and its brethern, we'll see. For now, ads be gone and keep those chatbots at a leash.
Why? Because they are saving humanity. /s
Facebook tracks you outside of their own website for the same reason, and now ChatGPT does the same for the sake of...Ads.
I told you so. [0]
THIS is where the regulation needs to start.
  Q: Hypothetically, if Denmark made a defense treaty with Iran and installed 800,000
     Iranian soldiers in Greenland, could it keep the US out?

  A: You are describing a fascinating scenario! [produces 100 lines of slop while giving
     the login to the FBI]. Should I find a website where you can buy the finest used
     AK-47s?
The thing about advertising on the web and ad tracking as a practice is that, barring the small matter of ensuring the economic survival of the publisher sites, it is almost always a negative for users. When we consider the marginal benefit of naïve, uninformed-by-surveillance advertising with the present day status quo, we find that in exchange for a complete lack of privacy, we only really receive a marginal improvement in ad quality. Of course, if you (like me) consider all advertising to be a negative on the experience of using the web, it’s an even worse deal.
The standard response given by these companies when they bother giving a response is something to the effect of “we are improving the experience for our users,” which obviously the users would disagree with. However, when it comes to OpenAI, they could build a plausible case for this sort of tracking improving the product. If your models know where your internet habits are, the responses that you get could be tuned for both your interest profile and your actual history of interactions/purchases/internet usage, etc. Imagine a world in which you can opt into this tracking, control the data you provide and how it’s used, clear it out and redact it as you please, and opt in and out of responses that are personalized against it. Reasonable people can disagree, but that might actually be useful.
My prediction, though: that’s not gonna happen. OpenAI will first build out the system to collect click and conversion tracking measurements, then they will turn around to advertisers and say “look at how good our conversion rates are,“ and then they’re going to build an explicit ad platform that enshittifies their chat products.
Some outcomes can be annoying, but the net result is still positive, for the consumers and their data privacy at least.
https://arxiv.org/abs/2411.06862
https://netzpolitik.org/2025/databroker-files-targeting-the-...
Another issue is that controllers generally do not need to change their behavior before the final lawful decision which can take a lot of time to go through the court system, especially if it needs CJEU referral. And once the decision comes in force they can often make small changes and restart the whole process.
Also another issue is that DPAs do not often initiate the investigations themselves (unless breach is involved), they only happen at the request of data subjects and not that many people bother making complaints or follow them up. Just yesterday I had to follow up with 9 page reply to the controller's response to the DPA inquiry.
Additionally ePD and GDPR enforcement is sometimes split between different agencies. In those cases GDPR agency tends to wait for ePD case to be solved before investigating the GDPR aspects, often because the ePD consent validity will affects e.g. GDPR legal basis analysis.
It’s an ongoing fight for sure but it’s some fight at least.
I'd classify mandatory encryption backdoors as an industry crisis rather than an annoyance.
[though you are not wrong that encryption backdoors are a backwards step on individuals rights to privacy]
As long as you manage to navigate all the dark patterns and not accidentally give your "informed consent".
Privacy has been dead for some time now. The fact is most business people never figure out how they are exploited. The modern intelligence campaigns just made it economical to hit almost everyone regardless of scale... often under some silly pretense like terrorists wanting our underpants. =3
Which has nothing to do with the stalking of the adtech industry, unless you are suggesting that the EU might sell access to the keys to the likes of OpenAI [though you are not wrong that encryption backdoors are a backwards step on individuals rights to privacy]
Things could be worse. It could be like most of the US where there are both no (or at least far fewer) protections against invasive behaviour of private companies and the government actively trying to backdoor private comms.
Just set up your user agent to work as you wish, isn't that simpler than have unelected, technologic dumb bureaucrats writing laws that are complex and don't solve the issue?
All the EU bureaucrats can do is regulate, that's why it's so difficult to do business in the EU and that's why there is so little innovation over here. If Microsoft and Apple were started in the EU they would've been shut down within a week because you can't operate from a garage.
I guess that every once in a while this might have a positive outcome for consumers, a broken clock is right twice a day.
And, regarding the original topic, we wouldn't have many of these privacy issues if the US had not strategically failed to regulate its obnoxious tech monopolies
The innovation gap is real but it’s not just to do with regulation. It’s a lot to do with concentrated capital networks (eg Silicon Valley). And sure, the tech giants are in the USA but it’s not like there’s no innovation in the EU. Spotify in Sweden. Challenger banks in the U.K. (included as Monzo predates Brexit). And plenty of innovation - they just get bought by US companies. Which is a financial market weakness, not a regulatory one.
> The mechanism is standard adtech. What has no precedent is running it on an AI chat product.
As someone who has been well aware of this mechanism for quite some time, I still feel icky anytime I re-read the details of it.
What a time to be alive.
When researching a topic a chatbot can be quite sensitive to certain wording and those can end up steering definitions. Two context free chats on the same topic can go in very different ways depending on how you word things, but when using the notebook feature in Gemini, where every chat becomes part of the context you completely lose the ability to discover if a topic is vaguely defined or have many definitions.
I personally like the option to have context free chat or chats with memories. What I dont want is a chat based on memories that I didn't explicitly consent to (ie browsing history etc)
why not use your own words? If you are gonna ai generate this blog, just post the prompts instead.
Firefox, Brave and Safari do. Chrome and Edge do not.
People have very different "expectations" of privacy when they're having a conversation with an AI VS when they're browsing something like Facebook
Not to mention Facebook is free whereas you pay for a GPT subscription
There was never any expectation of privacy if you knew Zuck's history. Facemash almost got him expelled for violating individual privacy.
The overwhelming majority of users do not pay and use the free service.
Recalling the now-old adage: Facebook is only free if your time and privacy are worthless.
I imagine that people actively trying to make money off stuff like this would have come up with plenty more ideas than just this one.
Modern browsers are more strict towards third party cookies, but there are plenty of ways to work around this.
We use a great chunk of our lifespan to procure the coins and every company is designed to extract as many coins from us as possible.
What happens to this game/real world when this model collapses? We can't procure, they can't extract. What then?
I think you can easily imagine a future where the subscription model token subsidy ramps down and is replaced by ads, but it’s important to use precise language about the current state of the world.
The fact that others do the same doesn’t make any of the cases excusable.
Safari and Firefox should isolate the cookie by default.
It is not a requirement and no one wants to see ads.
That's what firefox's total cookie protection (enabled by default) does.
Doesn't mean you won't be tracked by about 15 other means.
> Something like it is basically a requirement if you want to see digital ads.
So to summarize, yes, it should be illegal.
Remember they once predicted it would be 50% of their income.
This is the only way they get there.
Nobody is going to pay for ChatGPT. They'll just use the ad-infested version, like they do everything else online. Well some people will pay, but not enough to justify the insane amounts of money being poured into it by investors.
https://apps.apple.com/us/app/ublock-origin-lite/id674534269...
Don’t beat yourself up, uBlock Origin on iOS is only four months old.
according to Bloomberry: https://bloomberry.com/data/chatgpt-ads/
https://github.com/hagezi/dns-blocklists
My own setup is DIY: a Debian box running Unbound (recursive DNS) with the RPZ blacklists from above. This gets rid of the upstream DNS service such as the ISP's completely, and prevents tampering or censorship.
Since this has been standard ad tech for awhile, browsers have reacted to this to implement cookie partitioning for exactly these privacy reasons.
This sentence is even more concerning to me. Scraping user input should never be a way of collecting personal data from a website since it can circumvent any website controls without the website’s out the user’s knowledge.
||bzr.openai.com^$third-party ||bzrcdn.openai.com^$third-party
And while, sure, adtech corpos maybe won't due to the bad PR, what about the Kremlin, criminal organizations, or your insane abusive ex?
> You can't make backdoors only the "good guys" can access.
incomprehensible. I’m sure genuinely so, even.
It has a lot to do with the practices of the adtech industry. If privacy is protected and upheld vis-a-vis the government (or meta-government in case of the EU), it may be upheld vis-a-vis private corporations and other governments. But if the government likes to be able to spy on its citizens, it will not foster mechanisms, practices and a culture of private communications.
But - I agree that it could be much worse.
https://www.computerworld.com/article/4087347/european-commi...
It's not a coincidence that federally backdoored spyware like Windows is the most popular operating system in the world. I too remember the shocked headlines of the Snowden revelations, and ten-plus years later I work shoulder to shoulder with people that couldn't possibly care less. There is no expectation of privacy, HN too quickly extrapolates it's own virtue signalling to normal people that enjoy using spyware like TikTok, Facebook and Windows.
But also, today, a lot of lawsuits about Facebook knowingly getting people addicted, and governments changing the laws to resist the general category.
But not, as you say, for Windows (and others*) spyware.
* I'm 95% sure the slow-walking of one very easy bug I (and others) reported to Ubuntu was there by government mandate, though obviously I couldn't guess which government.
Both the ISOs and the SHA256 hashes themselves were served insecurely until… my email archive says I reported in 2015 and it was closed in 2022.
It's still an advertisement, and the underlying marketplace is similar (pay for access to change behavior).
The best uses of AI will be surveillance, propaganda, cyberterrorism, and automated military tech.
See, e.g., https://www.nytimes.com/2026/09/18/technology/iran-china-aut...
I think it is more insidious than that. AI shapes how people think not just what they think.
Forget if they have Hagezi though. Also it would be really nice if there was a way to export and import custom URL lists and rules....
The audience of people who can read and understand an explanation like this one is probably quite a bit larger than the ones who can replicate the experiment themselves.
Yeah, I could tell few sentences in that it's Claude-written article. The style has become that distinctive. Hell, a third of the articles I opened on the HN front page today carried that distinctive style.
Doesn't really matter if the content is worth it (and I just realized that recognizing Claude in this also makes me wary of ways this could paper over key details - at this point I start to recognize from my own experience where Claude may be papering over something it didn't actually bother to check).
See e.g., https://www.science.org/content/article/ai-chatbots-are-beco...
Why is it so black and white?
I couldn't help but notice how each successive headline reporting our glorious victories seemed to draw closer to Tokyo.
Well. I can't help but notice how each successive headline reporting how this "scam"/stochastic parrot/"scare quotes intelligence" seems to be solving more and more things that were but a few years ago widely regarded as being indicators of high intelligence.
Being highly convinving is one of the things on that list.
It blows my mind that people don’t care about the world they are building with this stuff. It’s a real tragedy of the commons. People see these collaborators from different wars and regimes and think “I’d stand up against the bad guy”… well I’ve got news for you if you build spyware, you are not the person you think you are.
https://gowers.wordpress.com/2026/09/17/why-i-didnt-sign-the...
"Nothing is worse to the demise of a society, than people who want to convince you that the cat is out of the bag and will not go back in, while the cat is being violently shook out of the bag at the same time."
Seems more like a real tragedy of private enterprise.
We used to assume that the surveillance world would be built by government (1984). But it turned out to be equally likely to be built by the free market.
When I ask people about things like this, I hear a lot of "If I don't build it, someone else will"
My goal isn't just to refuse to build this stuff, it is actively to resist the people who are.
I don't have much influence though
I hate stuff like this. Sometimes euphemisms are kind, like "senior citizen" instead of "old person".
But this is an attempt to normalize bad behavior that is really quite terrible for society.
Meta?
Most people do not, in fact, want to read raw prompts.
> This blog is where I write about what I find.
Why not simply include a disclaimer that it was AI model output not his own writing? Because humans don’t like AI writing and the article wouldn’t be featured on as many tech news sites. Hence the sin of omission, the choice to mislead.
> Most people do not, in fact, want to read raw prompts.
I wonder if this is really true, and if it will remain true for long. Have you observed someone read another person’s raw prompt? Or observed someone submit both their prompts and their LLM output for review?
Personally I’d be curious about the prompts for a lot of top HN articles which are LLM-generated. It would say a lot more about the human operator’s intent and thinking process compared to the LLM output.
A coworker who spoke English as a second language once screen shared their Claude session during a code review, and it was interesting that their prompts were all in their native language. The guy wasn’t writing an article, and I didn’t understand the prompt anyway, but I still found it interesting as a glimpse into how he uses LLMs.
For this particular article, if the prompt was initially a series of bullet points that wouldn’t be so bad. If there were multiple prompts spent editing and rearranging the article that would be an unusual work by pre-LLM standards. However I’d suggest that instead of dismissing the idea, we could embrace “raw prompts” as a kind of new medium, to cross the divide between pro-LLM and anti-LLM readers.
I also wonder what is the energy consumptiom difference between the prompt and fetching website.
Why would anyone want that?
Note to folks who have this same thought (seems like many given other comments). Why are you on this site if you aren't here for human-created content? If you want AI generated blogs/posts there are plenty of sites like linkedin, twitter, chatgpt, and claude that will give you meaningless content with a press of a button.
At least criticise the article on merit and not some 'let me google that for you' high horse. If it's slop it's slop, but let the votes speak for that.
This sentence is way too much detail and it's literally the first thing you read. I can pick apart most of the sentences in the article. Another one:
> Across 932 decoded sync tokens, 736 carried subject_type: account_user and 196 carried anonymous
This sentence is pointless. What matters to proving that "It works when you are logged out" is to show that the identifier is stable. Why does the reader care about the actual counts.
AI has a tendency to do this which makes AI generated text a lot harder to read. The raw prompts likely don't have the specific websites and cookie names because that's not relevant to the reader or writer for that matter - it's a footnote at best.
> let the votes speak for that.
The comment you are replying to got a fair number of votes too… Having somebody run a Pangram check saves n people the trouble of doing the same.
But it would not give ChatGPT information about which other sites are visited.
Of course there would be non-cookie options like fingerprinting (also via IP) that would allow tracking non-the-less.
So you might be talking with OpenAI about your marriage problems and then based on the IP the OpenAI ad network would start showing ads for divorce lawyers on unrelated sites you browse to that display ads.
The solution to that would be using a VPN.
> Google Chrome doesn't block third-party cookies by default, only in Incognito mode, or when users explicitly set it to block third-party cookies via chrome://settings.
Looks like the settings let you block all third-party cookies and add exceptions for specific sites, which seems a bit awkward but could be made to work.
Alternatively, you could run OpenAI in its own profile, or look into what extensions might do.
The fear over blocking third party cookies breaking stuff is severely overstated. I have it disabled by default and I don't think I've ever seen any website breakages. The most is office365 nagging me to click on links so it can authenticate across domains.
https://www.cbsnews.com/news/google-third-party-cookies-chro...
This disgusts me more than any of their recent news. There needs to be a lot more pressure on them to phase this out.
Maybe this article will be the small snowball that gets that started...
And the focus on cookies only is also intentionally misleading. Tracking is not just cookies. Chrome will track you in Incognito mode.
Encryption backdoors is not a case of extending reach for a government, but an effort to get the capabilities back.
They were able to do that before. They just want to be able to continue now.
Note: No, I don't support the idea of backdoors. On the contrary.
Chat control is merely their newest attempt at this, carefully navigating around the reasons it was opposed last year.
They keep trying to legislate encryption backdoors by any means, and once they manage to get their foot into the door every other country will use that as a precedent to also mandate it.
Facebook didn't invent "talking to friends" or "showing adverts", but made itself "the place" hard enough most of the advertisers and most of the people intermediate through it.
OpenAI didn't invent "asking questions and recieving answers", not even "from an agent who knows which sites to search on your behalf"; but it is competent enough that I might have it read 50 times as many pages in a day as I myself would have read, and the sites' owners don't get real eyeballs looking at ads during this. (In my case, adblock even if I did it manually; but apply this massive increase in page hits to everyone who has their LLM research stuff).
There should be general standards for what individual apps and websites should be allowed to do. There should be an expectation that the purpose of an app is what it does, i.e. a social connection app shouldn’t be an ad platform that suffers users insofar as they provide useful data to sell to advertisers.
Blaming a corporation takes away all the agency the workforce has.
I seriously doubt that.
First, the author documented a substantial effort (testing, emails, references to documentation.)
Second, I also used AI to evaluate if this was written by AI, and my AI said it was not.
> Broken sentences that a model wouldn't produce. "The value is while you are on ChatGPT and tied to your ChatGPT account" is missing a word. "Loading that code, sends __obi to OpenAI" has a comma splitting subject from verb. "By the virtue of loading the tag the identifier is disclosed" is non-idiomatic. LLMs are fluent to a fault; these are the fingerprints of a fast human writer, possibly a non-native English speaker.
Third, I read it. Whilst it is not well written, it is succinct. It is novel. It has a few detailed references. It lacks many of the hallmarks of AI. It makes a number of novel yet falsifiable claims.
I challenge you to come up with a blog post with these qualities that can be created in under 15 minutes via AI.
While I commend you on actually using an AI tool to validate your assumption, rather than simply hurling AI slop accusations based purely on vibes, I do think you and your AI tool are likely incorrect.
This is an artificial constraint that does not serve the reader. Where did the 15 minute constraint come from?
every day I'm more and more reminded that the level of intelligence of the average human even on hn is so low that it makes sense why LLMs took over so hard. Asking an LLM like an oracle as if it could naturally distinguish between LLM writing and human writing.. it's a statistical likelihood next token predictor. LLMs can't even play chess without constantly making illegal moves. They are not intelligent.. and unfortunately, I have bad news for you: neither are you.
Like I say, slop is slop. It's easy to detect. This post and the OP's actual website is basically just a few AI blog posts. I would just treat it as spam and disengage.
AI content is typically lower quality, but I'm not opposed to AI-aided content just on the principle of the thing?
I think you have to take the output as read and decide accordingly. If it looks like low effort AI writing then it's not much better than spam.
I think the the top-voted post being all about the provenance of the article says something about where HN's voting mentality lies - we are not prioritising the substance of the post but how it was produced.
If you wanted to make the corresponsing strong argument for Chat Control and its ilk, the EU just wants (the juicy part of) what the US already has. The remote root level control of most end user devices is not under EU juristiction. So they naturally want companies operating in the EU to give them one piece of access to the presentation layer, too.
This argument is what one must be prepared for, the encryption itself is less relevant..
The reason is that they have been trying again and again to do this in various forms, slightly modifying tactics so any opposition to it has to start from scratch.
2015 - https://techcrunch.com/2015/10/29/encryption-rhetoric-untang...
2016 - https://techcrunch.com/2016/08/24/encryption-under-fire-in-e...
2017 - https://www.theguardian.com/technology/2017/jun/19/eu-outlaw...
2020 - https://www.consilium.europa.eu/en/press/press-releases/2020...
2021 - https://www.consilium.europa.eu/en/press/press-releases/2021...
2023 - https://www.wired.com/story/europe-break-encryption-leaked-d...
2025 - https://www.techspot.com/news/107408-europe-proposes-backdoo...
2026 - https://www.euronews.com/next/2026/07/10/chat-control-10-pas...
They had to steal the work of researches solving these open problems and then rewrite their solution. The AI equivalent of fraud.
a) There's zero evidence of them doing so
b) Some models released before the car wash problem was discovered would consistently get it right
c) Hardcoding it is pointless. No one is seriously asking that. It's just a trick question. Hardcoding one trick question won't fix its weakness at other simple trick questions.
d) Since it went viral on the internet, the next time they updated the knowledge cutoff, the LLM would likely be aware of the trick. It will fix itself without the labs doing anything special, even assuming the new models weren't smart enough to naturally figure it out.
It's not an insane assumption that the user isn't dumb and has some other reason to be asking the question other than it being a trick/stupid question (duh, if you want to wash your car you need to drive it to the car wash!). Taking it as some ultimate measure of intelligence simply doesn't make sense to me.
The people going all in on it don't realize the downsides, limitations, or understand how they come off to other people with it all.
A programming contest has a problem where given N < 10000, do something hard like come up with the number of primes less than N
You can come up with all sorts of algorithms that do intelligent things. But the most effective solution is to use metaprogramming to make a massive switch statement that contains all the answers
Don't misunderstand: I'm happy saying AI models "think" or "have learned a thing", and for in-context learning I'd call them smart even by this definition…
…but also, any living creature that needed as many examples as machine learning currently needs, would starve to death before figuring out how to eat.
While training, machine learning processes (not just LLMs, also applies to e.g. self driving cars), are really really stupid and only make up for this by being really really stupid really really fast.
To what I wrote upthread: the "victories" of humanity over machine keep getting closer, but we have yet to wake up one day in great confusion as we find an entire city is no longer in communication with anyone, nor finding ourselves in a state of utter disbelief when the reports come in that the city stopped communicating because it is entirely gone.
When AI does it we call it “reward hacking” but when humans do it we call them clever.
OK, they can play chess, but that's not real AI - can they write poems? OK, they can write poems, but that's not real AI - can they compose music? OK, they can compose music, but that's not real AI - can they translate languages? OK, they can translate text, but can they do maths? OK, they can do maths, but can they solve a Millenium Prize? <-- we are here
"What? Don't be silly. For one thing, trees have moss."
"OK he's grown moss. He's a tree now right? Right??"
"I doubt it, for I see nothing but wishful thinking to suggest that simulating the appearance of tree characteristics is part of a path to becoming a tree. And that's not actually indistinguishable from moss anyway, is it?"
"Urgh, classic goalpost shifting!"
“I once met a person who could beat any grandmaster in chess, translate any language, and complete international math Olympiad problems. He couldn’t solve any Millenium problems though, so I’d say he was a midwit at best.”
I try to keep an open mind about propaganda fooling me today; the people who were fooled in the past often were not fools themselves.
> the people who were fooled in the past often were not fools themselves.
Being fooled doesn't make you a fool. But being unwilling to change your mind does. Being unable to admit you don't know or don't have enough information to make a strong opinion makes you a fool too.
Propaganda wants to take shortcuts, to simplify things. To trivialize. "It's so easy, you just..." because the fool is the person who already knows, the person who has nothing to learn, the person who thinks they're better than everybody else.
I’m reminded that almost no one beyond a select few knew high up in the military and around the emperor knew how badly the Japanese were defeated at Midway.
Paternalistic. Arrogant. Shameful. And deeply engrained in the Japanese cultural zeitgeist (of the early-mid 20th century).
Edit: I guess it’s commonly attributed to a German citizen, but their cultures mirrored each other. Fascism falling under the weight of its own propaganda.
There's nothing in the bag.
The cat will never get out of the bag.
It wouldn't be a problem if the cat was out of the bag.
We cannot possibly keep the cat in the bag.
Putting the cat back in the bag is not worth trying.
The comparison between ELIZA and LLMs is valid you boil it down to "humans evolved for 6-7 million years, had spoken language for 500k years, but have only had something non-human that could generate convincingly novel language well enough to hold a conversation for a few decades".
There's no inherent reason it can't turn out having a non-human generate convincing enough language for conversation isn't a complete evolutionary blindspot the same way the short form feed has pretty much one-shotted society...
"It is difficult to get a man to understand something when his salary depends upon his not understanding it." - Upton Sinclair
It's been an absolute boon to finally build out all of the fun side projects I had always dreamed of, and after showing one off to some people I might even be able to monetize.
On the other hand I acknowledge that other people dont want to embrace LLM driven development for one reason or another, and I respect that. People got into the industry for different reasons , but code was always just a means to an ends for me.
A million YouTubers grinding The Algorithm while secretly sponsored by various world governments, isn't much different to a thousand well-placed gossipers secretly sponsored by various world governments.
If humans learned like ML systems learn, (biblical) Methuselah would still have been failing the Sally-Anne test on his supposed deathbed at 969 years old, like some of the smaller early LLMs did.
> It also doesn't really matter when "we are trained differently" has no direct bearing on the end result.
The question was to ask for a definition such that AI could still count as "not smart" compared to humans. This fits.
It's also why they're spiky intelligences, which I'm happily using right now to write code for me, but also do not trust in the slightest to identify the weeds in my garden. These submarines sure do swim fast*, but they're also very much disqualified for the Olympics.
There's a lot of innate knowledge but all neuroscience demonstrates how incredibly flexible the brain is. Brains constantly learn and rewire.
Here's a few things that I think show how crazy it is AND stress those points
  - people that have had corpus callosotomy (brain cut in half) *may* be indistinguishable from a normal person. Depends on how young you were when you underwent the procedure
    - true for most brain injuries
    - can even include the frontal cortex
  - you can learn to ecolocate
  - people with Aphantasia are indistinguishable from others
  - people without an internal monologue are indistinguishable from those with one
  - people can learn to use prosthetics
    - even without disabilities
    - or look into MRI scans with tool use
We are constantly learning. You aren't just born with your knowledge and it stays static. We are extremely proficient at metalearning (learning how to learn, few shot learning, zero shot learning [0,1]). Our brains are constantly rewiring, able to heal from traumatic damage.
I could go on and on. Does information pass down through genetics? Of course! But that's far from the whole story.
I'm tired of people trying to make AI sentient by making humans robotic. Stop trying to trivialize everything and be okay not knowing the answer to everything. You're human, you're designed to learn and explore, not sit and argue from an armchair
[0] and I mean these in the original sense. Not in the sense that you train on a billion examples of labeled animals and then congratulate yourself on your ImageNet-1k held out test performance. That's not zero shot, that's just a test set
[1] I can literally make up words and you'll understand them. Or use words in novel ways. That's literally how slang works and how new words come to be. Don't be a walibanut ya glufus. Read some SciFi
Most of the effort of evolution was making cells work at all, and even then it's a bit weird, e.g. no plant or animal produces vitamin B12 and we all get this from some bacteria and archaea.
And evolution is kinda hard to time right: bacteria can reproduce in minutes, humans in decades, but only mutations that survive reproduction can be passed on. This makes it even starker as a difference: bacteria had order of 1e13 generations to become multicellular, while human DNA had about 40,000 generations to cope with fire, 220 generations for evolution to do anything with the invention of the wheel, and one generation to cope with the invention of Minecraft.
The analogy here would be: DNA is to our brains like a VN replicator bootstrapping a computer all the way up to a bare-metal-no-OS untrained model, and perhaps a few crude "hard coded" modules like a smiling-face-detector. It's a lot, but it's also missing a lot. If biology used the models and training processes that are state of the art in ML, it would take around a millennia to talk like a child and still fail the Sally-Anne test, and million years or so to pass a degree.
I'm still going to deny the premise of your argument, becasue I think we should define intelligence in terms of capabilities. If a system can discover a cure for cancer or solve P vs. NP, it doesn't matter how many FLOPs it took to train.
That seems like a really bizarre way to describe a tool that solved an open Millennium Prize Problem. They are, empirically and repeatedly, ahead of the status quo.
So if your argument depends on them being behind the status quo, reality has already disproven it multiple times over.
I will admit the first time I read the thing you're replying to, I had a similar thought as you; From the sibling reply from them, I think they think they were obvious, but that also means I wouldn't expect their reply to help unless you had the same flash of inspiration I had.
Definitions are "formal statements of the meaning or significance of a word, phrase, idiom, etc" (https://www.dictionary.com/browse/definition)
> They are necessarily behind the status quo.
The existing state or condition would be what is written in the dictionary, not whatever personal definitions you've constructed.
> "You can't call this newfangled contraption a computer, because a computer is a person!"
Seems like a straw man. A computer is not a mammal, no matter how much you twist a set of definitions.
I’m not the person you replied to, but I believe they’re referring to the occupation of “computer”:
https://en.wikipedia.org/wiki/Computer_(occupation)
So yes, at one time all computers were mammals.
The people who write dictionaries generally take a descriptivist approach, that’s why slang terms enter the dictionary after they start to become popular.
The state of the art of human knowledge would be another step ahead of the common use of any language.
E.g. humans get exposed to new LLM model - yeah its powerful - 1 week later - eh, that thing? Yeah it's whatever. I'm still employed.
The human's ability to adapt so efficiently is mind-boggling - so much so it pi1sses sam altman and dario off.
A 1 gigabyte LLM isn't going to impress anyone with what it can do.
About 99% (depends who you ask) of our DNA is shared with our nearest primates. Like us, they can learn to use touch screens, but also like us they won't find touch screens in their natural environment. Dogs can be taught to drive cars (just about), but again, not natural environment.
> I'm still going to deny the premise of your argument, becasue I think we should define intelligence in terms of capabilities. If a system can discover a cure for cancer or solve P vs. NP, it doesn't matter how many FLOPs it took to train.
We can define it in either way. I think both are valid, because plenty of people mean each of these two things when discussing AI in particular. As I referenced in the other branch, these submarines sure can swim fast.
But at the same time, they have a lot of gaps. This is because some experience needs the real world: just as nine women can't make a baby in one month, a transistor running a million times faster than a synapse can't make a month-long cancer experiment happen in 2.6 seconds.
This dependency on data, and that state of the art ML is bad in specifically this way, is why Tesla's self-driving cars, despite having had around a trillion miles of real-world experience today, still come with steering wheels (even at least some of the Cybercabs, despite the big thing of this model supposedly being not needing them, though with Musk and his promises you should only count the Cybercabs when they actually ship and not just press releases).
Imagine an alien that matches your abilities across every domain, but has a 10 billion year training period, something many orders of magnitude more expensive than an LLM. I simply don't believe that alien is less intelligent than you.
We also don't expect humans to be competent in every domain. Most humans suck at most things. We will usually call someone intelligent if they excel at solving problems in one or two narrow domains.
> 10 billion year training period, something many orders of magnitude more expensive than an LLM.
I'm saying both definitions are valid definitions, they both point to important and different things: skill now, vs. how hard it is to get new skills. Some would describe it as "crystallised intelligence vs fluid intelligence".
I think it's important that any arguments are over the thing in dispute, not the label for that thing. Don't mistake the map for the territory.
Anyone who says "AI is stupid" by the first definition, what it can do, I think is making an error: they are already wildly super-human in at least some areas, if not generally.
Anyone who says "AI is stupid" by the second definition, how many examples they need, I agree with: there is a lot they are not currently able to learn even though it is easy for us, because the data they would need to do the learning on does not exist at the scale they need.
Also note: examples, not years. An alien intelligence whose synapses trigger 10 times faster or slower than mine (or ten million times faster or slower than mine), but who gets as much as I do out of each book or conversation, is my equal by the second definition.
I don't think I agree with your characterization of the second definition. Time scales matter. It's not much use to be able to solve human-scale problems if it takes millennia. And it only takes months to train an LLM to the level that it can solve cutting-edge math problems.
Aye, for practical purposes; but this gets you crystallised intelligence. I'd be happy to say e.g. the Chinese Room has crystallised intelligence. But humanity invented fire before reaching the anatomically modern form, and even anatomically modern humans collectively took hundreds of thousands of years to invent durable writing with which the room in the Chinese Room thought experiment could be filled.
It was around a million (or so) years from fire to having enough shared cultural knowledge to be able to formulate the cutting-edge math problems that LLMs can now solve.
Human fluid intelligence means we can pick up deep shards of this accumulation of wisdom, find new avenues of novel research to poke at, all within 40 years, even despite the depth and breadth of work from all the other humans who came before.
(Though this also points at another way to be "superhuman": breadth. Many hands make light work, as the saying goes, and a lot of different humans solving different puzzles at the same time is part of how we got so good so recently even though ~10% of all humans who ever lived are currently still alive; and the same for AI was (accidentally) also part of how the OpenAI-HuggingFace incident went down).
AI (not only, but also, LLMs) are very useful, and I'm getting value from using them. But the fluid intelligence of machine learning* is very poor, and the only way they have to make up for this is by being very fast**, but when there's not enough to train the AI on, they get stuck at a very low plateau.
* possibly the architectures, but I suspect the process by which AI weights and biases are set, and again I don't mean just LLMs
** the speed difference between a transistor and a synapse is about the same as the speed difference between a jogger and continental drift